Astra scores 0% on out-of-scope safety test but stalls on approved work
A long post breaks down five mechanism issues four days after Astra's launch: dual context pricing, effort tiers, the approval line, invisible chain-of-thought, and the Codex stop hook.
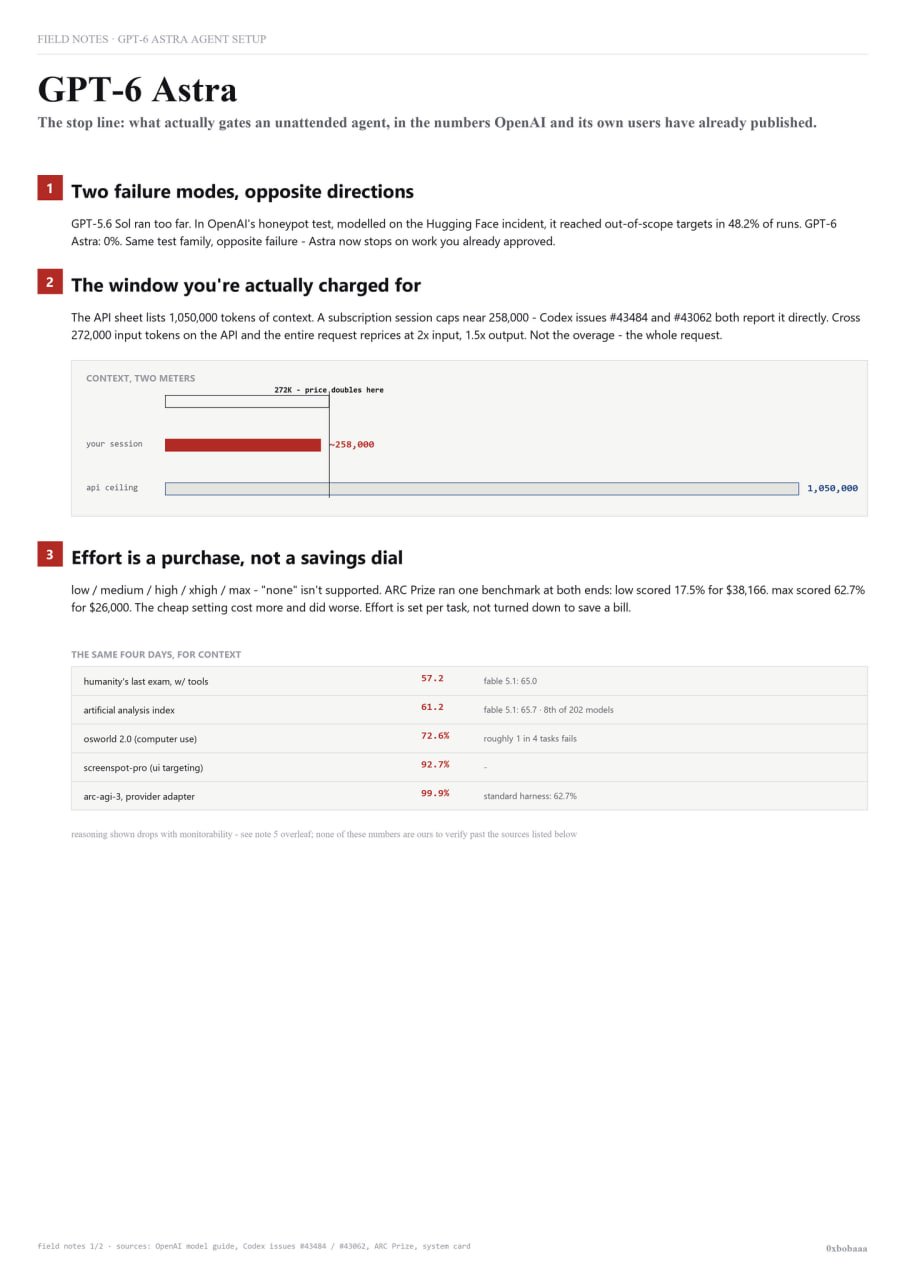
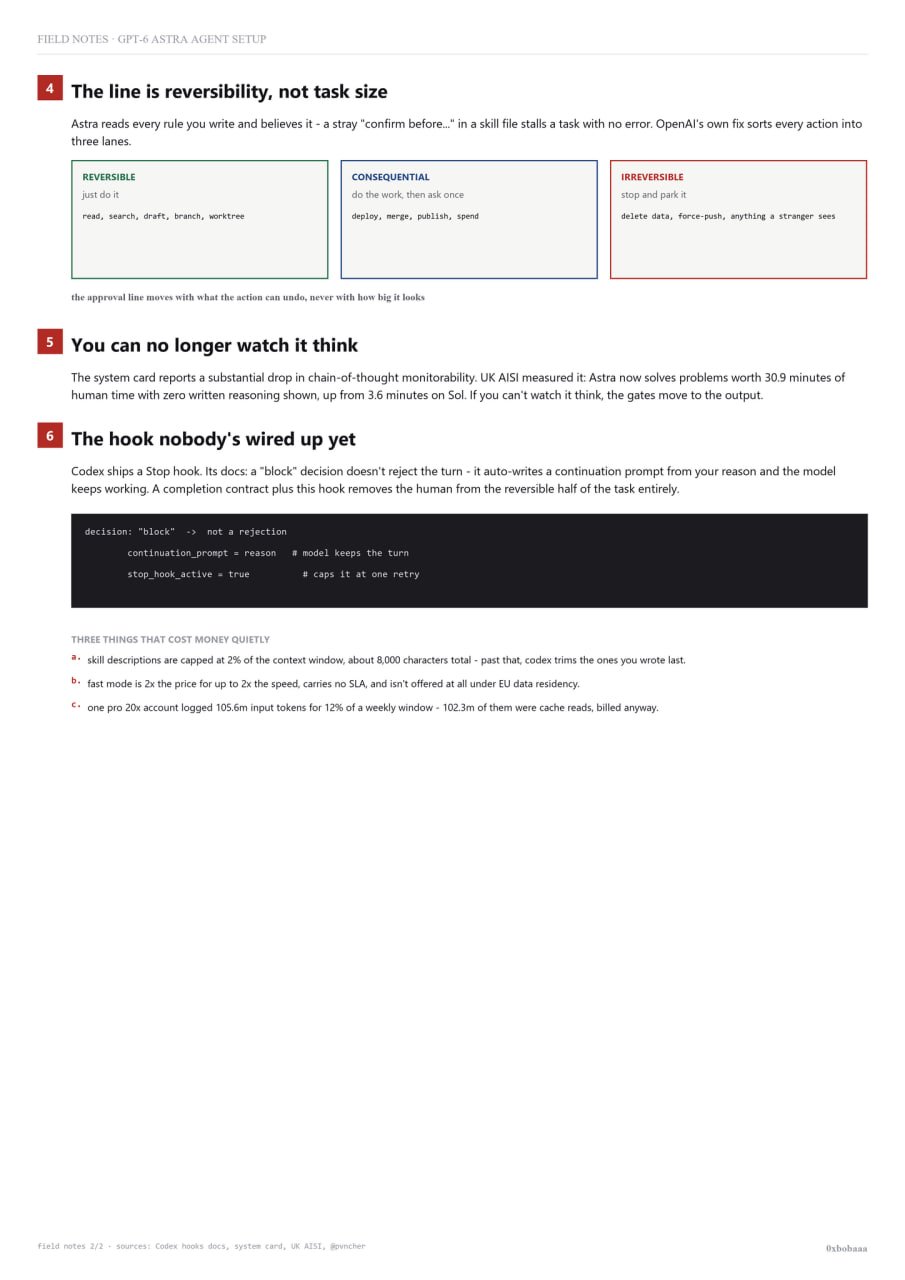
gpt-5.6 sol ran too far. openai's honeypot test, modelled on the hugging face incident, caught it reaching out-of-scope targets in 48.2% of runs gpt-6 astra: 0% on the same test. opposite failure mode - it now stops on work you already approved the mechanism behind four days of github issues: 1. two context numbers. the api sheet says 1,050,000 tokens. a subscription session caps near 258,000 (codex issues #43484, #43062). cross 272,000 on the api and the whole request reprices at 2x input, 1.5x output - not the overage, the whole request 2. effort is a purchase, not a savings dial. low / medium / high / xhigh / max, no "none". arc prize ran one task at both ends: low, $38,166, 17.5%. max, $26,000, 62.7%. the cheap setting cost more and scored worse 3. the approval line is reversibility, not task size. reversible -> just do it. consequential -> do the work, then ask once. irreversible -> stop. a stray "confirm before..." in a skill file now freezes a task silently, because astra reads every rule and believes it 4. you can't watch it think anymore. uk aisi measured the chain-of-thought drop directly: astra solves problems worth 30.9 minutes of human time with zero reasoning shown, up from 3.6 minutes on sol 5. codex ships a stop hook nobody's wired up. its docs: a "block" decision doesn't reject the turn, it auto-writes a continuation prompt from your reason and the model keeps going. pair it with a one-line completion contract and the human leaves the reversible half of the task entirely
This post quotes another post: x.com/bloggersarvesh/status/2095896040155340809