GPT-6 Astra tops RecreationBench at 58.06% but passes only 2.8% of tasks fully
A paper shows GPT-6 Astra ranks first on a cross-platform interface recreation benchmark but fully passes only 2.8% of tasks, because it rebuilds how a screen looks far better than how it behaves.
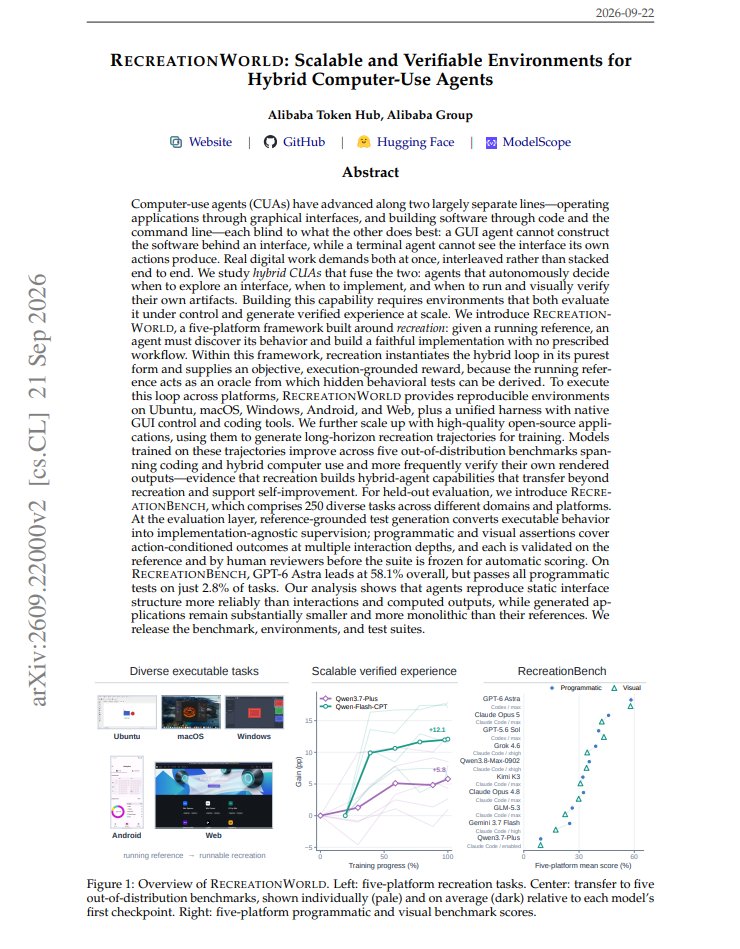
this is wild, GPT-6 Astra tops RecreationBench at 58.06% and passes everything on 2.8% of the tasks the reason: it rebuilds what a screen looks like far better than what the screen actually does here's what the paper shows: > 250 tasks across Ubuntu, macOS, Windows, Android and web, 50 on each, every one graded by code and by a vision judge > second place is Claude Opus 5 at 44.16%, then GPT-5.6 Sol at 42.06%, so this is the strongest of them failing this way > between those two numbers is work that looks finished, opens, renders, and breaks on the step that matters > 94.2% of the checks look at what happens after an interaction, rather than at whether the interface appeared > even the strongest model relaunched and inspected its own result after the last edit in 47.5% of attempts the result: handing work over makes sense only when you can check it in a minute, because the model mostly won't check itself which jobs clear that bar and which ones quietly cost you is what my article covers
This post quotes another post: x.com/1450821446859624454/status/210709866593638…