Back-of-envelope math puts DeepSeek's DeepInfer cluster at ~2,400 B200s serving 155T tokens/day
Working backward from DeepSeek's inference deployment Q&A figures on prefill/decode throughput and cache hit rate, the poster estimates one cluster at roughly 1,185 GPU pairs, or about 2,400 B200s.
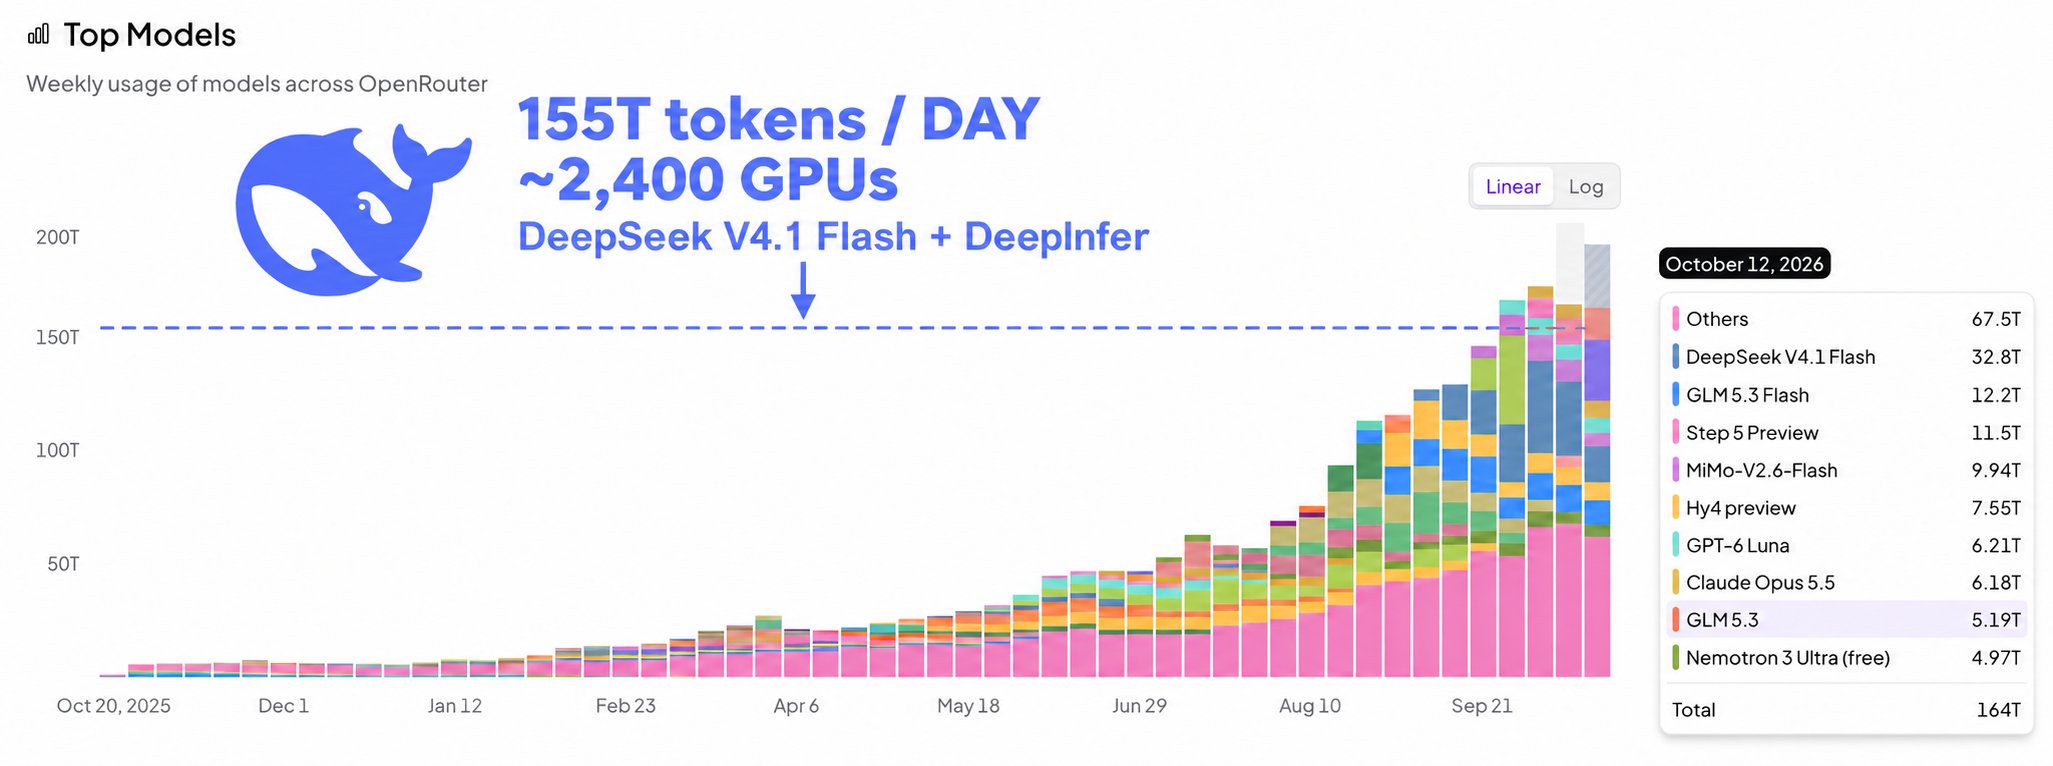
I don’t think folks realize just how insane DeepInfer is. One cluster with DeepInfer. IN One day. Can produce AS MUCH tokens AS OpenRouter in an entire week. “A single cluster currently serves 155 trillion tokens per day, with overall revenue of US$38 per GPU-hour (at valley pricing).” - "DeepSeek V4.1 Flash Inference Deployment Q&A" I wanted to know what “a single cluster” actually means here. So I worked backward from the numbers DeepSeek shared: -- 60,000 fresh input tokens/sec per prefill GPU -- 14,000 output tokens/sec per decode GPU -- Roughly a 1:1 prefill-to-decode GPU ratio -- 77K average input length -- 96% input cache hit rate Insane perf numbers but otherwise pretty resonable assumptions on the user side. With only 4% of input needing fresh processing, each prefill GPU serves: 60,000 ÷ 4% = 1.5 million input tokens/sec Add the decode side: 1,500,000 + 14,000 = 1,514,000 tokens/sec × 86,400 seconds = 130.8 billion tokens/day. Now divide the cluster’s reported 155 trillion by that: 155 trillion ÷ 130.8 billion ≈ 1,185 pairs. That’s ~1,185 prefill GPUs + ~1,185 decode GPUs. Roughly 2,400 B200 GPUs. And how many B200-family GPUs have shipped worldwide? An estimated 2.2–3.0 MILLION by July 2026. This cluster’s inferred GPU count is about 0.1% of that estimated shipped base. 🤯🤯🤯