Replacing Opus self-grading with three Jev questions
The author shares an ~80-line Python manual where CHOICE picks the next worker, SCORE judges whether a source is worth reading, and NOUL decides if a draft is ready to publish, so Opus writes once and Jev handles the checks.
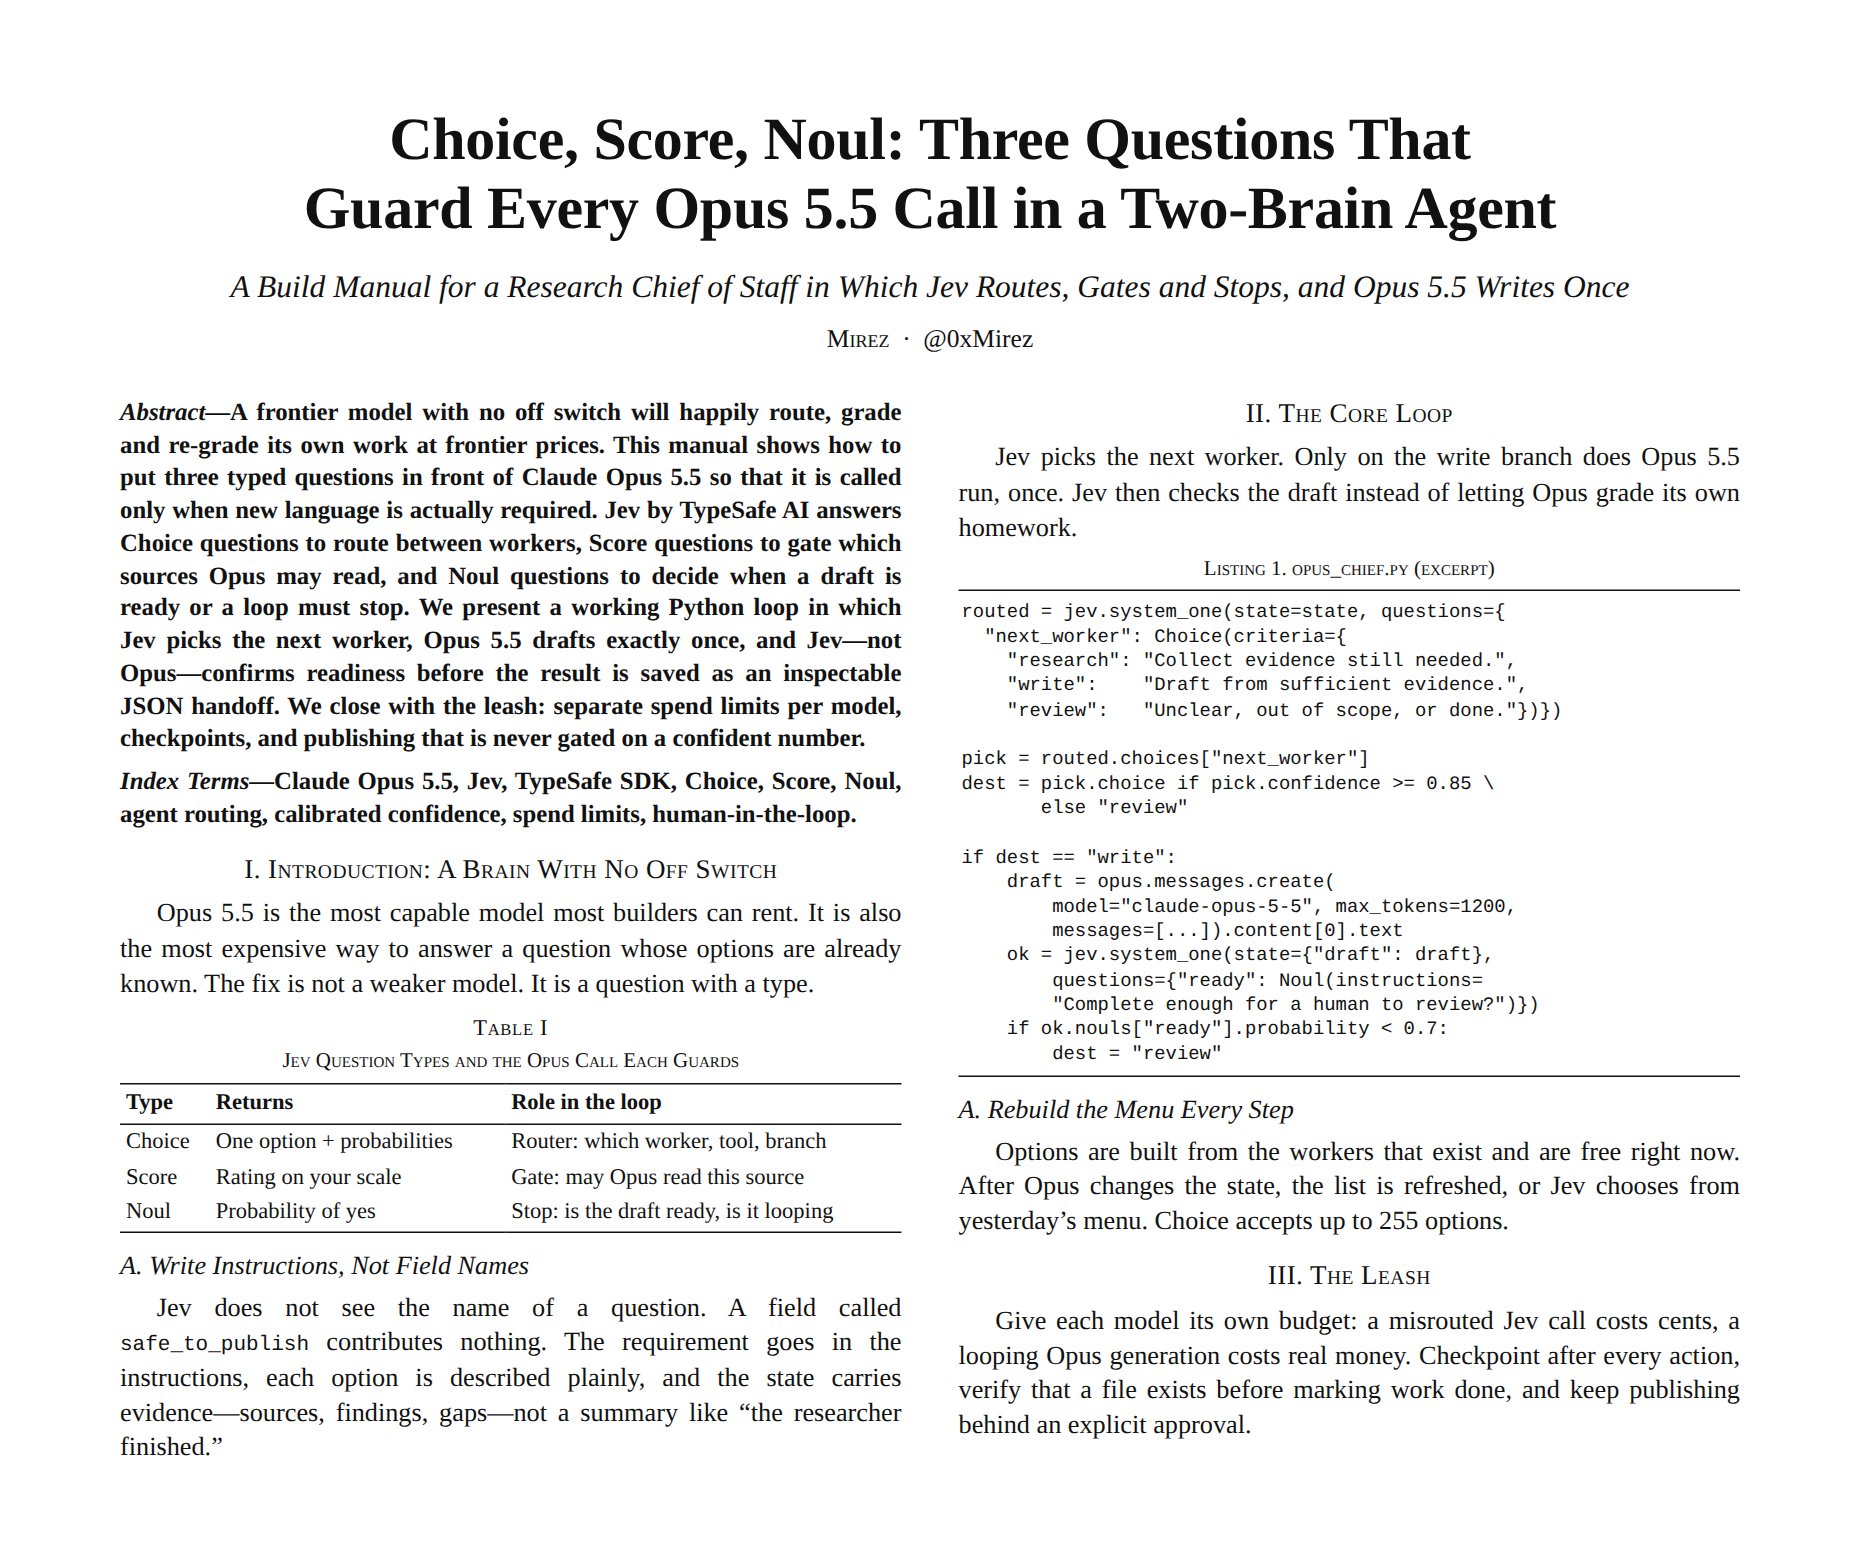
i still don't understand why people let opus 5.5 grade its OWN homework your agent calls a frontier model to write the draft, then calls it AGAIN to ask "is this good?" you're paying frontier rates for a yes or no i wrote a build manual on fixing this with 3 questions from jev: → CHOICE: which worker goes next → SCORE: is this source worth opus reading → NOUL: is the draft actually ready jev answers in 70 to 500ms at $0.042 per million tokens. opus writes exactly ONCE the full loop is in python, about 80 lines. two api keys, one json handoff you can inspect opus writes. jev checks. nothing publishes without your approval:
This post quotes another post: x.com/0xzynex/status/2103182484775039307