Scale AI leaderboards: GPT-6 Astra and Fable 5.1 split the coding benchmarks
Astra wins SWE Atlas Refactoring and HLE while Fable 5.1 takes SWE Atlas Test Writing and both PRBench splits, codebase QnA is nearly tied, and no model clears 70 on SWE Atlas.
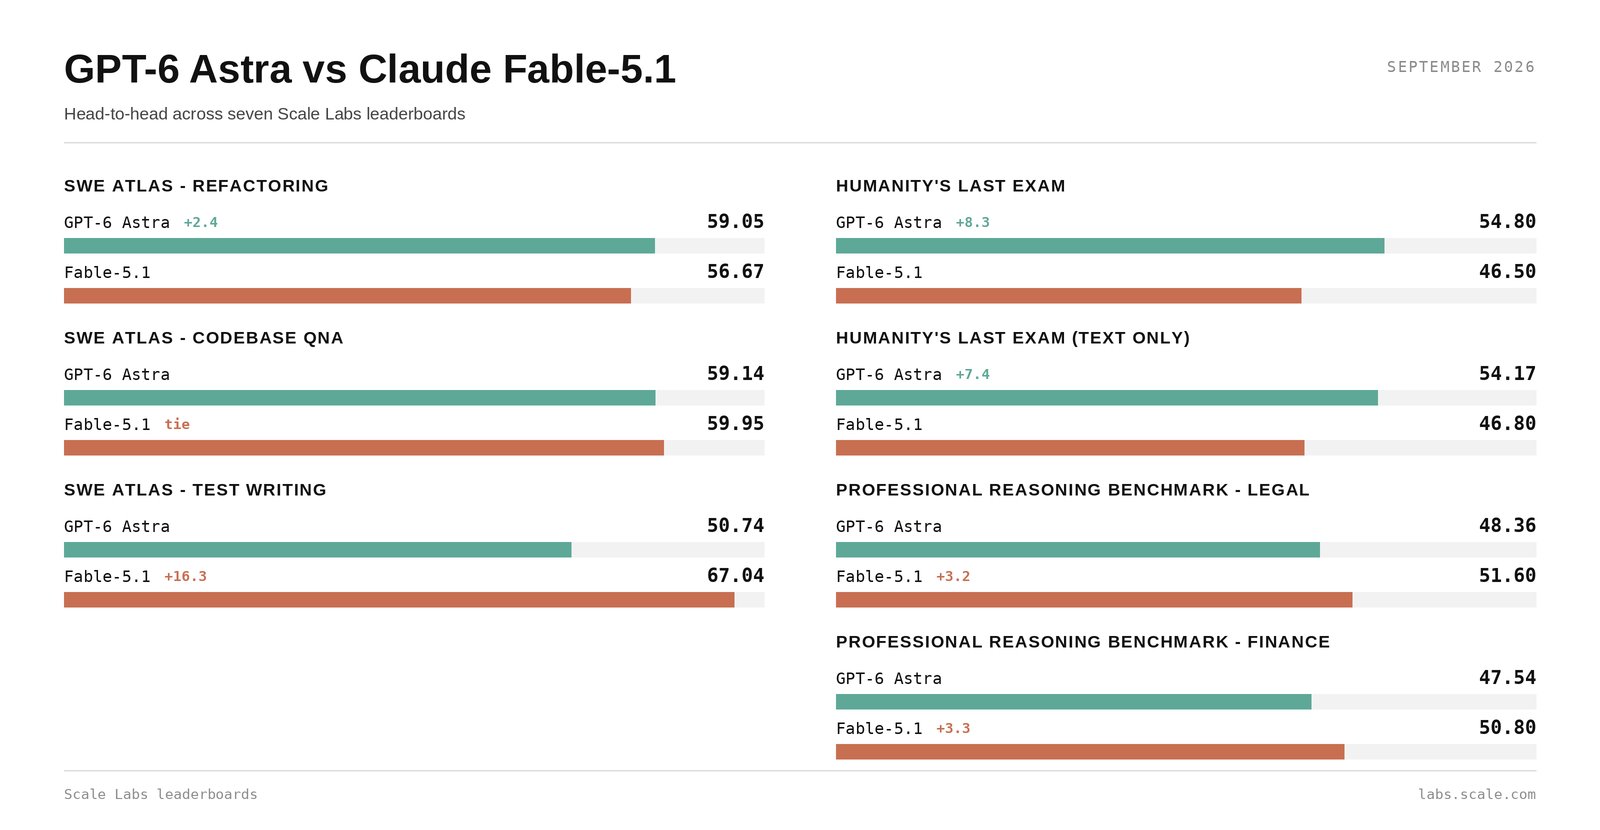
🚨🚨🚨New models on the @ScaleAILabs leaderboards! It's a tight race with @OpenAI's GPT-6 Astra and @AnthropicAI's Fable 5.1. Astra takes SWE Atlas Refactoring and HLE. Fable takes SWE Atlas Test Writing and both PRBench splits. Codebase QnA is a near tie. Moving past the headlines, the two models are good at different things. There is no one size fits all model for your work, and I don't expect that to change. Also, that split is only visible because benchmarks like SWE Atlas are nowhere near saturated. No model clears 70 on SWE Atlas still. There are still plenty of real coding tasks to improve on here.
This post quotes another post: x.com/scaleailabs/status/2097776601039839608