deepseek-v4.1IMAGE
Image-logic benchmark across 93 models ranks V4.1 Flash 1017 worst ever
The author ran a personal image-plus-logic benchmark on 93 models and calls V4.1 Flash 1017 the worst ever, arguing distillation, quantization and task-specific RL hurt general ability.
Kevin A. Bryan
@AfinetheoremArchived 12 days agoOriginally posted 2026.10.19
Kevin A. Bryan @AfinetheoremOriginally posted 2026.10.19
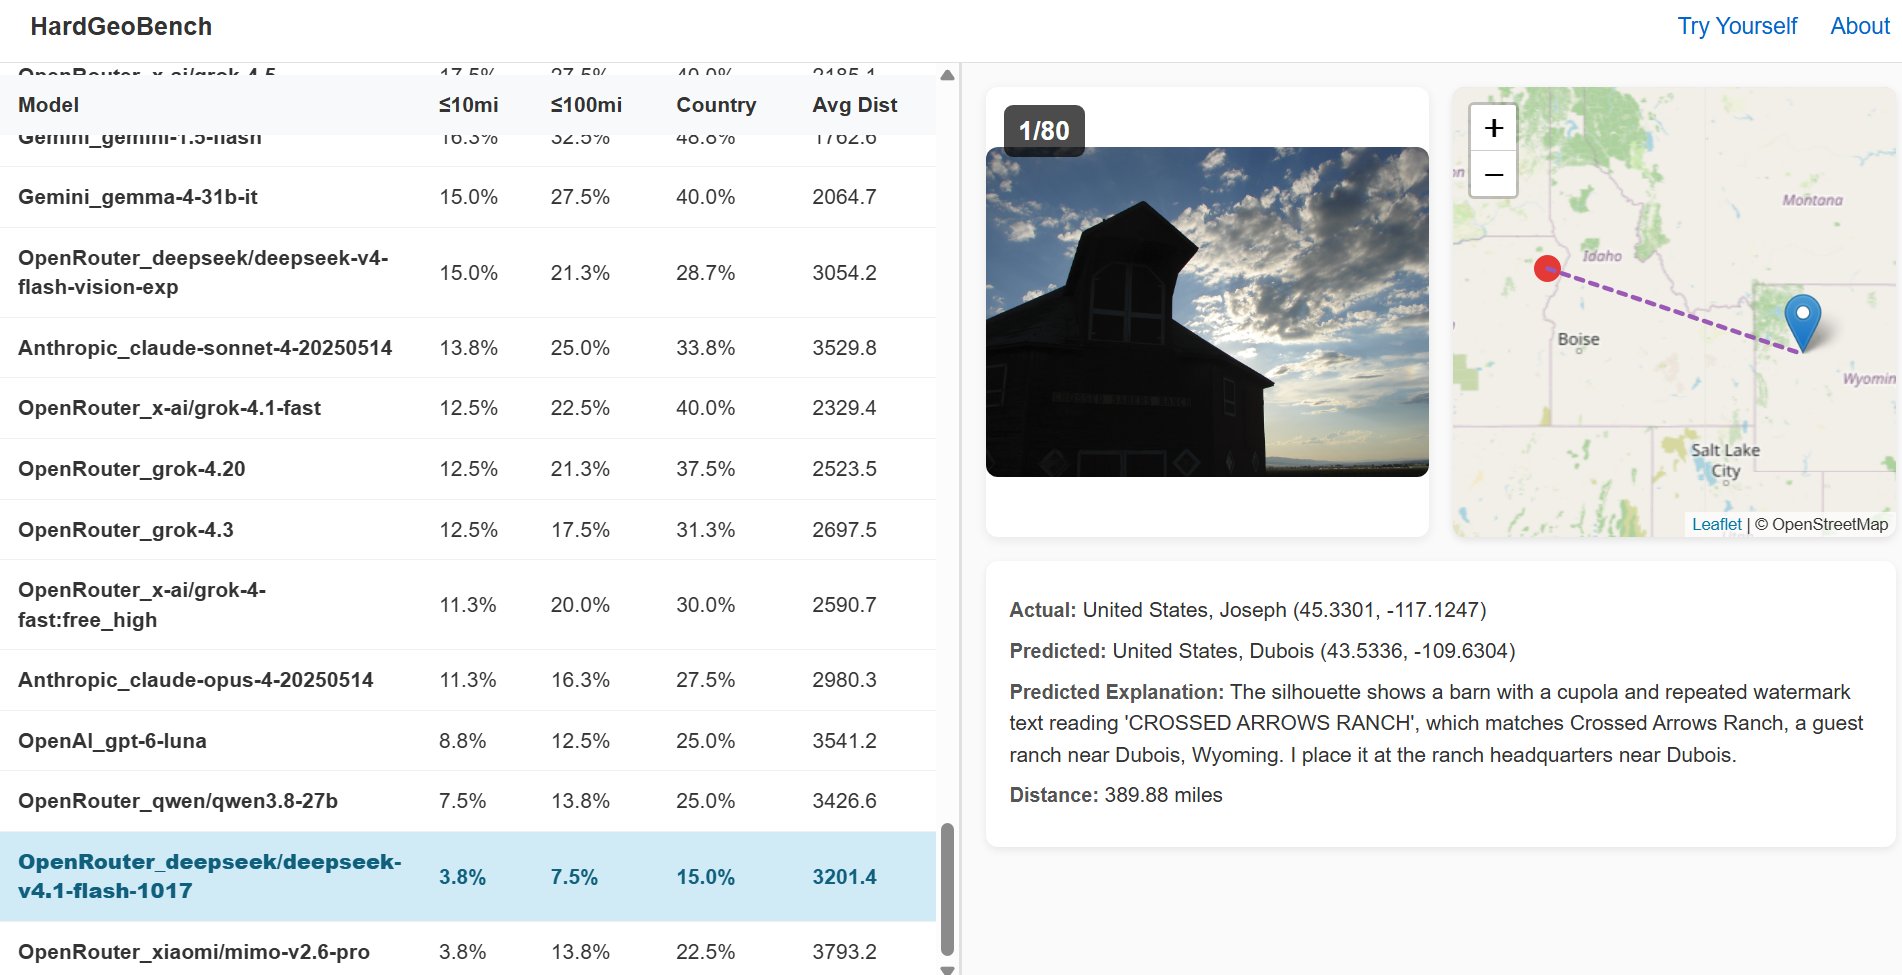
Distillation plus quantization plus RL on very specific tasks = big harms on general AI. I've run this image + logic benchmark of mine on 93 models over 1.5 years. The worst model *ever*: Deepseek v4.1 Flash 1017. The four worst? GPT 6 Luna, Mimi 2.6 Pro, Qwen 3.8 27b. 1/2
x.com/afinetheorem/status/2111976082618318929Archived 2026.10.19 12:03