You.com Inference Router adds DeepSeek V4.1 Flash with 99.9% SLA
You.com launched an enterprise inference router supporting DeepSeek V4.1 Flash and other open-weight models, with a 99.9% uptime SLA, zero data retention, US-hosted infrastructure, and an OpenAI-compatible API at 0% platform fee.
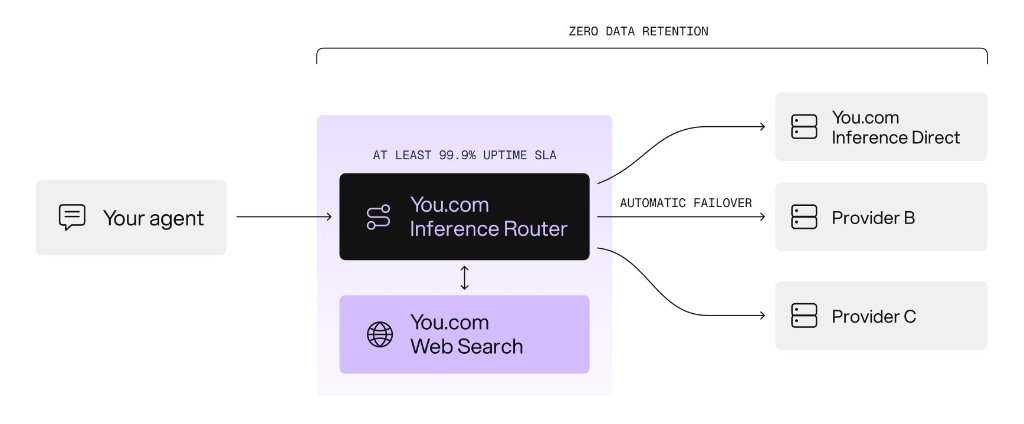
most teams prototype agent workflows on open-weight models using aggregators, but moving to enterprise production stalls when you need real uptime guarantees and strict data residency. @youdotcom launched Inference Router to solve that gap: enterprise-grade inference on demand for models like Kimi K3, GLM 5.3, DeepSeek V4.1 Flash, and Qwen 3.8. It comes with an uptime SLA of at least 99.9% backed by service credits, full-stack Zero Data Retention (ZDR), and 100% US-hosted infrastructure. it drops into existing code through an OpenAI-compatible API, with 0% platform fee and pay-as-you-go pricing. Requests hit own tuned capacity first and fail over automatically to vetted US partner hosts if capacity spikes, keeping latency and SLAs intact. worth a look if you're taking open-weight models into production.
This post quotes another post: x.com/youdotcom/status/2113330643472121873