KingBench 4 ranks five coding models across six projects
Five models each built six projects, including an emulator, a Docker alternative and a 3D room designer; Opus 5.5 led at 57.8% and GPT-6 Astra placed second at 56.5%.
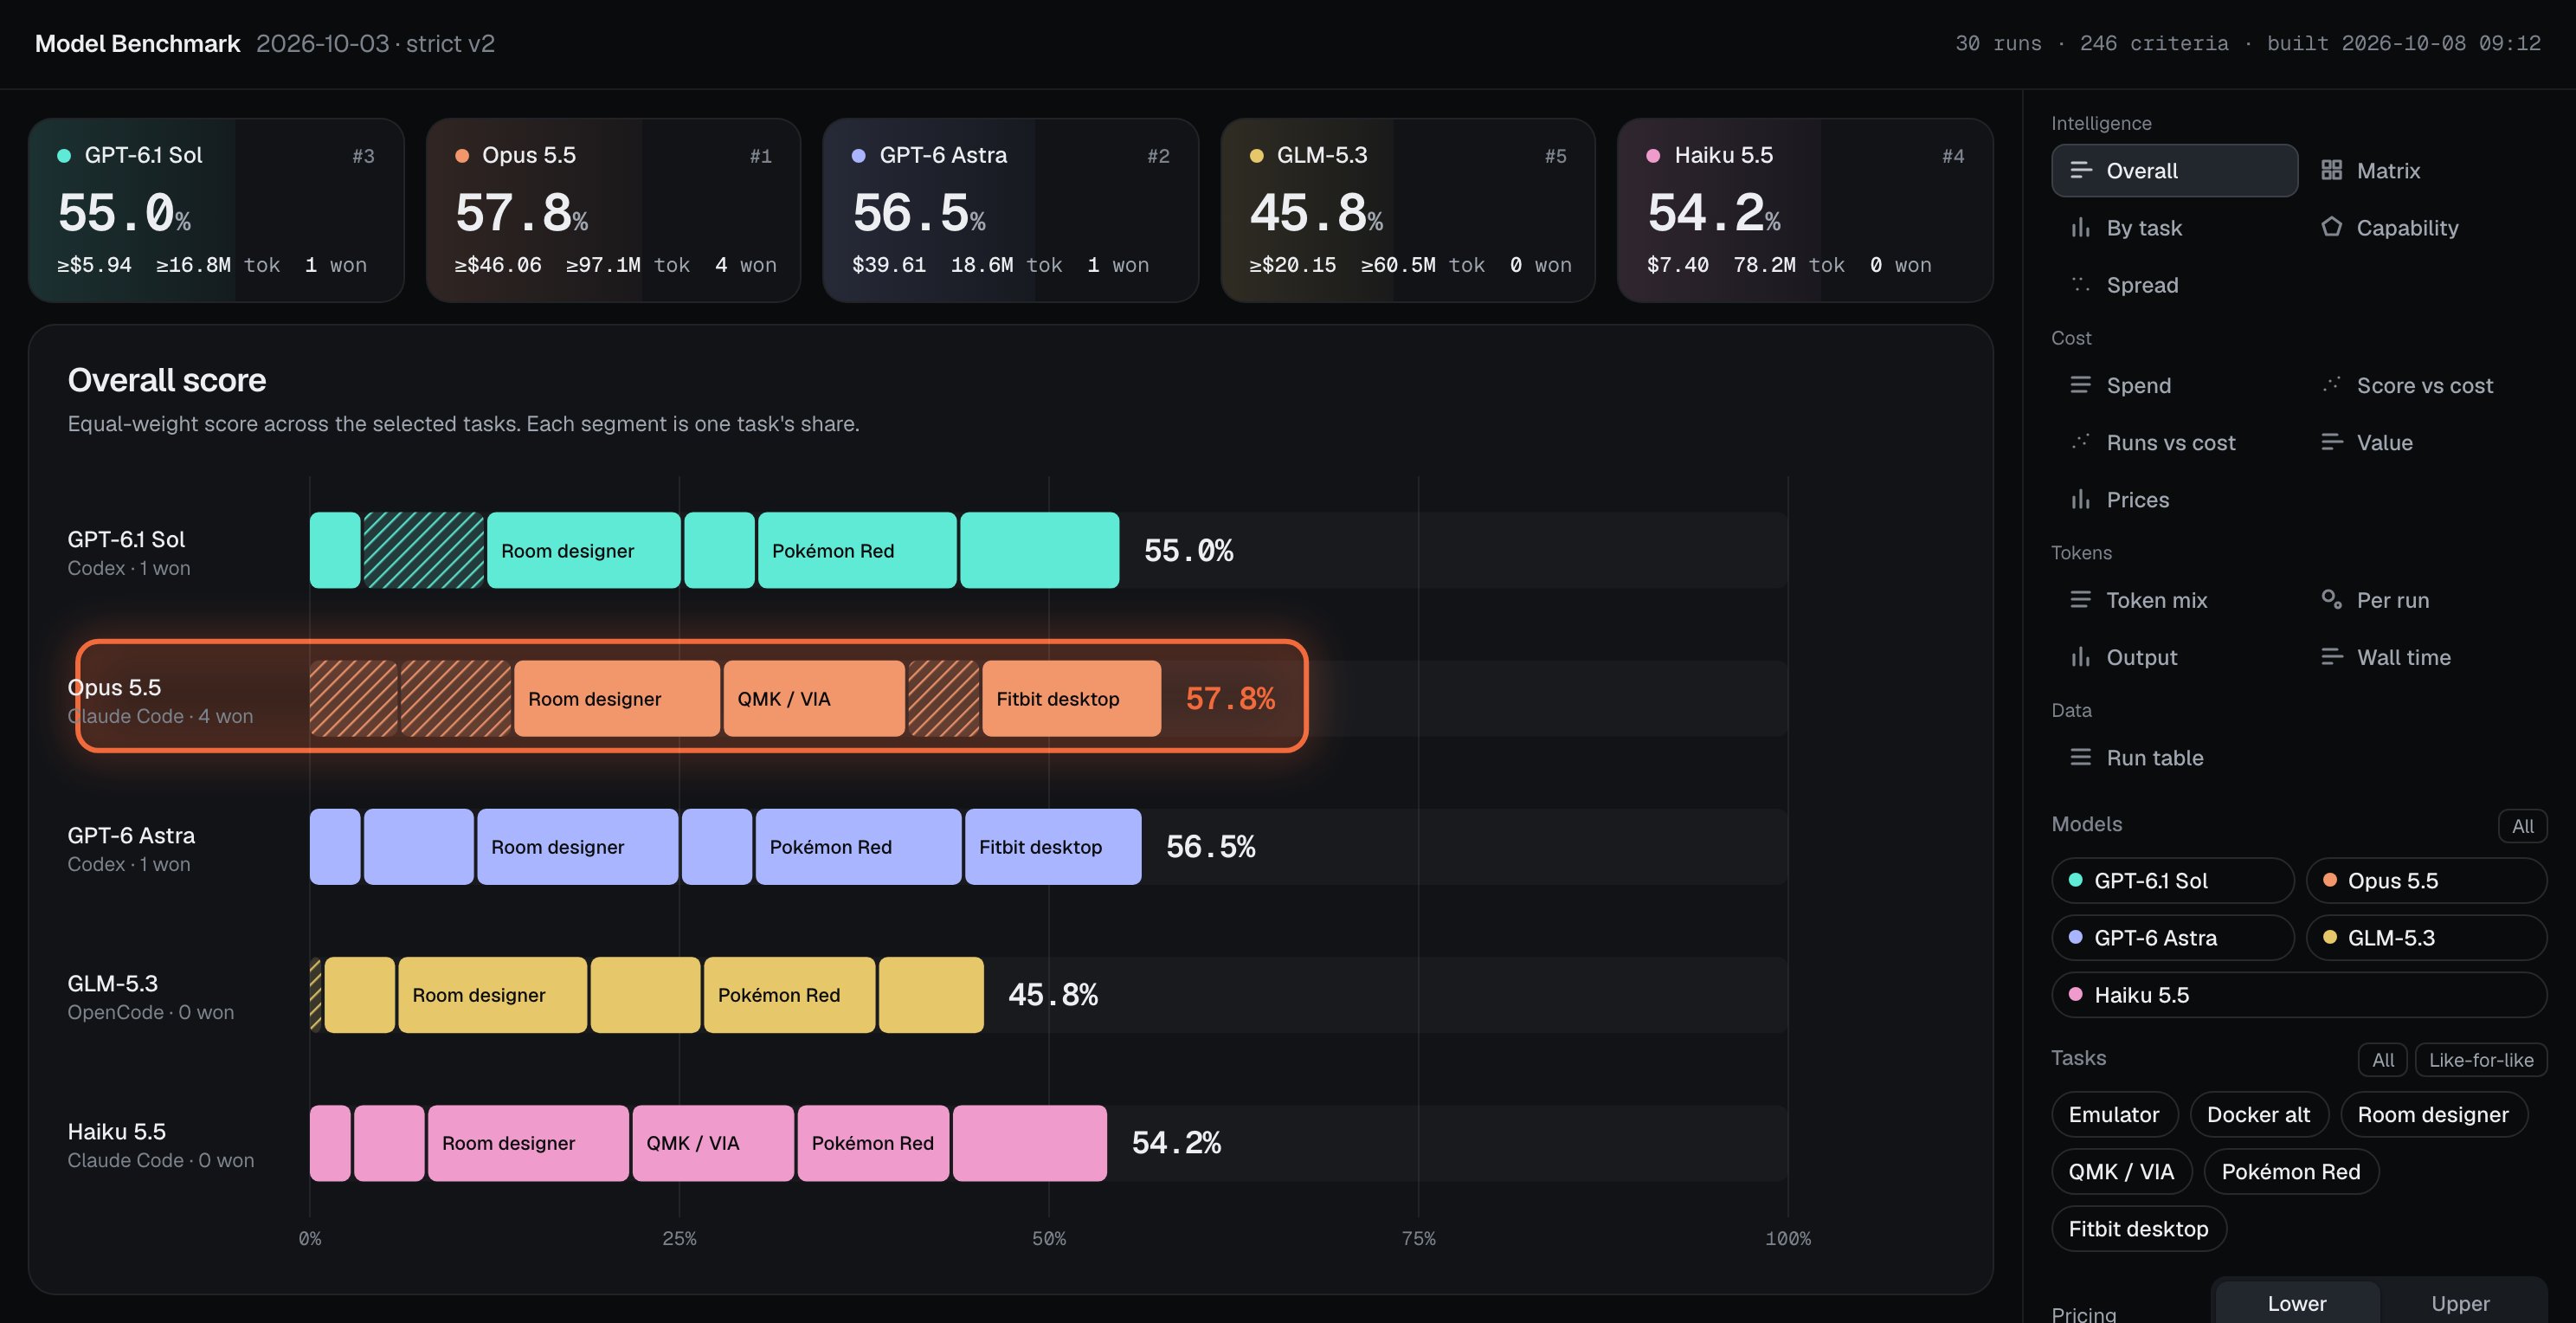
I've been working on KingBench 4. This benchmark isn't scientific or whatever in anyway. But, it does indeed align with my preference (how i'd position models based on my experience). So, I gave 5 AI coding models the same 6 projects: a Game Boy/DS/3DS emulator, a Docker alternative, a 3D room designer, a QMK keyboard configurator, Pokémon Red through the first gym and a Fitbit desktop app. #1: Opus 5.5 at 57.8% #2: GPT-6 Astra at 56.5% #3: GPT-6.1 Sol at 55.0% #4: Haiku 5.5 at 54.2% #5: GLM-5.3 at 45.8% to look at all generations and stuff.. look at this vid please: https://www.youtube.com/watch?v=cAIvhxVx0kU