LiveBench 2.0: DeepSeek V4.1 Flash at $0.18 per task, weak on long agentic runs
DeepSeek V4.1 Flash ties GPT-6.1 Sol at 96.0 on real merged-PR bug fixes at $0.18 per successful task (38x cheaper than Fable), but scores 40.9 vs 77.9 on long agentic work.
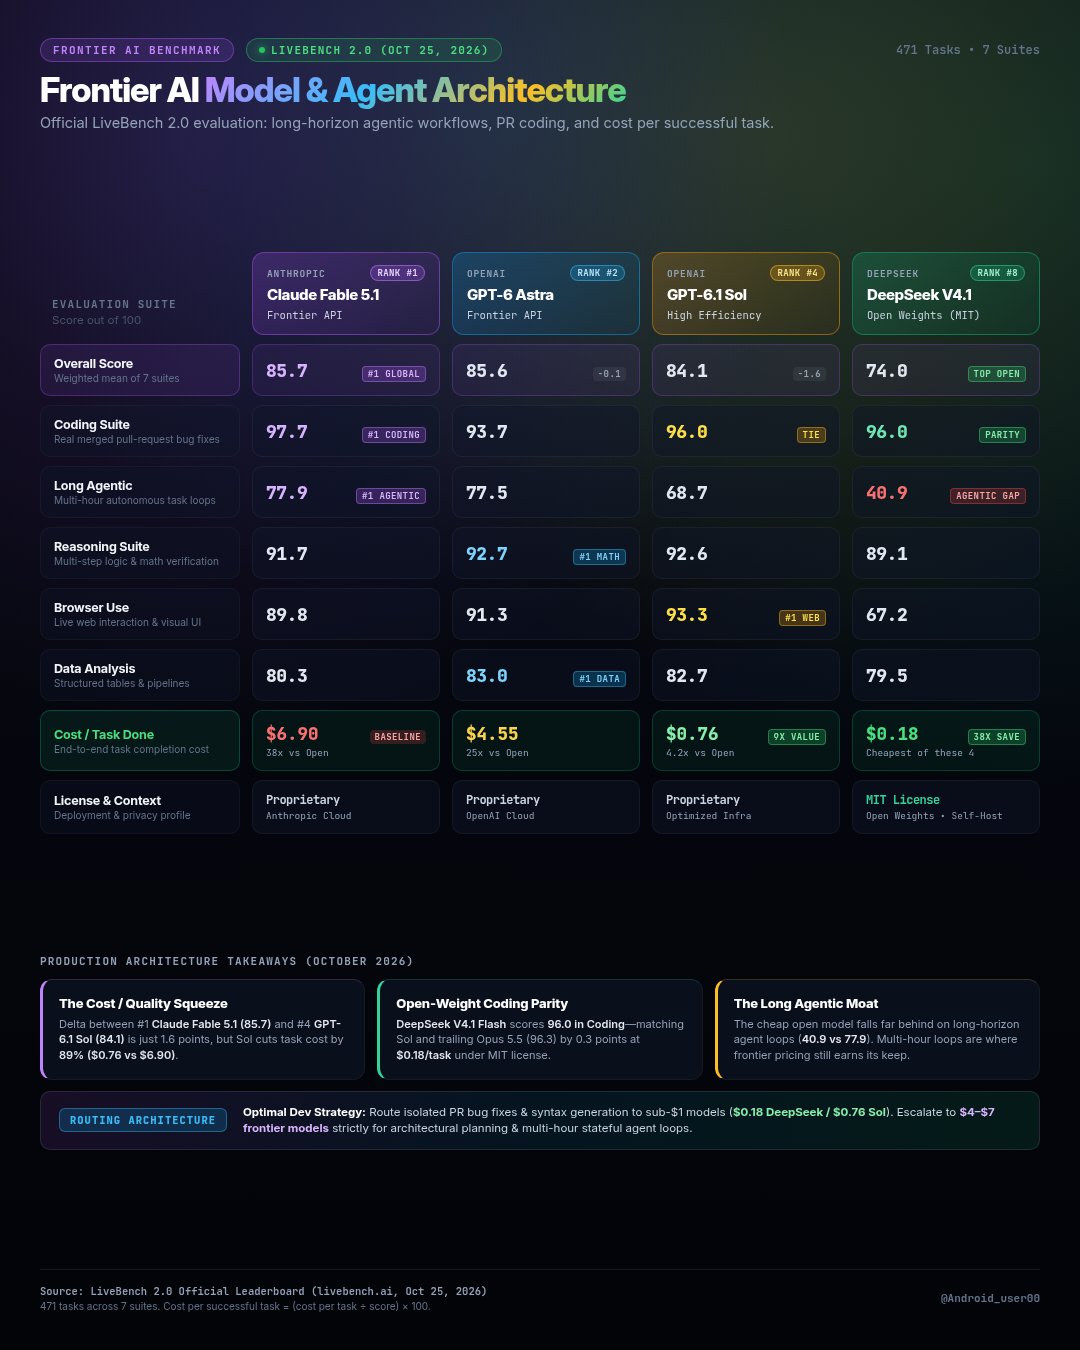
LiveBench 2.0 dropped yesterday, and it finally tracks what devs actually pay for: cost per successful task, not token price. Claude Fable 5.1 takes #1 overall (85.7) and #1 in coding (97.7), at $6.90 per successful task. GPT-6.1 Sol sits 1.6 points back at 84.1 for $0.76. Then there's DeepSeek V4.1 Flash: • Ties Sol at 96.0 on real merged-PR bug fixes • MIT license, open weights • $0.18 per successful task, 38x cheaper than Fable The catch is long agentic work: 77.9 for Fable vs 40.9 for DeepSeek. Cheap models fix diffs fine, then fall apart on multi-hour loops. Are you paying $7 a task for agent completion, or routing diffs to $0.18 models and saving frontier tokens for the hard stuff? #AIcoding