MicroAGI egocentric benchmarks: Gemini 4 Argon loses 4.9 points at high reasoning effort
MicroAGI's two robotics VLM benchmarks show Gemini 4 Argon dropping 4.9 points on its headline score at high reasoning effort while costing 4.7x more, with self-hosted nanoannot-1 beating it overall.
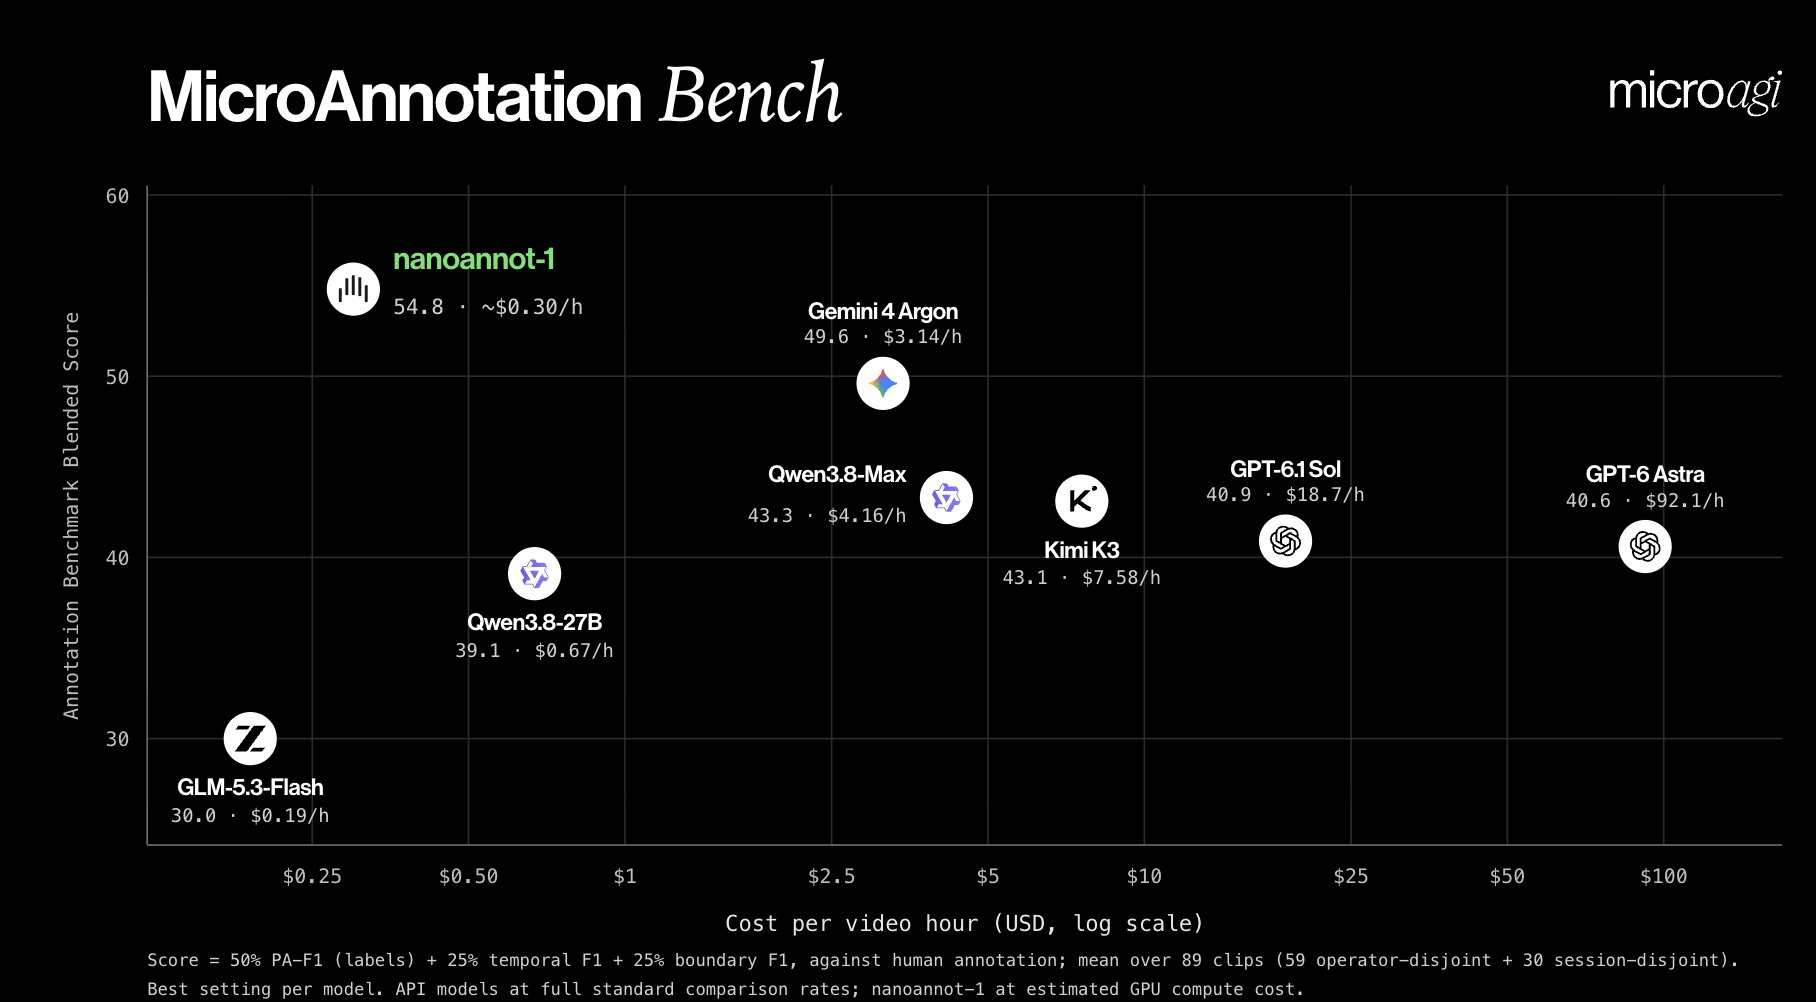
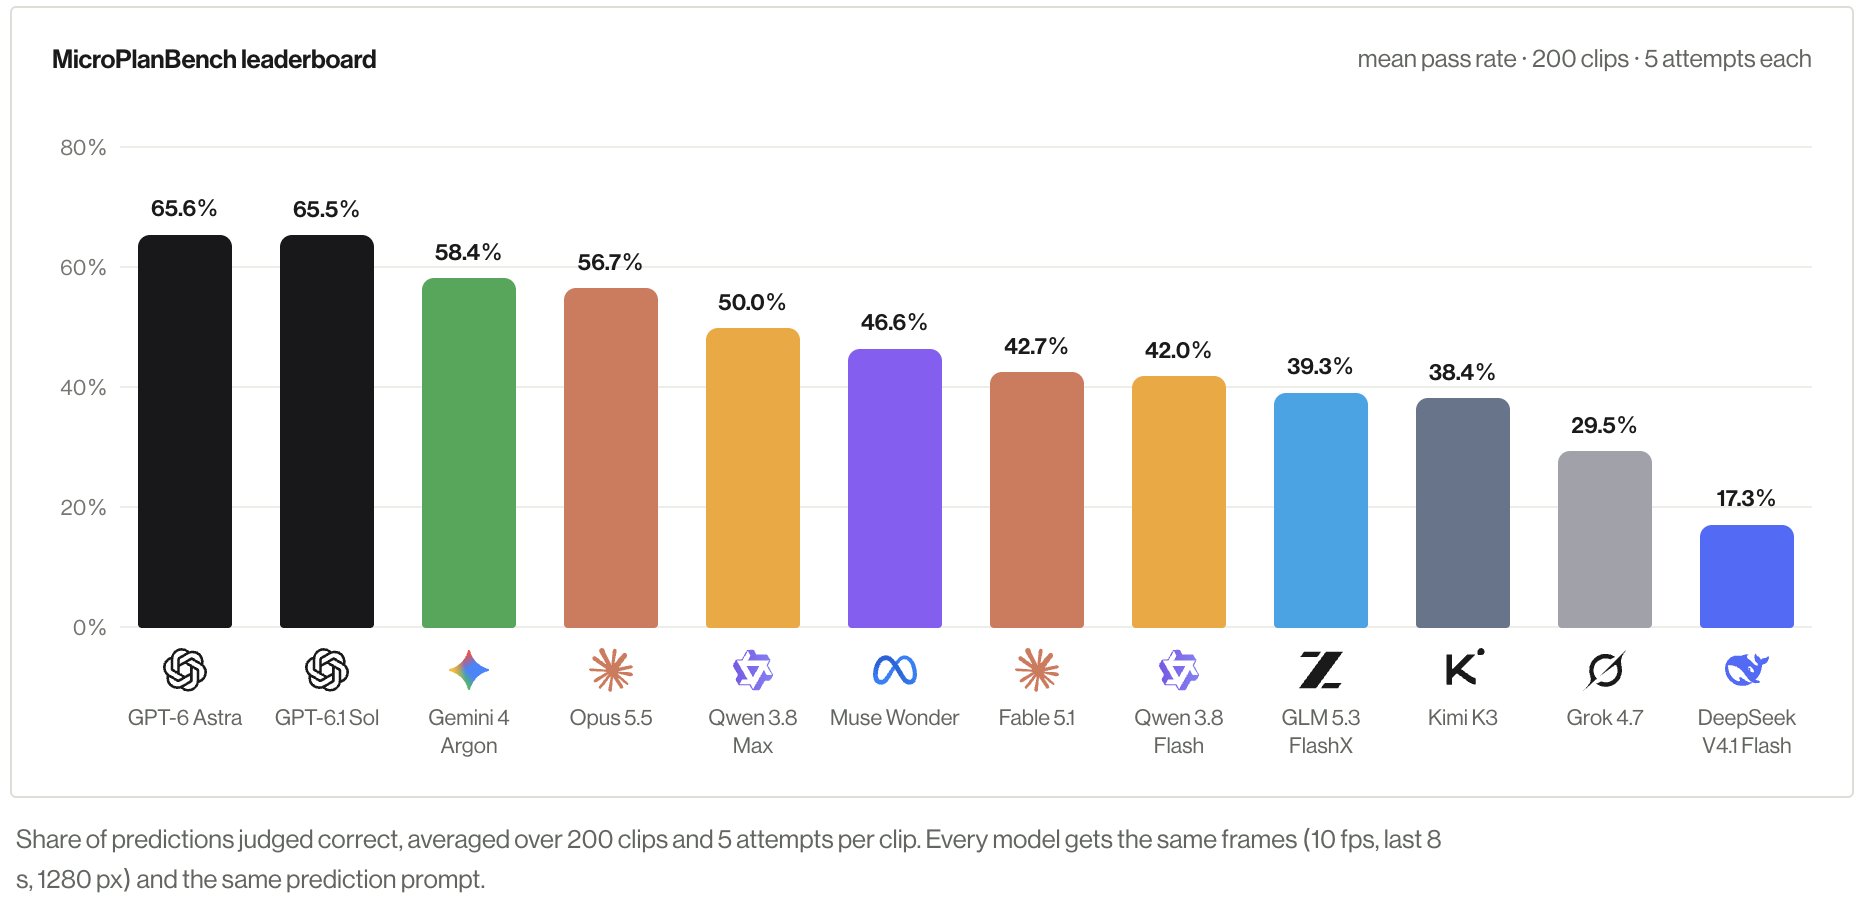
Two new egocentric benchmarks from @microagi evaluate VLM readiness for robotics: MicroPlanBench and MicroAnnotationBench. tl;dr: Semantic reasoning ≠ perceptual timing A lot of work to do. MicroPlanBench (consequential next-action planning) When predicting the single valid next atomic action from 8s of egocentric video, SOTA models still fail ~1/3 of the time (GPT-6 Astra: 65.6%, GPT-6.1 Sol: 65.5% at 1/5th cost). - GPT-6 Astra error breakdown: 60% wrong manipulation, 23% wrong hand assignment, 17% wrong object/destination. - Across all flags, 42% of failures involve tracking the wrong hand. https://www.microagi.ai/benchmarks/microplanbench MicroAnnotationBench (continuous temporal grounding) Knowing what happens ≠ knowing when Continuous 60s+ dense manipulation video remains unsolved for generalist VLMs: - GPT-6 Astra/Sol over-segment (~22 segments/clip vs. 13.8 human mean), collapsing precision (~39%) and strict Boundary F1 (<20%). - Scaling Test-time compute fails to fix perceptual boundaries: scaling Gemini 4 Argon to high reasoning effort dropped its headline score by 4.9 points while costing 4.7x more https://www.microagi.ai/benchmarks/microannotationbench Currently, Small specialists match/beat frontier APIs at scale. @microagi's self-hosted nanoannot-1 outperforms the frontier models (Gemini 4 Argon) across the board: - 54.8 vs 49.6 overall; - 32.9 vs 27.3 on strict ± 0.667s Boundary F1 - ~1/10th the cost (~$0.30 vs $3.14/video hr & >300x cheaper than GPT 6 Astra) Solid work by @ErguzelYag, Ömer Adanir & Team.
This post quotes another post: “New benchmarks: nanoannot-1 beats Gemini 4 Argon at 1/10 cost”