Baseten Mammoth vs Jev on 2,891 decision fields
The author benchmarks Baseten's open-weights Mammoth against Jev for cheap trace-filtering decisions, seeing a 15% lead on 2,891 consensus fields but doubting 27B throughput.
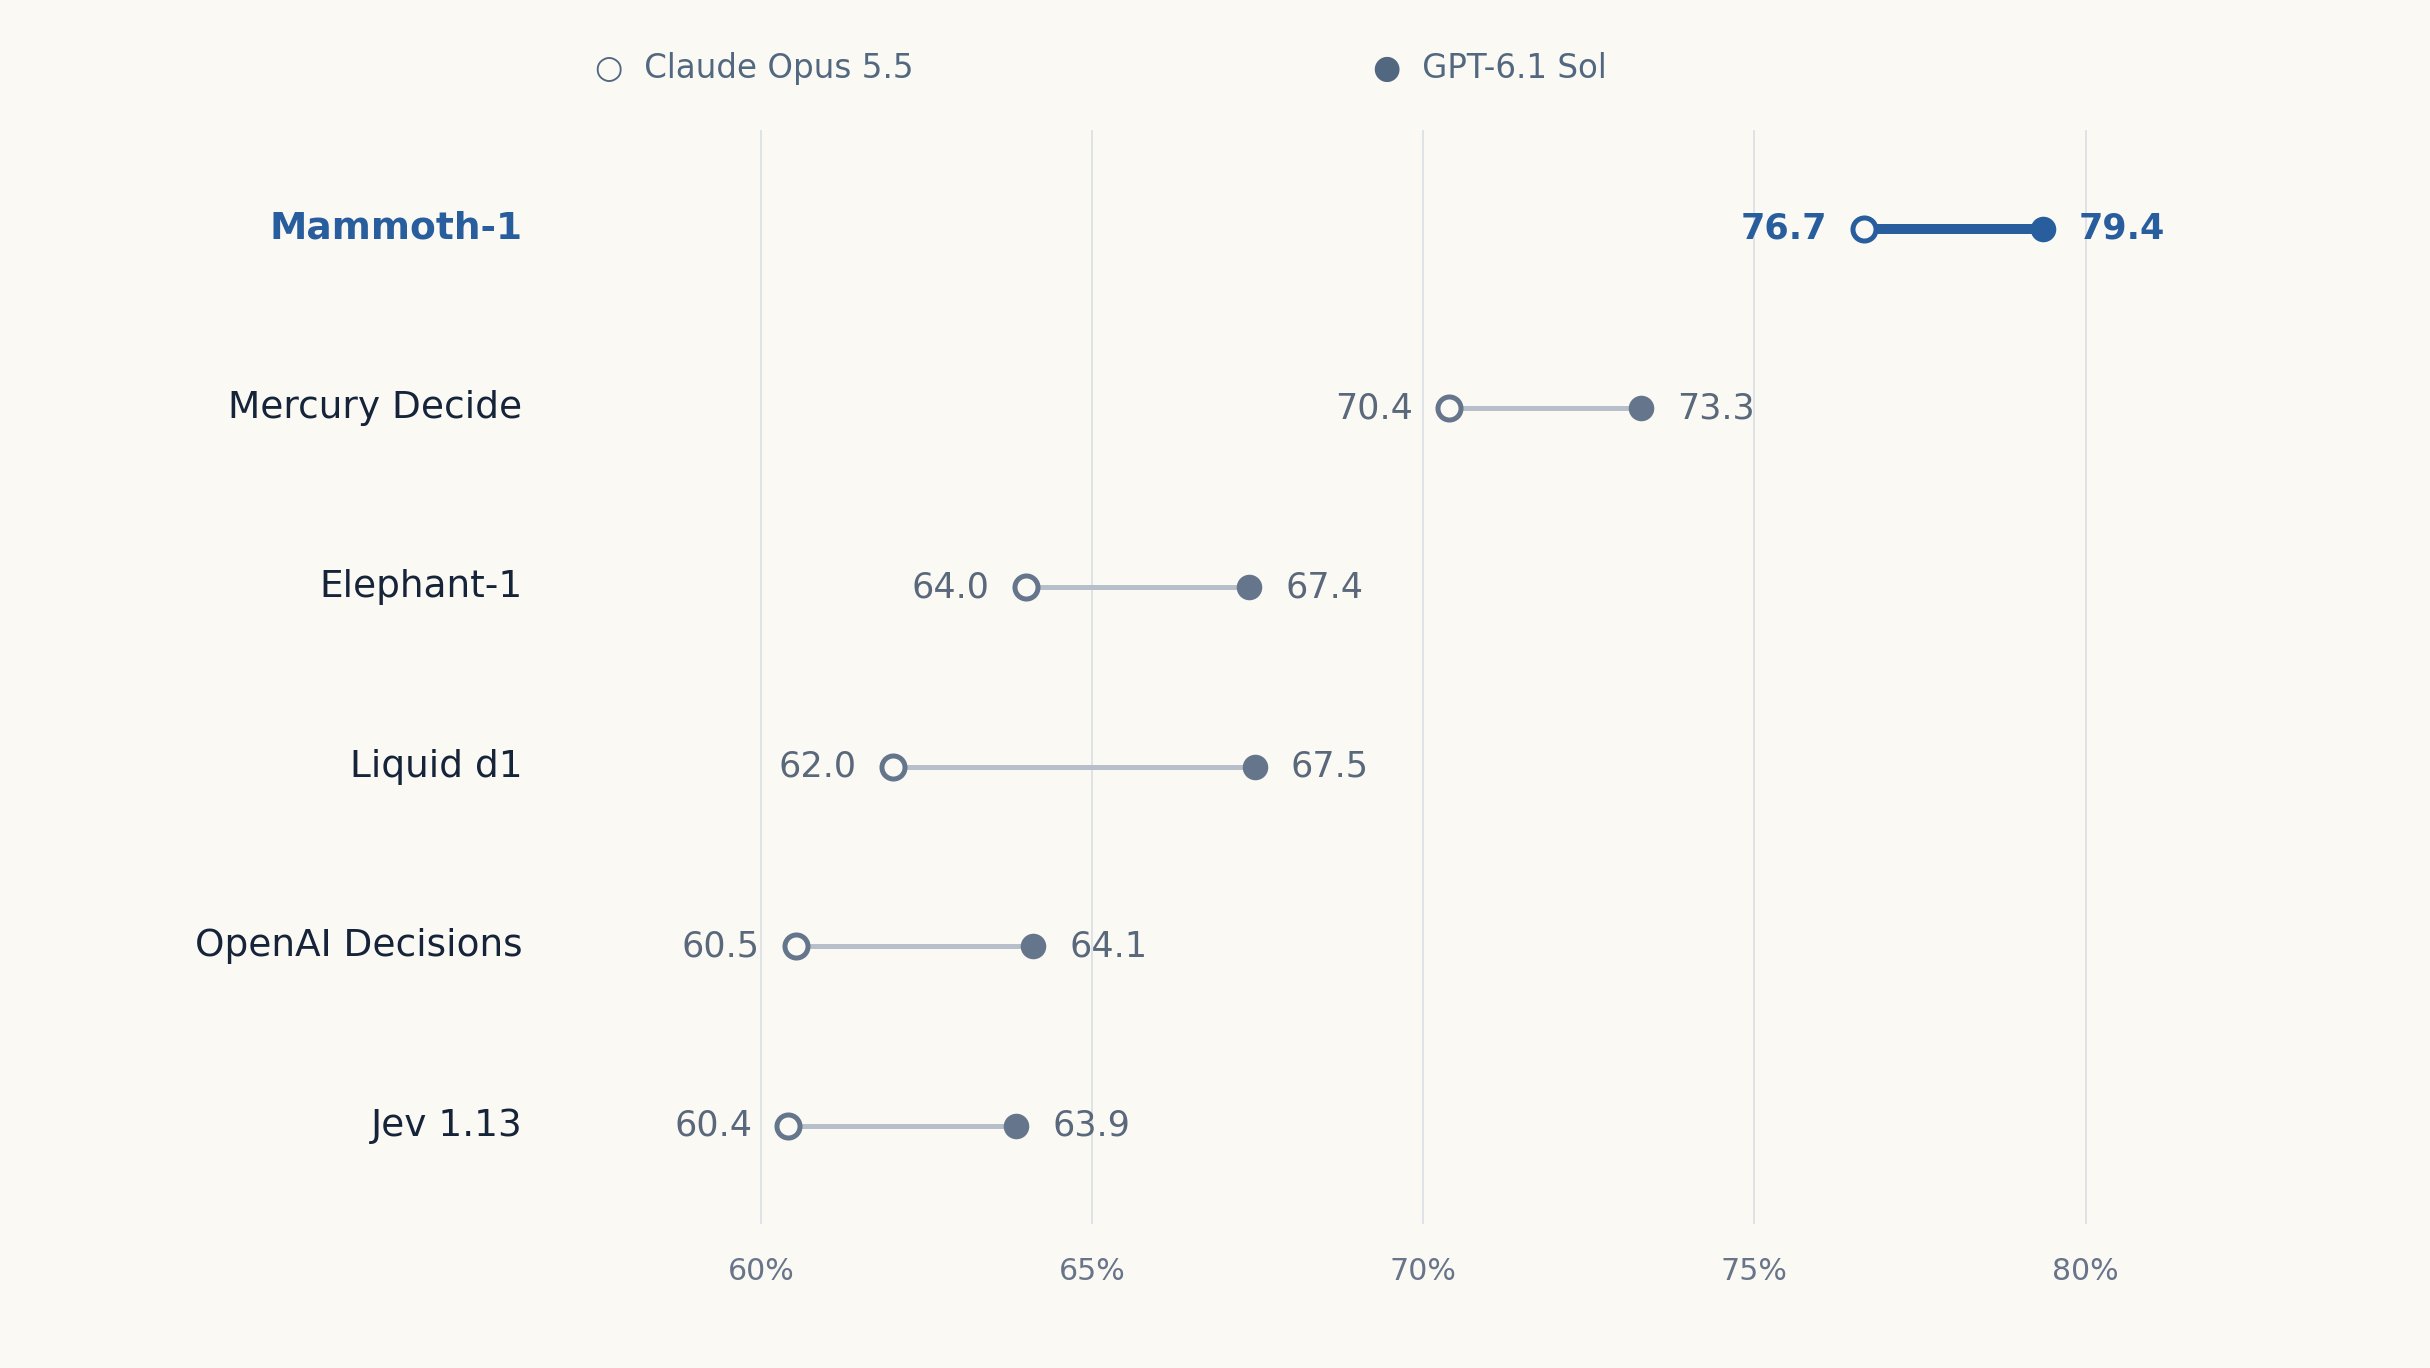
Baseten cooked so hard with this Mammoth model its unreal. I have been trying to find very cheap and fast Jev alternatives for my code understanding pipelines to filter traces. Getting a cheap decision algorithm to work at a massive scale has been a challenge especially with jev's small context window. In my internal eval test set of 2891 consensus fields mammoth beat Jev by a lead of 15% and that's amazing for a fully free open weights model. The only deciding factor now would be if this model could also compete on pricing. If the hosted offering of this model turns out of be cheaper than Jev then I will fully switch to this. Right now, its free and open weights but I am not sure my sparks can handle 300 concurrent threads and high throughput for a 27 B model.
This post quotes another post: x.com/2079474328664719360/status/211295558705945…