工具IMAGE
StepFun releases StepAudio 3 ASR speech-to-text model
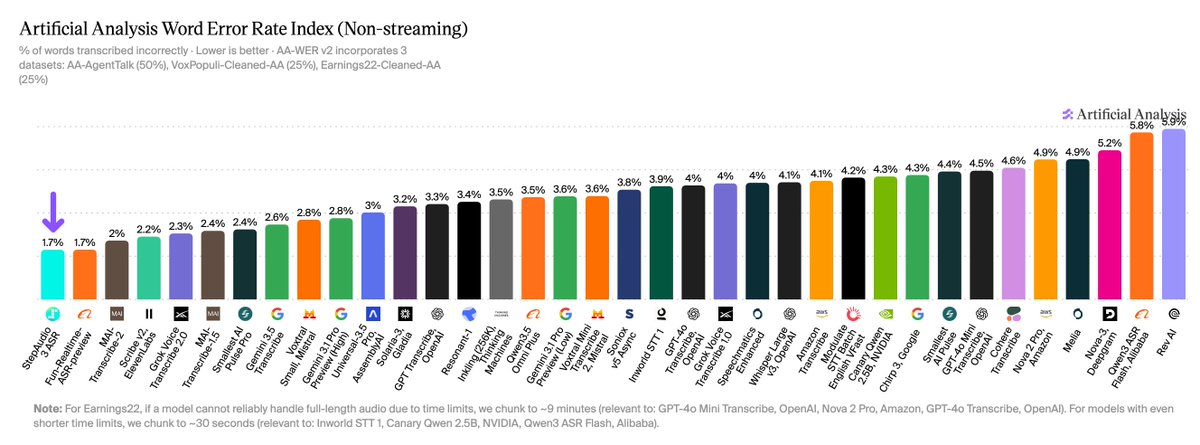
StepAudio 3 ASR ranks first on the AA-WER non-streaming speech-to-text index with a 1.7% error rate, down from 4.7% in the previous generation, and is available through the StepFun API.

Artificial Analysis
@ArtificialAnlysArchived 2026.09.23Originally posted 2026.09.23
Artificial Analysis @ArtificialAnlysOriginally posted 2026.09.23
StepFun has released StepAudio 3 ASR, ranking #1 on the AA-WER Index for non-streaming Speech to Text with 1.7% WER, a notable improvement on StepAudio 2.5 ASR (4.7%) StepAudio 3 ASR is StepFun's new Speech to Text model, available through the StepFun API for non-streaming https://t.co/hF17aMAFo7
x.com/artificialanlys/status/2102485740248842710Archived 2026.09.23 10:42