Claude Sonnet 5.5 uses ~7x the output tokens per task of GPT-6 Astra
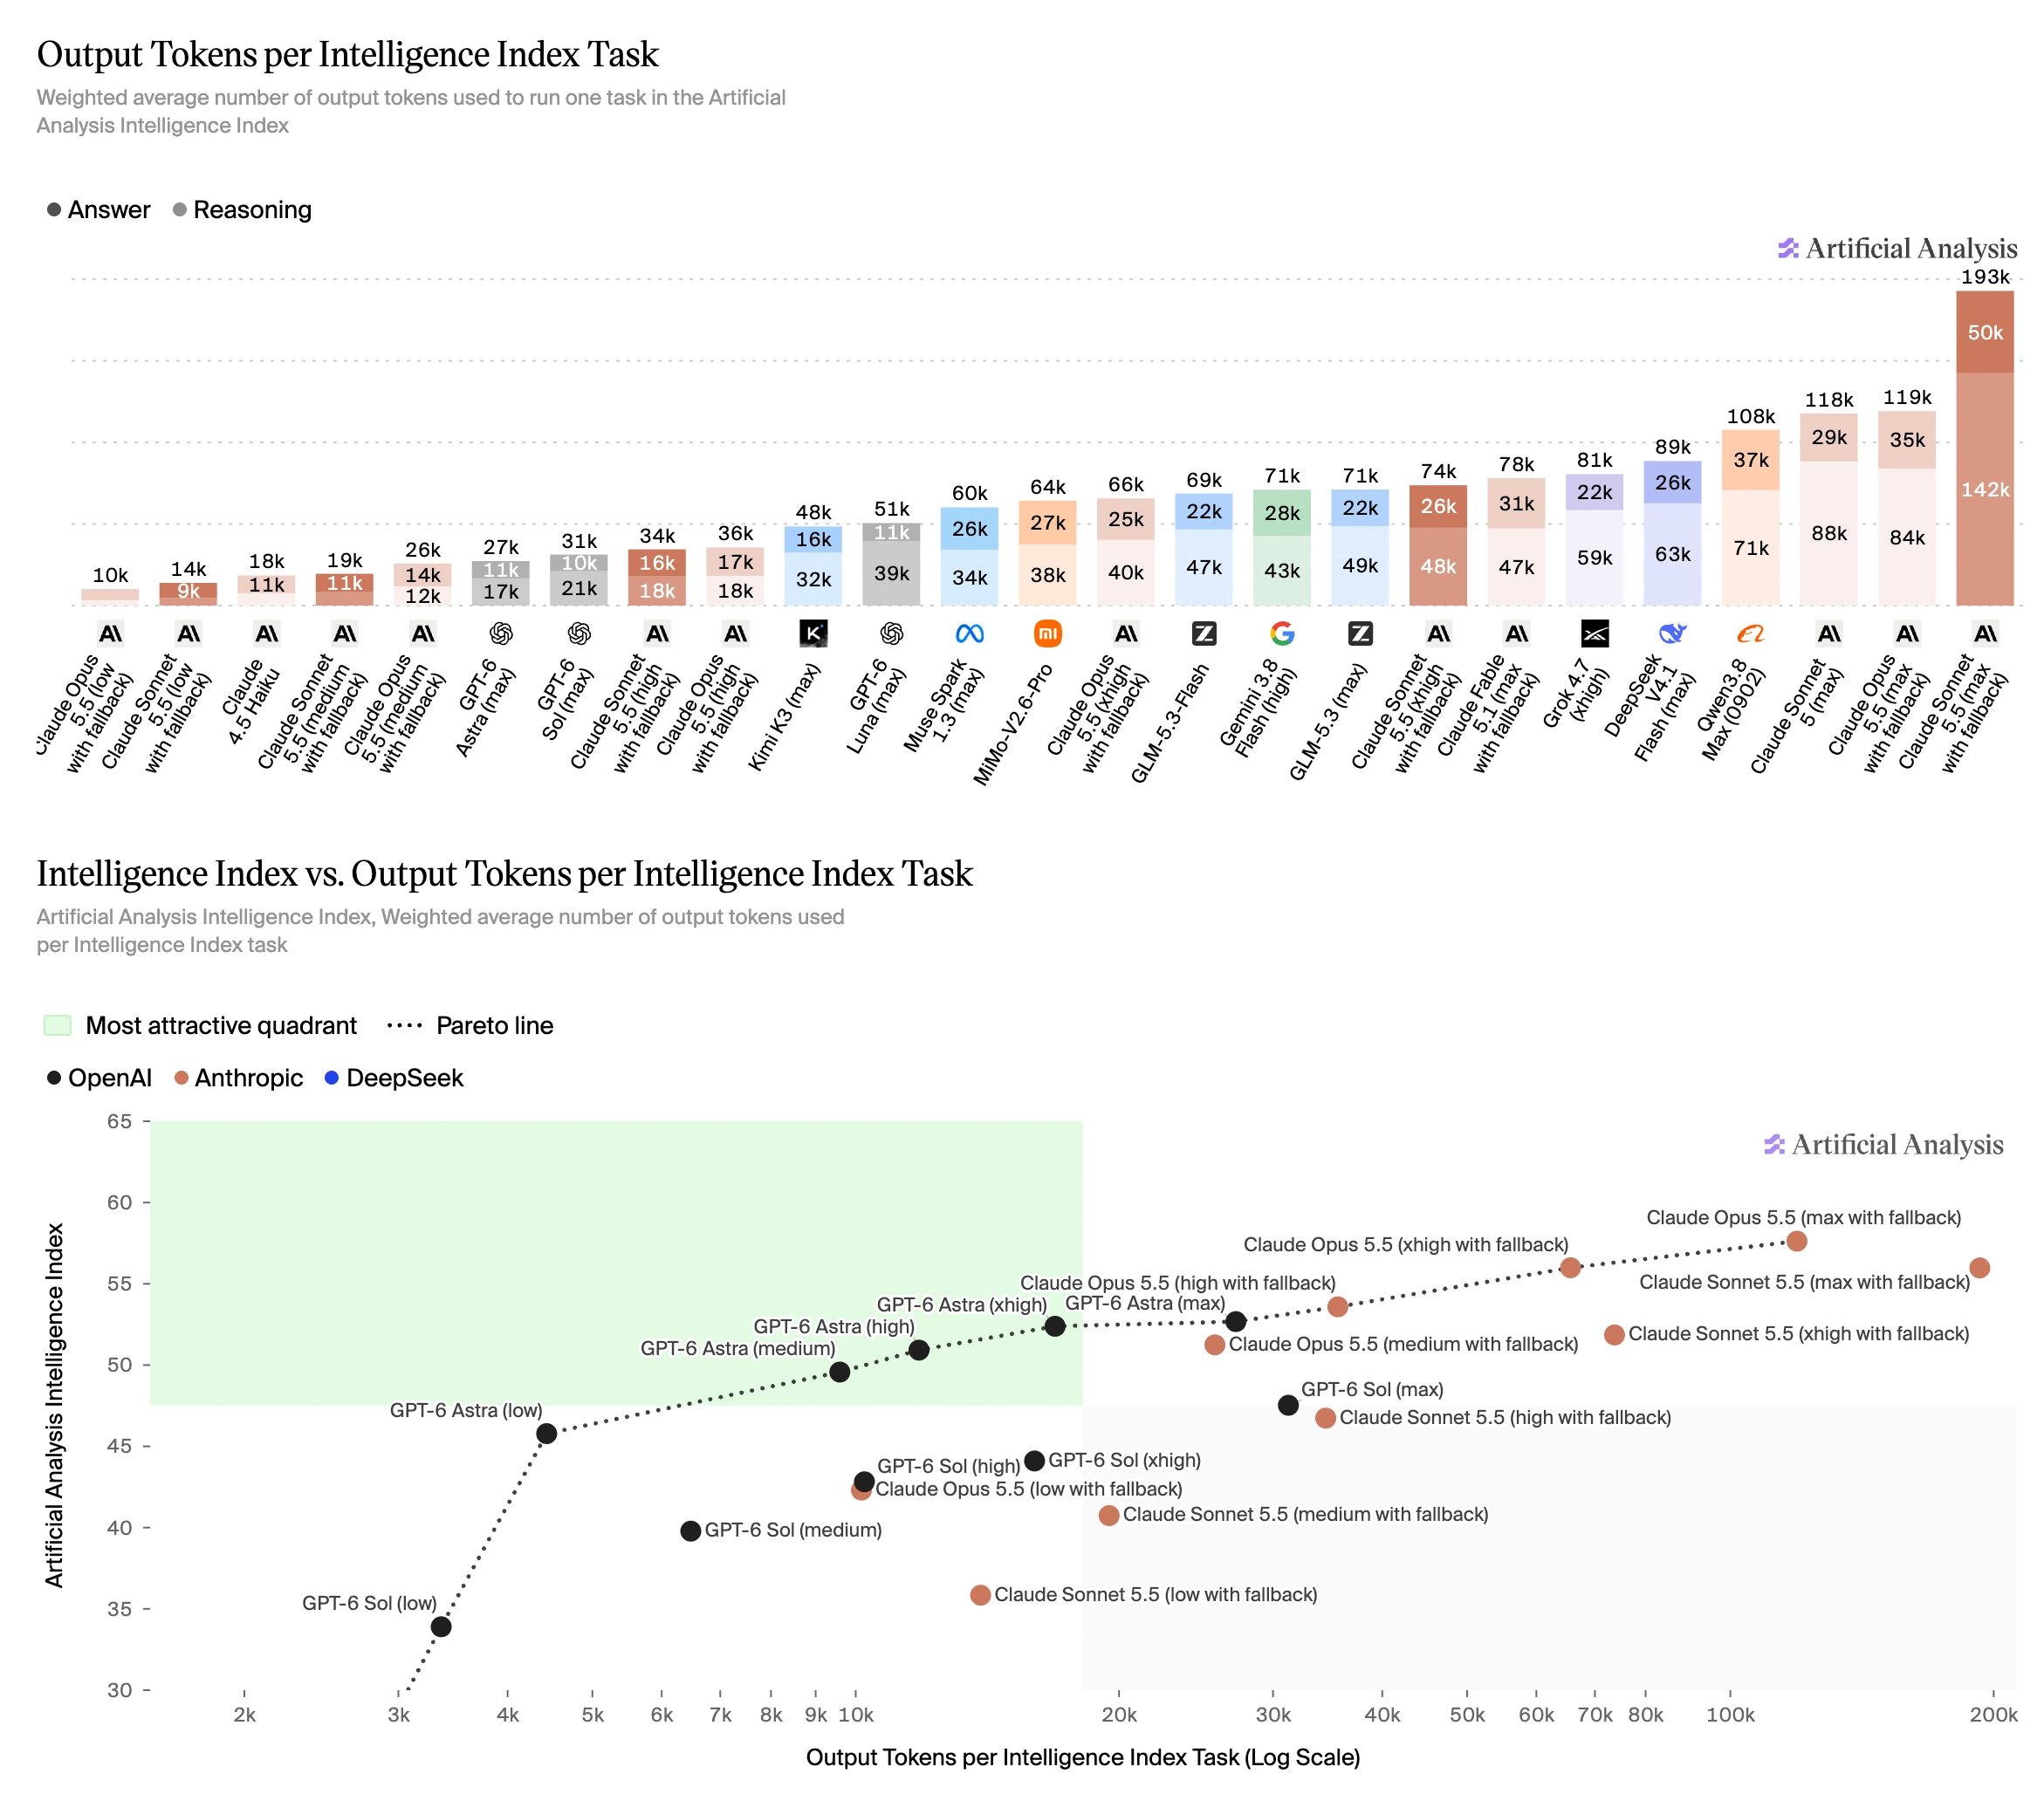
Artificial Analysis measures Sonnet 5.5 (max) at about 193k output tokens per Intelligence Index task, roughly 7x GPT-6 Astra (max), though its lower effort settings trail GPT-6 Sol on efficiency.
To achieve its outsized performance, Claude Sonnet 5.5 (max) uses ~193k output tokens per Intelligence Index task, the most we have measured and ~7x that of GPT-6 Astra (max). However, its lower effort settings span a broader area of Intelligence versus Output Tokens per Task tradeoffs, with low, medium, and high effort settings sitting behind GPT-6 Sol high, xhigh, and max efforts - in this area Sol provides higher performance with fewer output tokens.
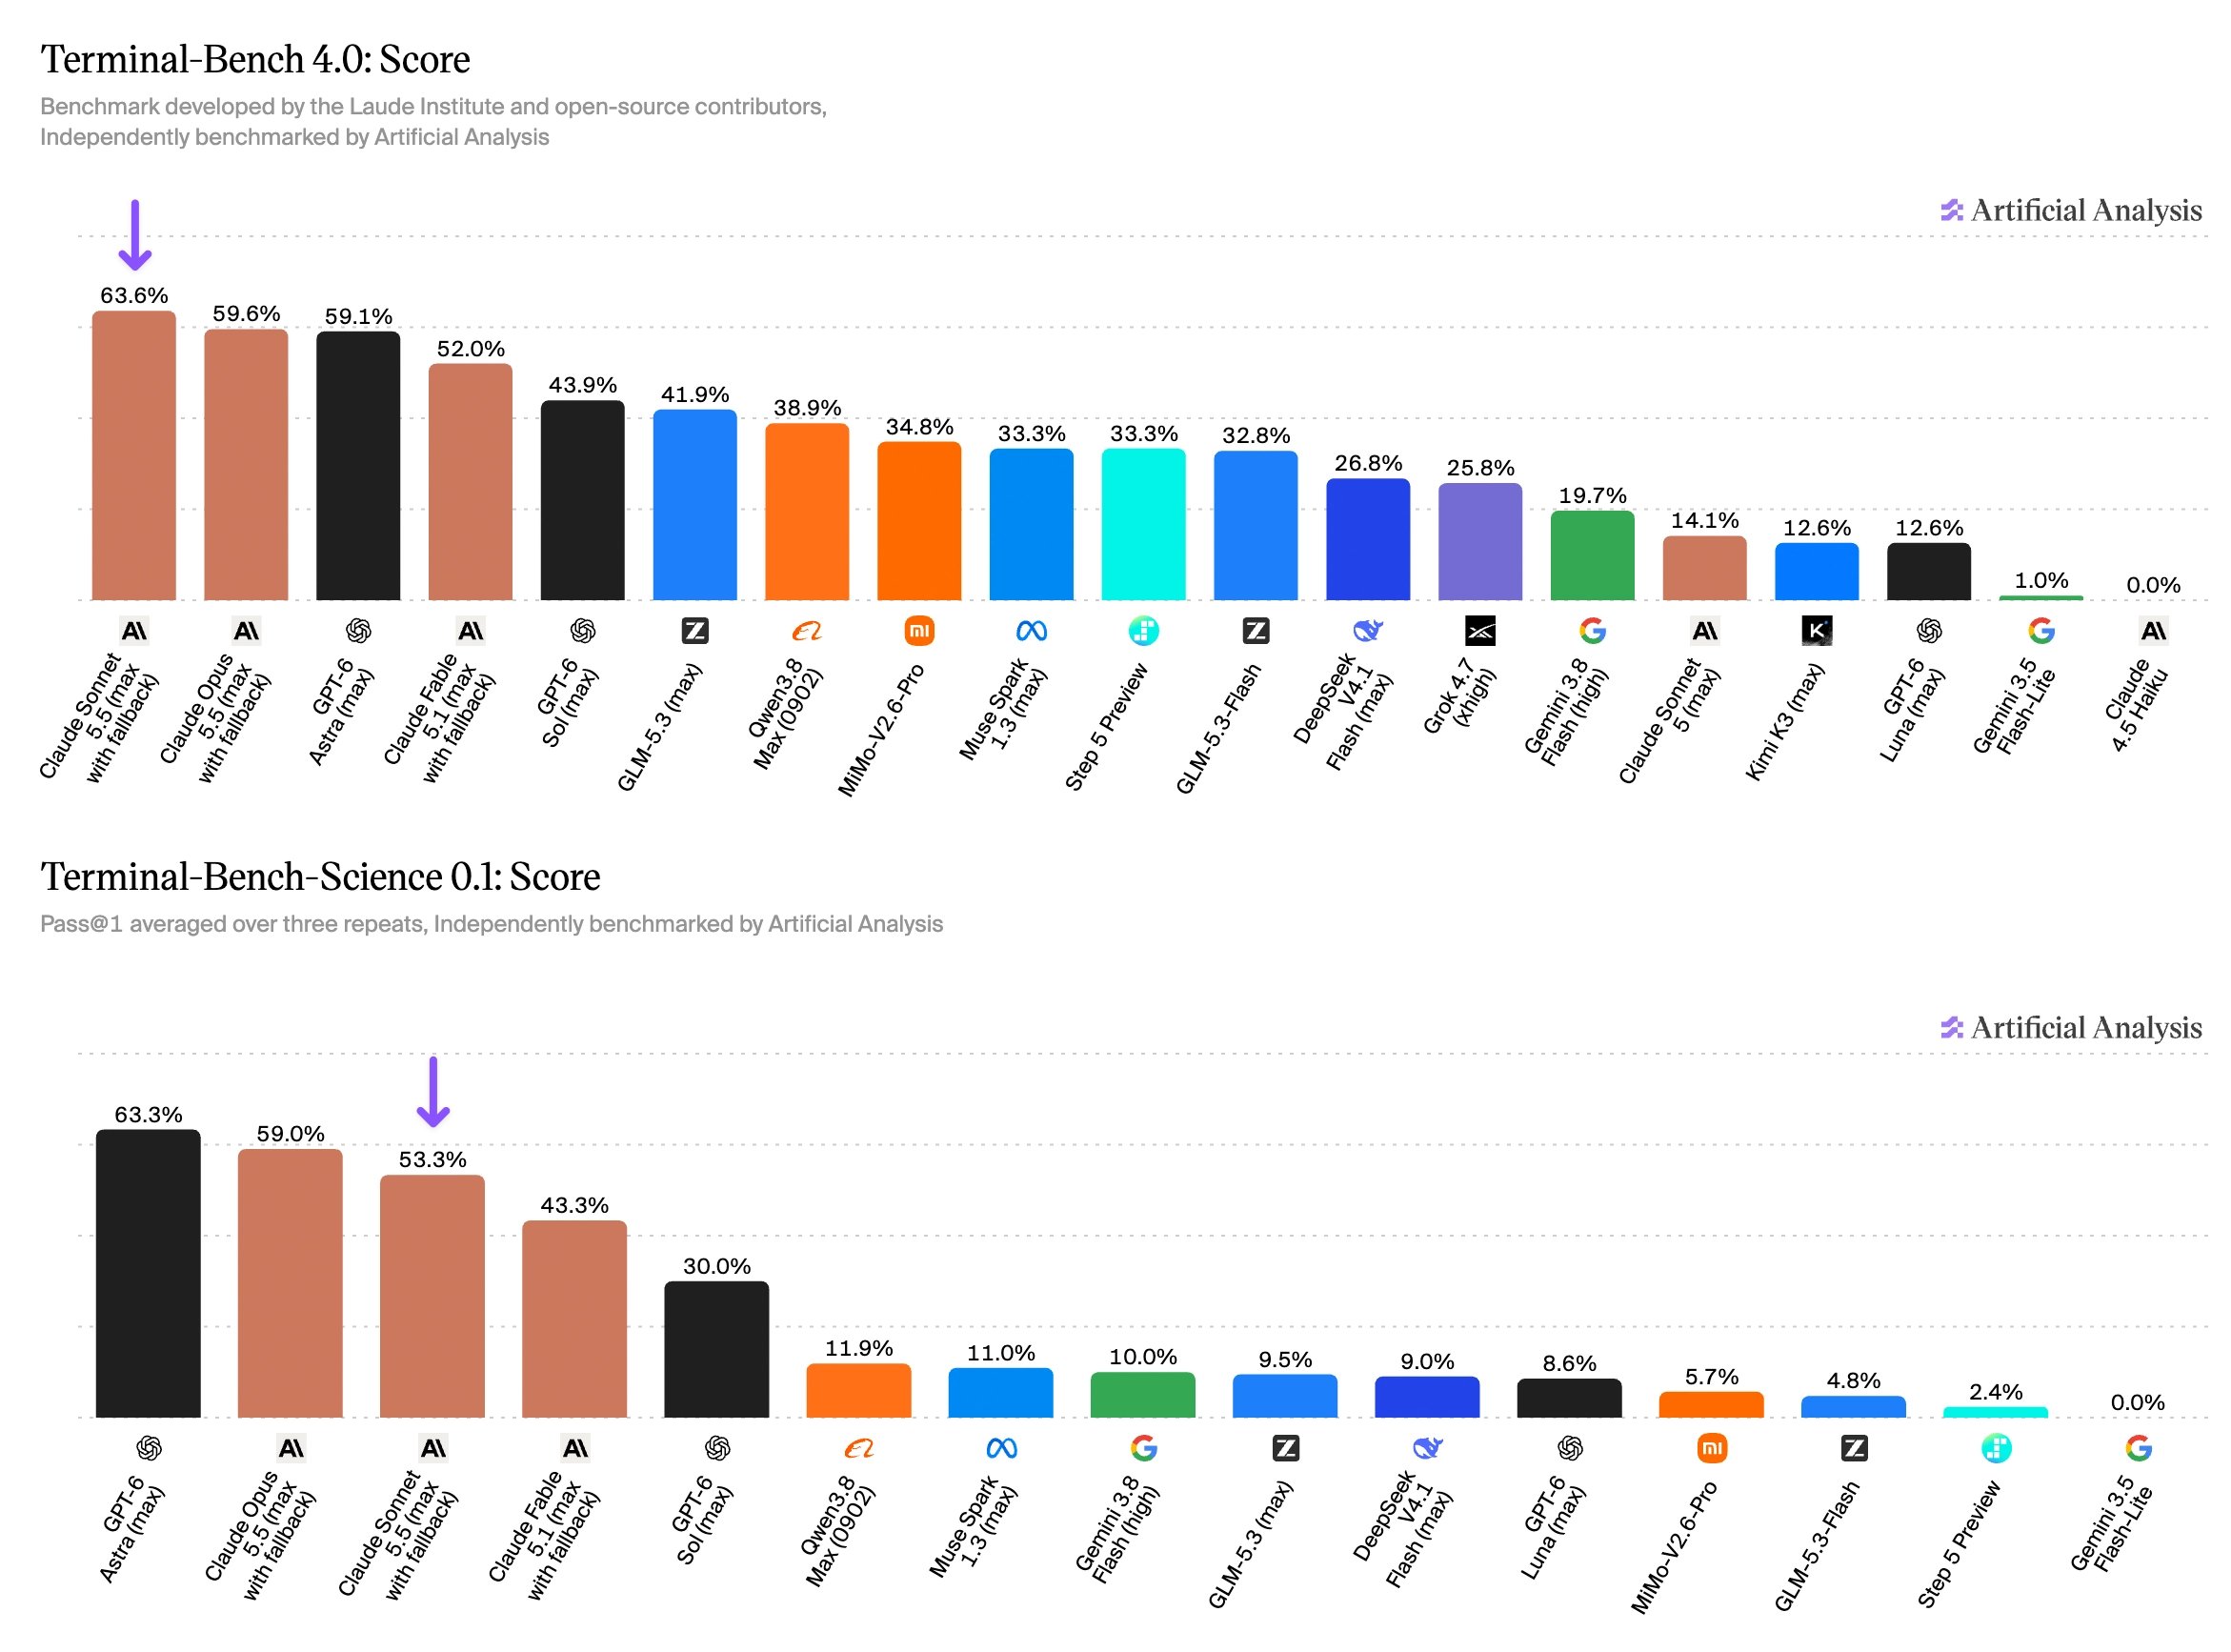
Claude Sonnet 5.5 (max) makes large strides on Terminal-Bench, sitting among the top models for both Terminal-Bench 4.0 and Terminal-Bench-Science. In Terminal-Bench 4.0 it scores 64%, a 50 point increase over Claude Sonnet 5 (max), and slightly above 60% for Opus 5.5 and GPT-6 Astra (xhigh). On our leaderboard for Terminal-Bench-Science - a benchmark of agentic terminal use to complete realistic scientific research workflows across domains - it scores 53% and sits behind only GPT-6 Astra and Opus 5.5. Terminal-Bench-Science is not currently included in the Artificial Analysis Intelligence Index.