Upstage Solar Mini 4: matches Astra on long context, weak on agentic coding
Upstage's new Solar Mini 4 matches GPT-6 Astra on long-context reasoning at 81% but scores only 1% on Terminal-Bench.
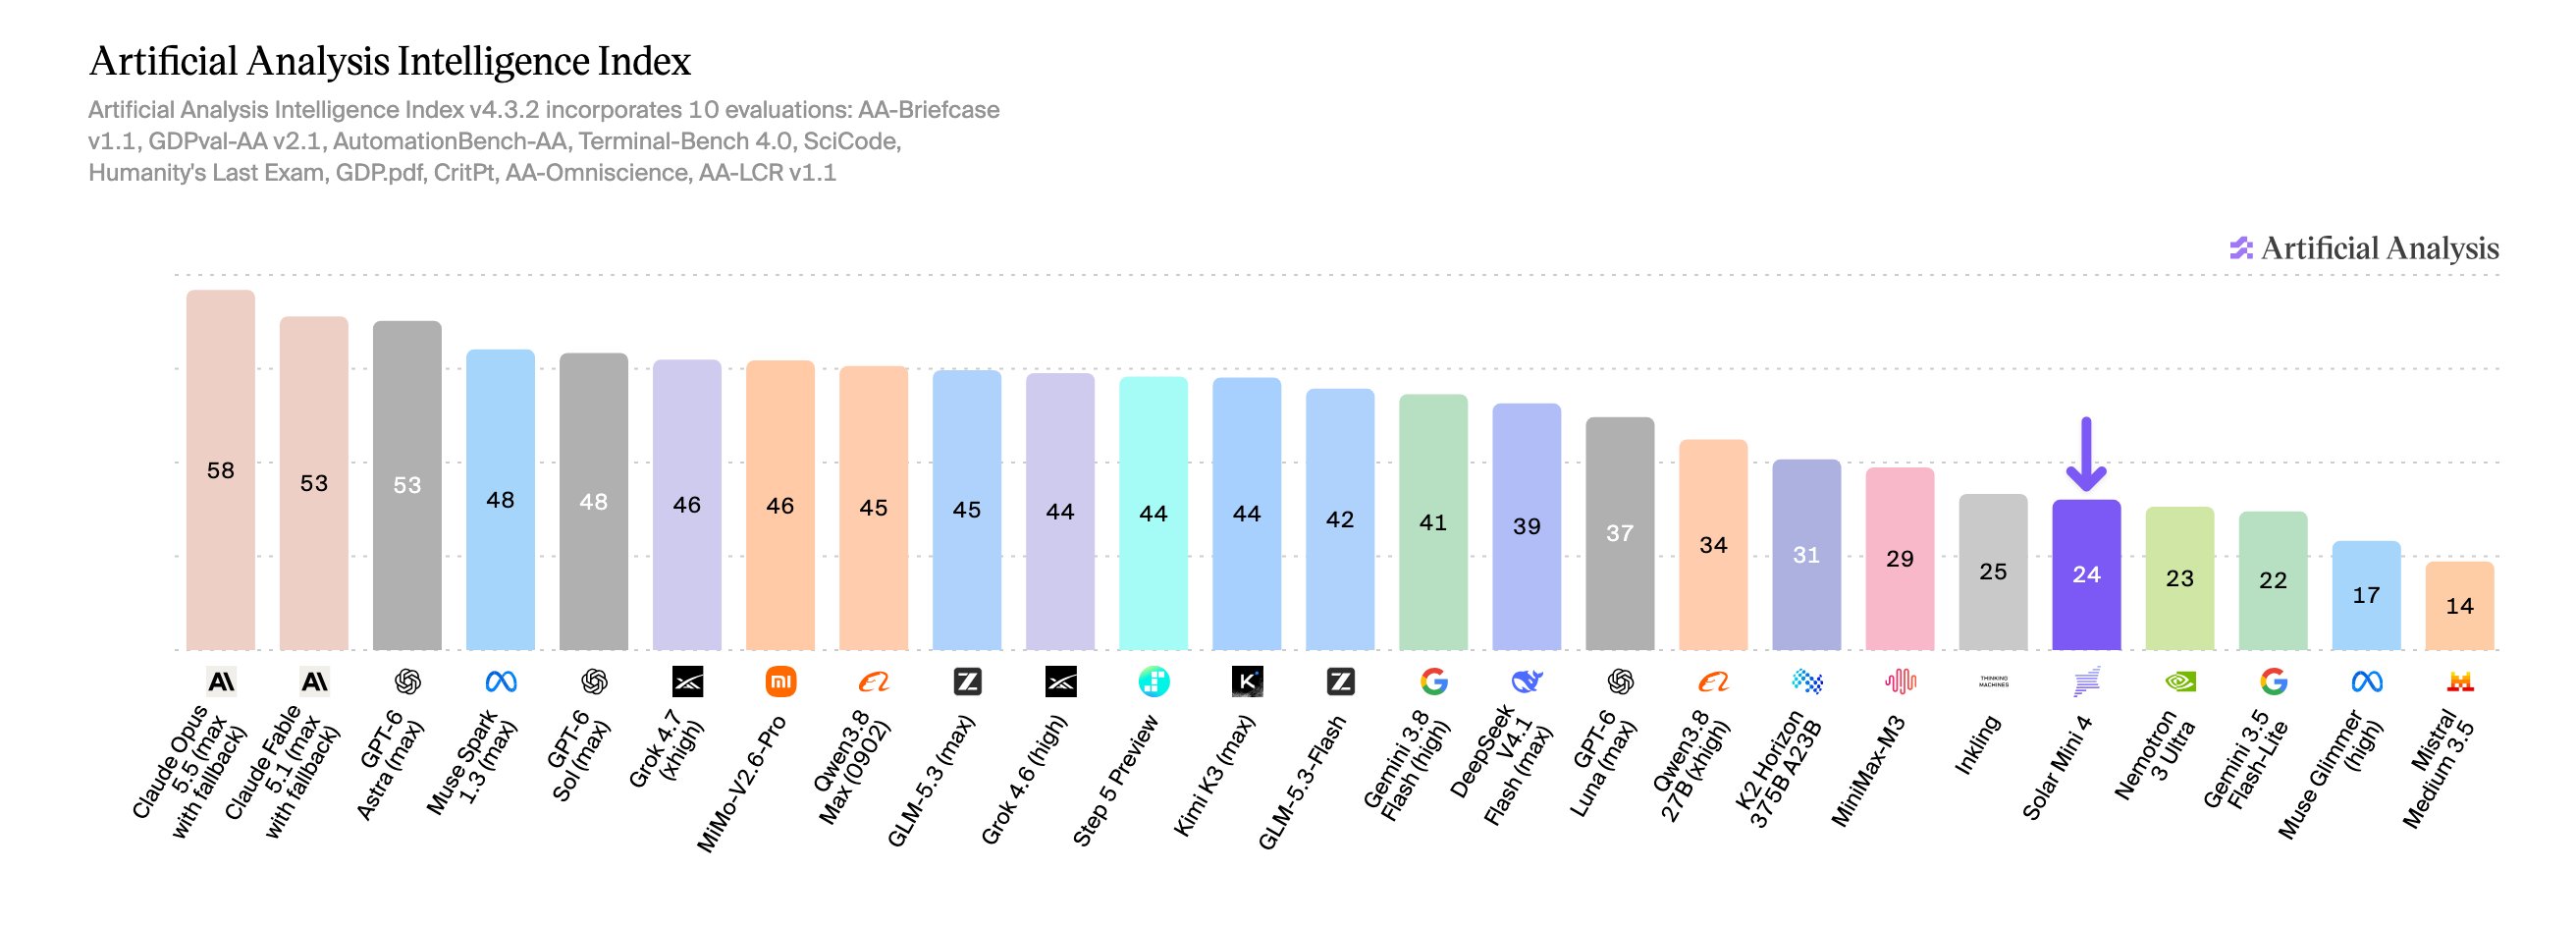
Korean AI Lab 🇰🇷 Upstage has released Solar Mini 4 which scores 24 on the Artificial Analysis Intelligence Index, but costs ~5x as much per task as GPT-6 Luna (max) despite similar per-token prices Upstage has released Solar Mini 4, a new proprietary reasoning model. Upstage reports 35B total and 3B active parameters, setting a new Pareto optimal point on Intelligence Index vs. Active Parameters for models under 3B active parameters. It also scores 16 points higher than Upstage's previous-generation flagship, Solar Pro 3 (8), and cuts per-token pricing by a third to $0.10/$0.40 per 1M input/output tokens. Key results: ➤ Strong for its reported active parameter size: Solar Mini 4 scores 6 points higher than Qwen3.6 35B A3B (Reasoning), which has the same 3B active parameters, and 1 point higher than Nemotron 3 Ultra, which has 55B active. As a proprietary model, its size cannot be independently verified. ➤ Long context reasoning is a relative strength: It scores 83% on AA-LCR v1.1, matching MiniMax-M3 and GPT-6 Luna (max), and ahead of Gemini 3.8 Flash (high) and GPT-6 Astra (max) at 81%. It also scores 48% on SciCode, ahead of MiniMax-M3 and Inkling (xhigh) at 47%. ➤ Fast output, but slow tasks: Solar Mini 4 generates 208 tokens/s as of launch date, faster than GPT-6 Luna (max) at 152 tokens/s. However, it uses 88k output tokens per Intelligence Index task, so it averages 7.1 minutes per task. ➤ Agentic coding is a relative weakness: It scores 1% on Terminal-Bench 4.0 and 22% on AutomationBench-AA. On agentic knowledge work, it scores 1072 Elo on GDPval-AA and 872 Elo on AA-Briefcase, close to Inkling (xhigh). ➤ Low knowledge accuracy, but also relatively high non-hallucination rate: Solar Mini 4 scores -11 on AA-Omniscience with 18% accuracy. It abstains on about half of the questions, and scores 64% on non-hallucination rate, higher than Inkling (xhigh) at 32% and GPT-6 Luna (max) at 23%. Additional model details: ➤ Context window: 1M tokens ➤ Max output tokens: 262k ➤ License: Proprietary, with weights not released ➤ Parameters: 35B total, 3B active (reported by Upstage) ➤ Modalities: Text input and output only ➤ Knowledge cutoff: February 2026 ➤ Pricing: $0.10/$0.40/$0.01 per 1M input/output/cache hit tokens