Artificial Analysis: GPT-6 models on the speed-score Pareto frontier
GPT-6 Luna, Astra and Sol are fast because they use only 27k–48k output tokens per task, putting them on the Pareto frontier alongside Claude Opus 5.5.
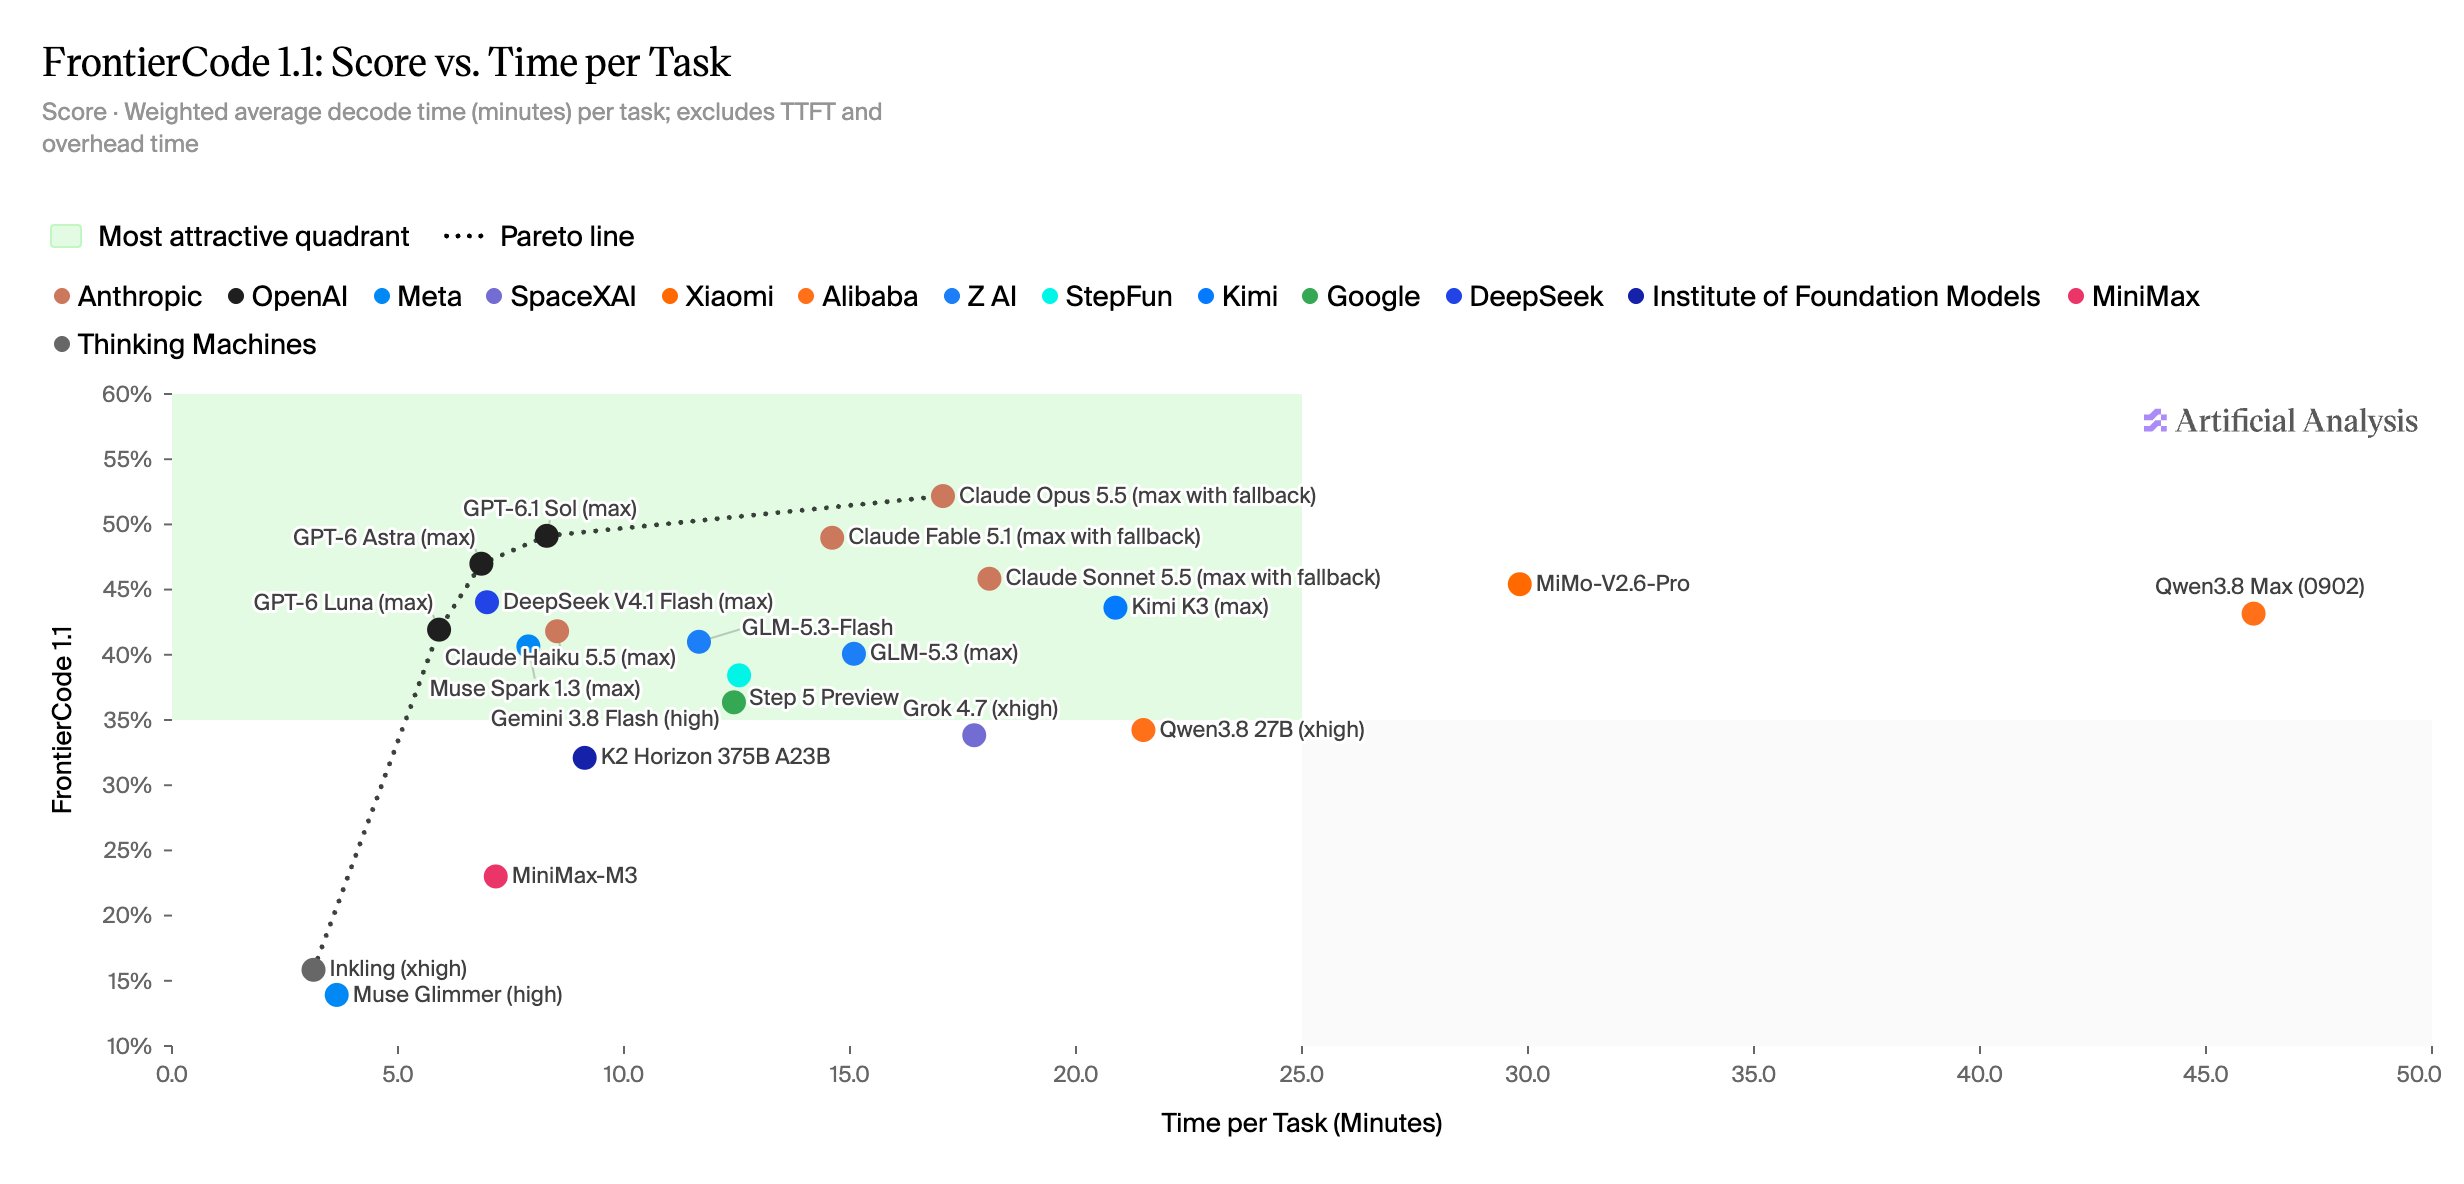
GPT-6 Luna (max), GPT-6 Astra (max), GPT-6.1 Sol (max) and Claude Opus 5.5 (max with fallback) sit on the Pareto frontier for score vs. Time per Task. We estimate Time per Task from each model's token usage and our live output speed measurements. The GPT-6 models are fast because they use few tokens, at 27k to 48k output tokens per task. DeepSeek V4.1 Flash (max) uses ~119k but is served quickly, averaging ~7 minutes per task, around 40% of the time of Claude Opus 5.5 (max with fallback) at ~17 minutes.
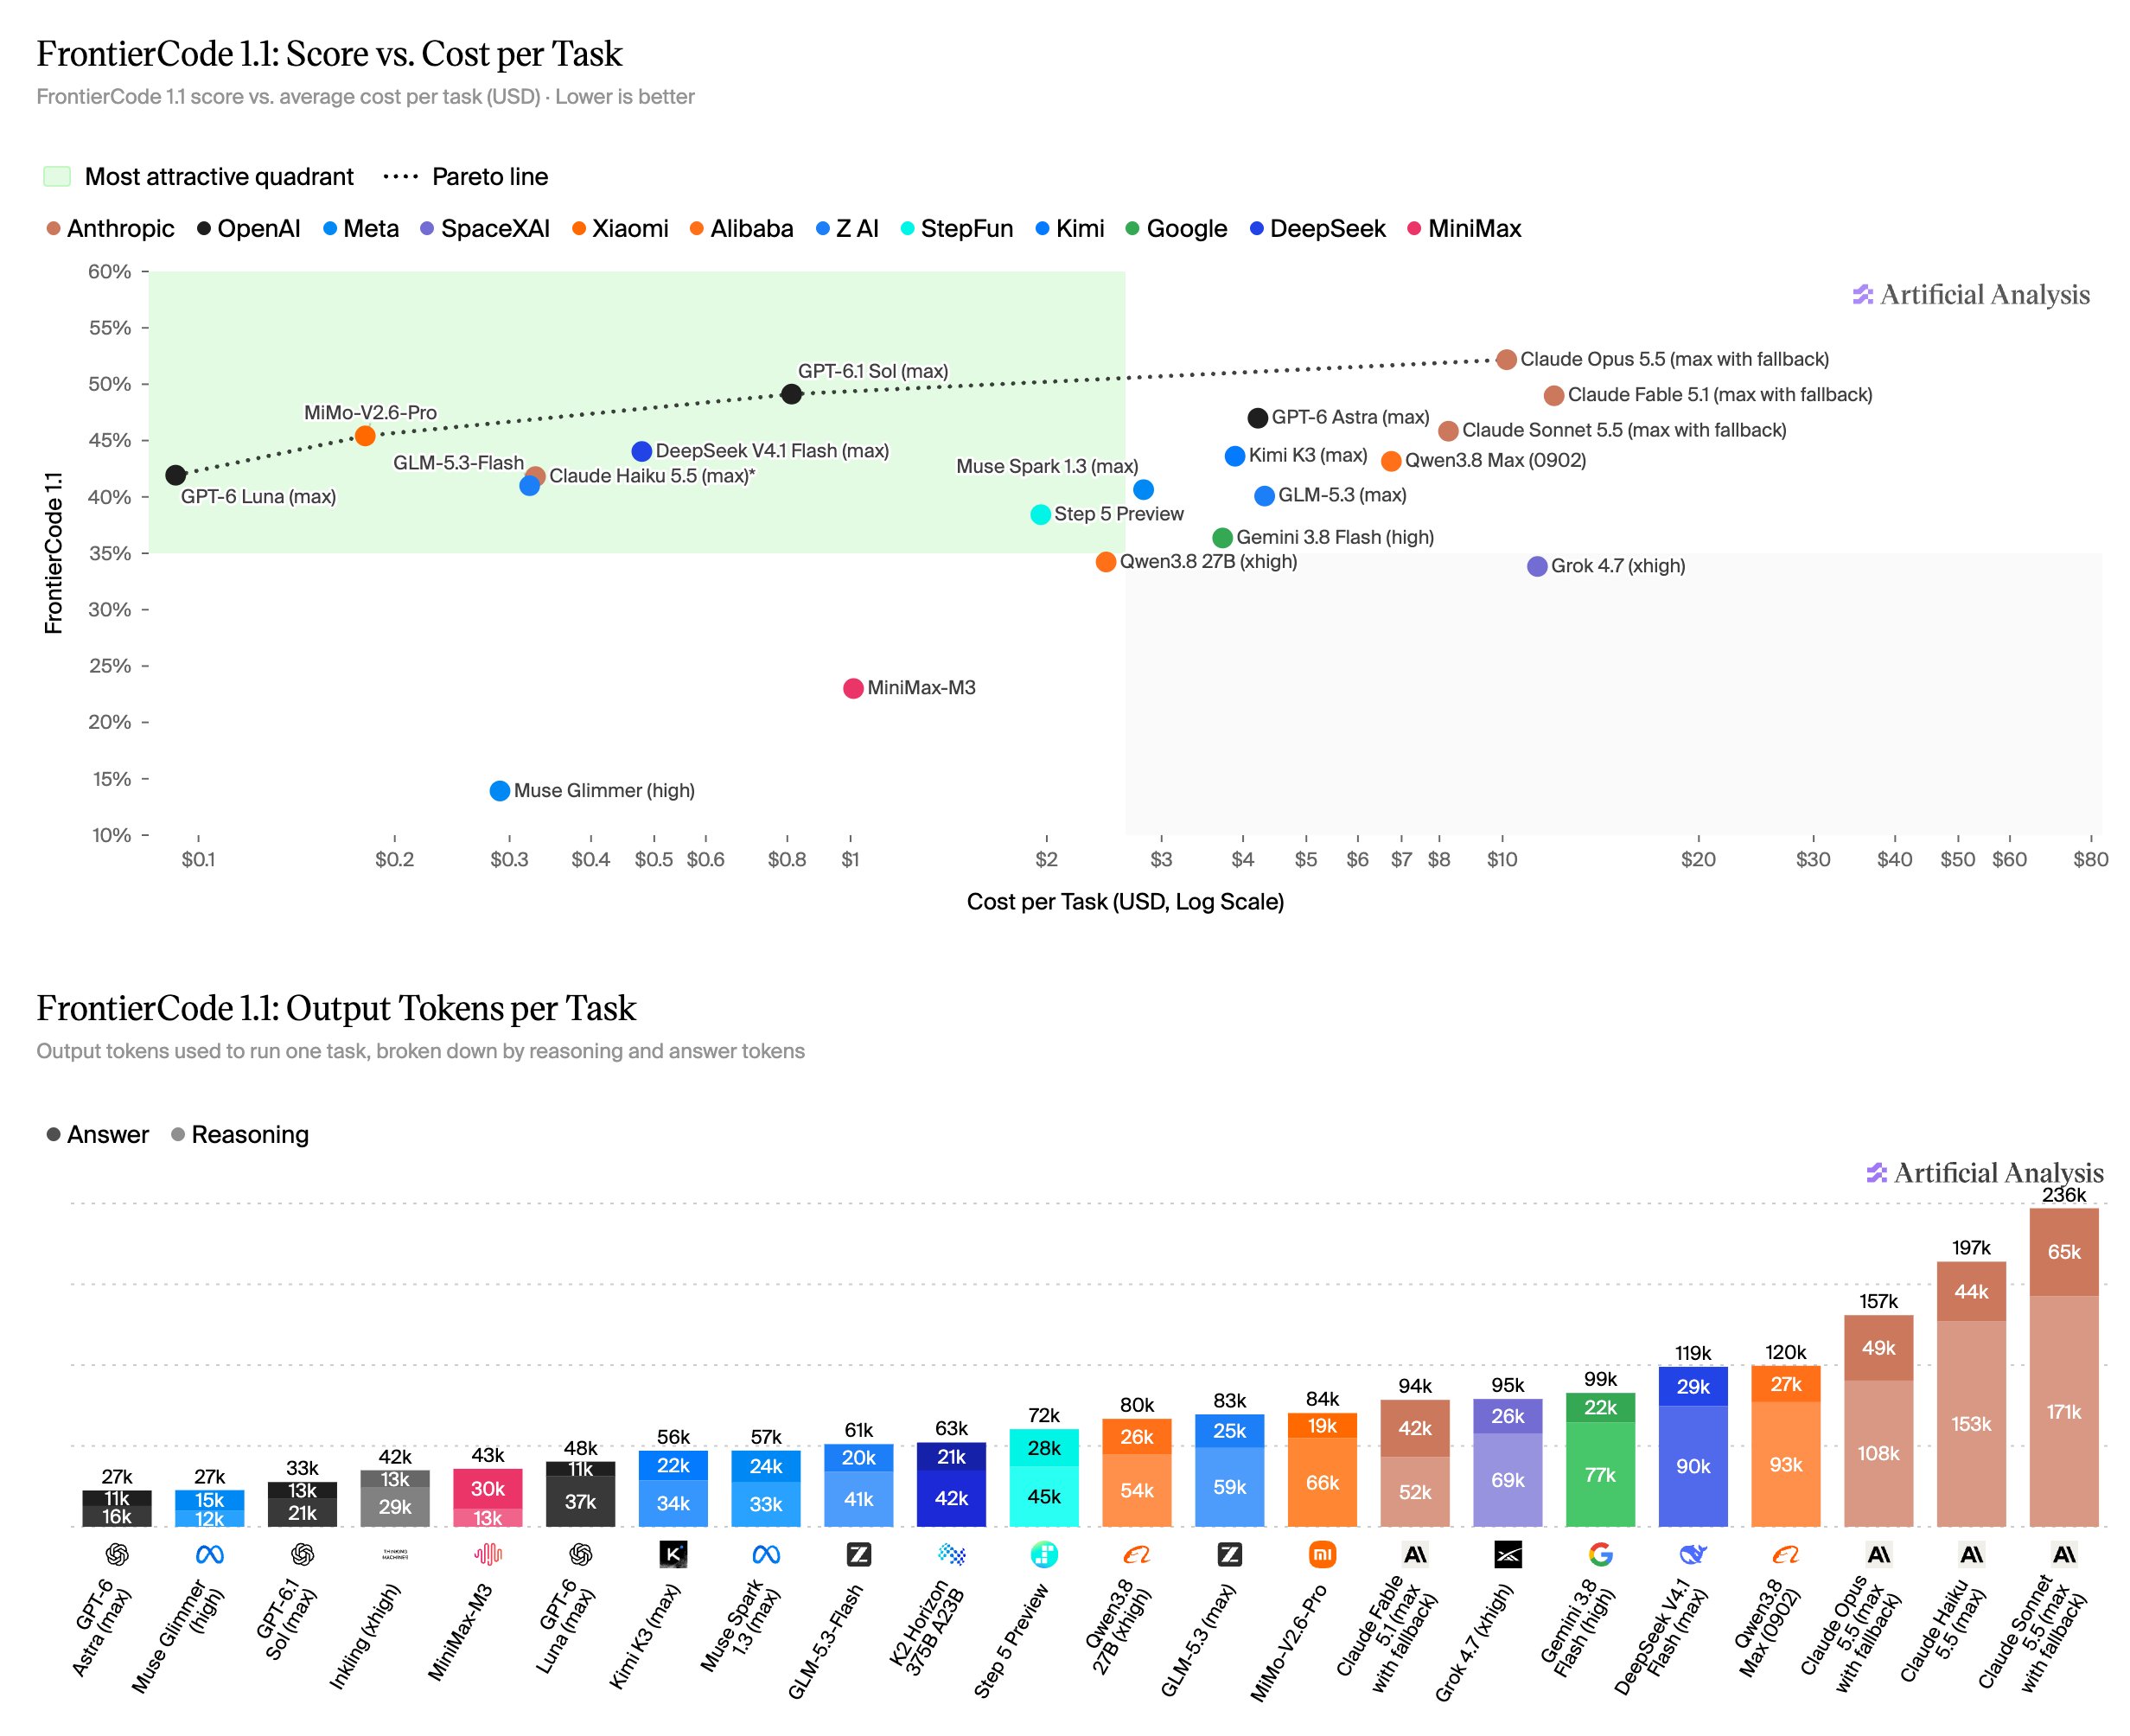
Cost per Task on FrontierCode spans two orders of magnitude, from $0.09 for GPT-6 Luna (max) to $12.00 for Claude Fable 5.1 (max with fallback). Four models sit on the Pareto frontier for score vs. Cost per Task: GPT-6 Luna (max) at 42% and $0.09 per task, MiMo-V2.6-Pro at 45% and $0.18, GPT-6.1 Sol (max) at 49% and $0.81, and Claude Opus 5.5 (max with fallback) at 52% and $10.15. GPT-6 models led on token efficiency in our testing. GPT-6 Astra (max) and GPT-6.1 Sol (max) averaged 27k and 33k output tokens per task respectively, compared with 157k for Claude Opus 5.5 (max with fallback) and 236k for Claude Sonnet 5.5 (max with fallback).