deepseek-v4.1IMAGE
FrontierCode v1.1: DeepSeek V4.1 Flash scores 52.6%, behind Opus 5.5
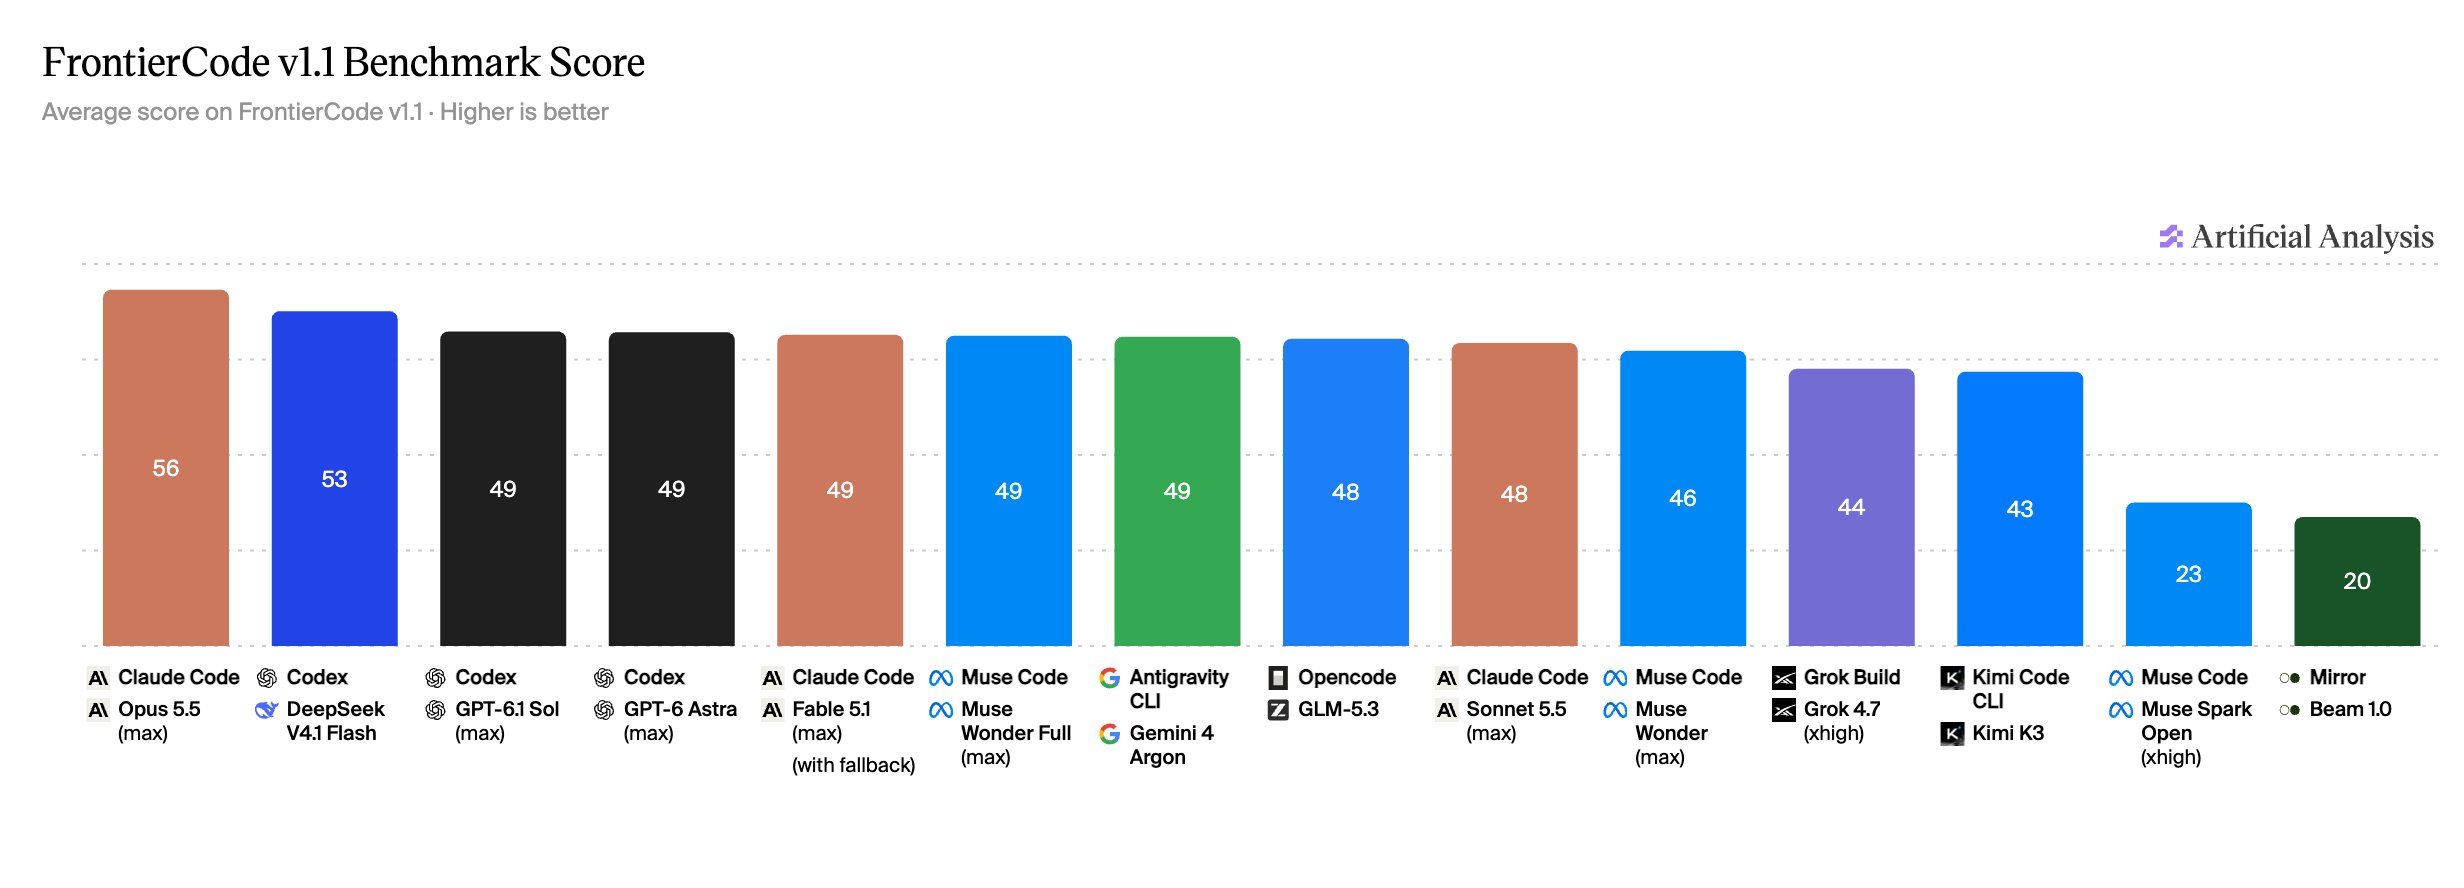
On the new FrontierCode v1.1 benchmark, Codex with DeepSeek V4.1 Flash scores 52.6%, below Claude Opus 5.5 at 56.0% and above GPT-6.1 Sol and GPT-6 Astra.
Artificial Analysis
@ArtificialAnlysArchived 9 days agoOriginally posted 2026.10.23
Artificial Analysis @ArtificialAnlysOriginally posted 2026.10.23
FrontierCode v1.1 replaces DeepSWE v1.1 in the Index. Cognition's benchmark has 100 software engineering tasks on real open-source repositories with a private test set, graded on whether a maintainer would merge the change. Claude Code with Claude Opus 5.5 (max) scores 56.0%, ahead of Codex with DeepSeek V4.1 Flash (max) at 52.6%, Codex with GPT-6.1 Sol (max) at 49.4% and Codex with GPT-6 Astra (max) at 49.3%. Below the top, scores are tightly packed: 15 of the 24 configurations on the Index score between 43% and 49%.
x.com/artificialanlys/status/2113424556069372203Archived 2026.10.23 12:05