Copilot Fusion debuts as Gemini 4 Argon appears in Antigravity CLI
Artificial Analysis reports Copilot Fusion leads Terminal-Bench 4.0 at 71 and scores 57 on SWE-Atlas-QnA, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
Copilot Fusion in GitHub Copilot lands with a slight lead in Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI.
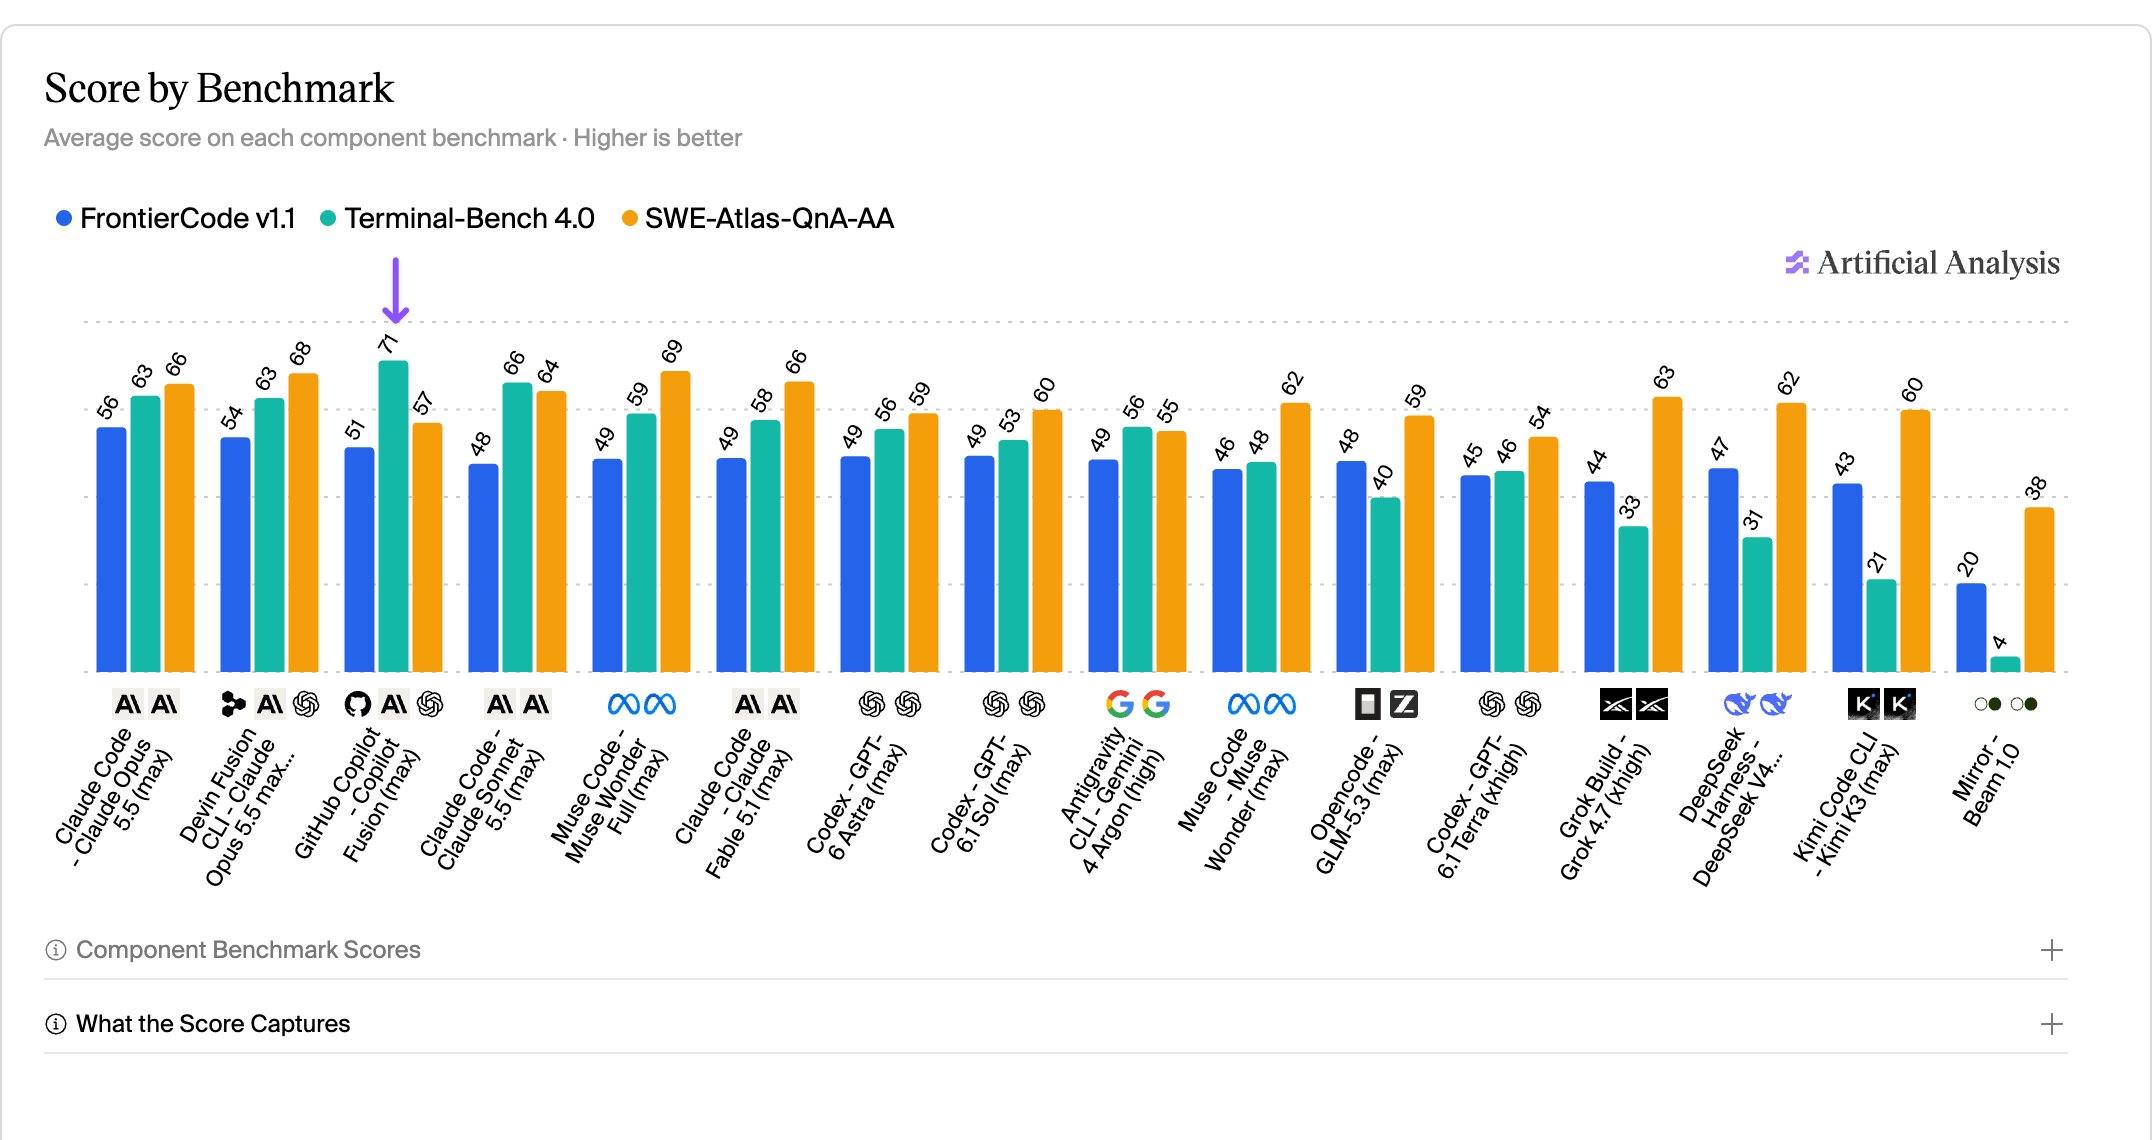
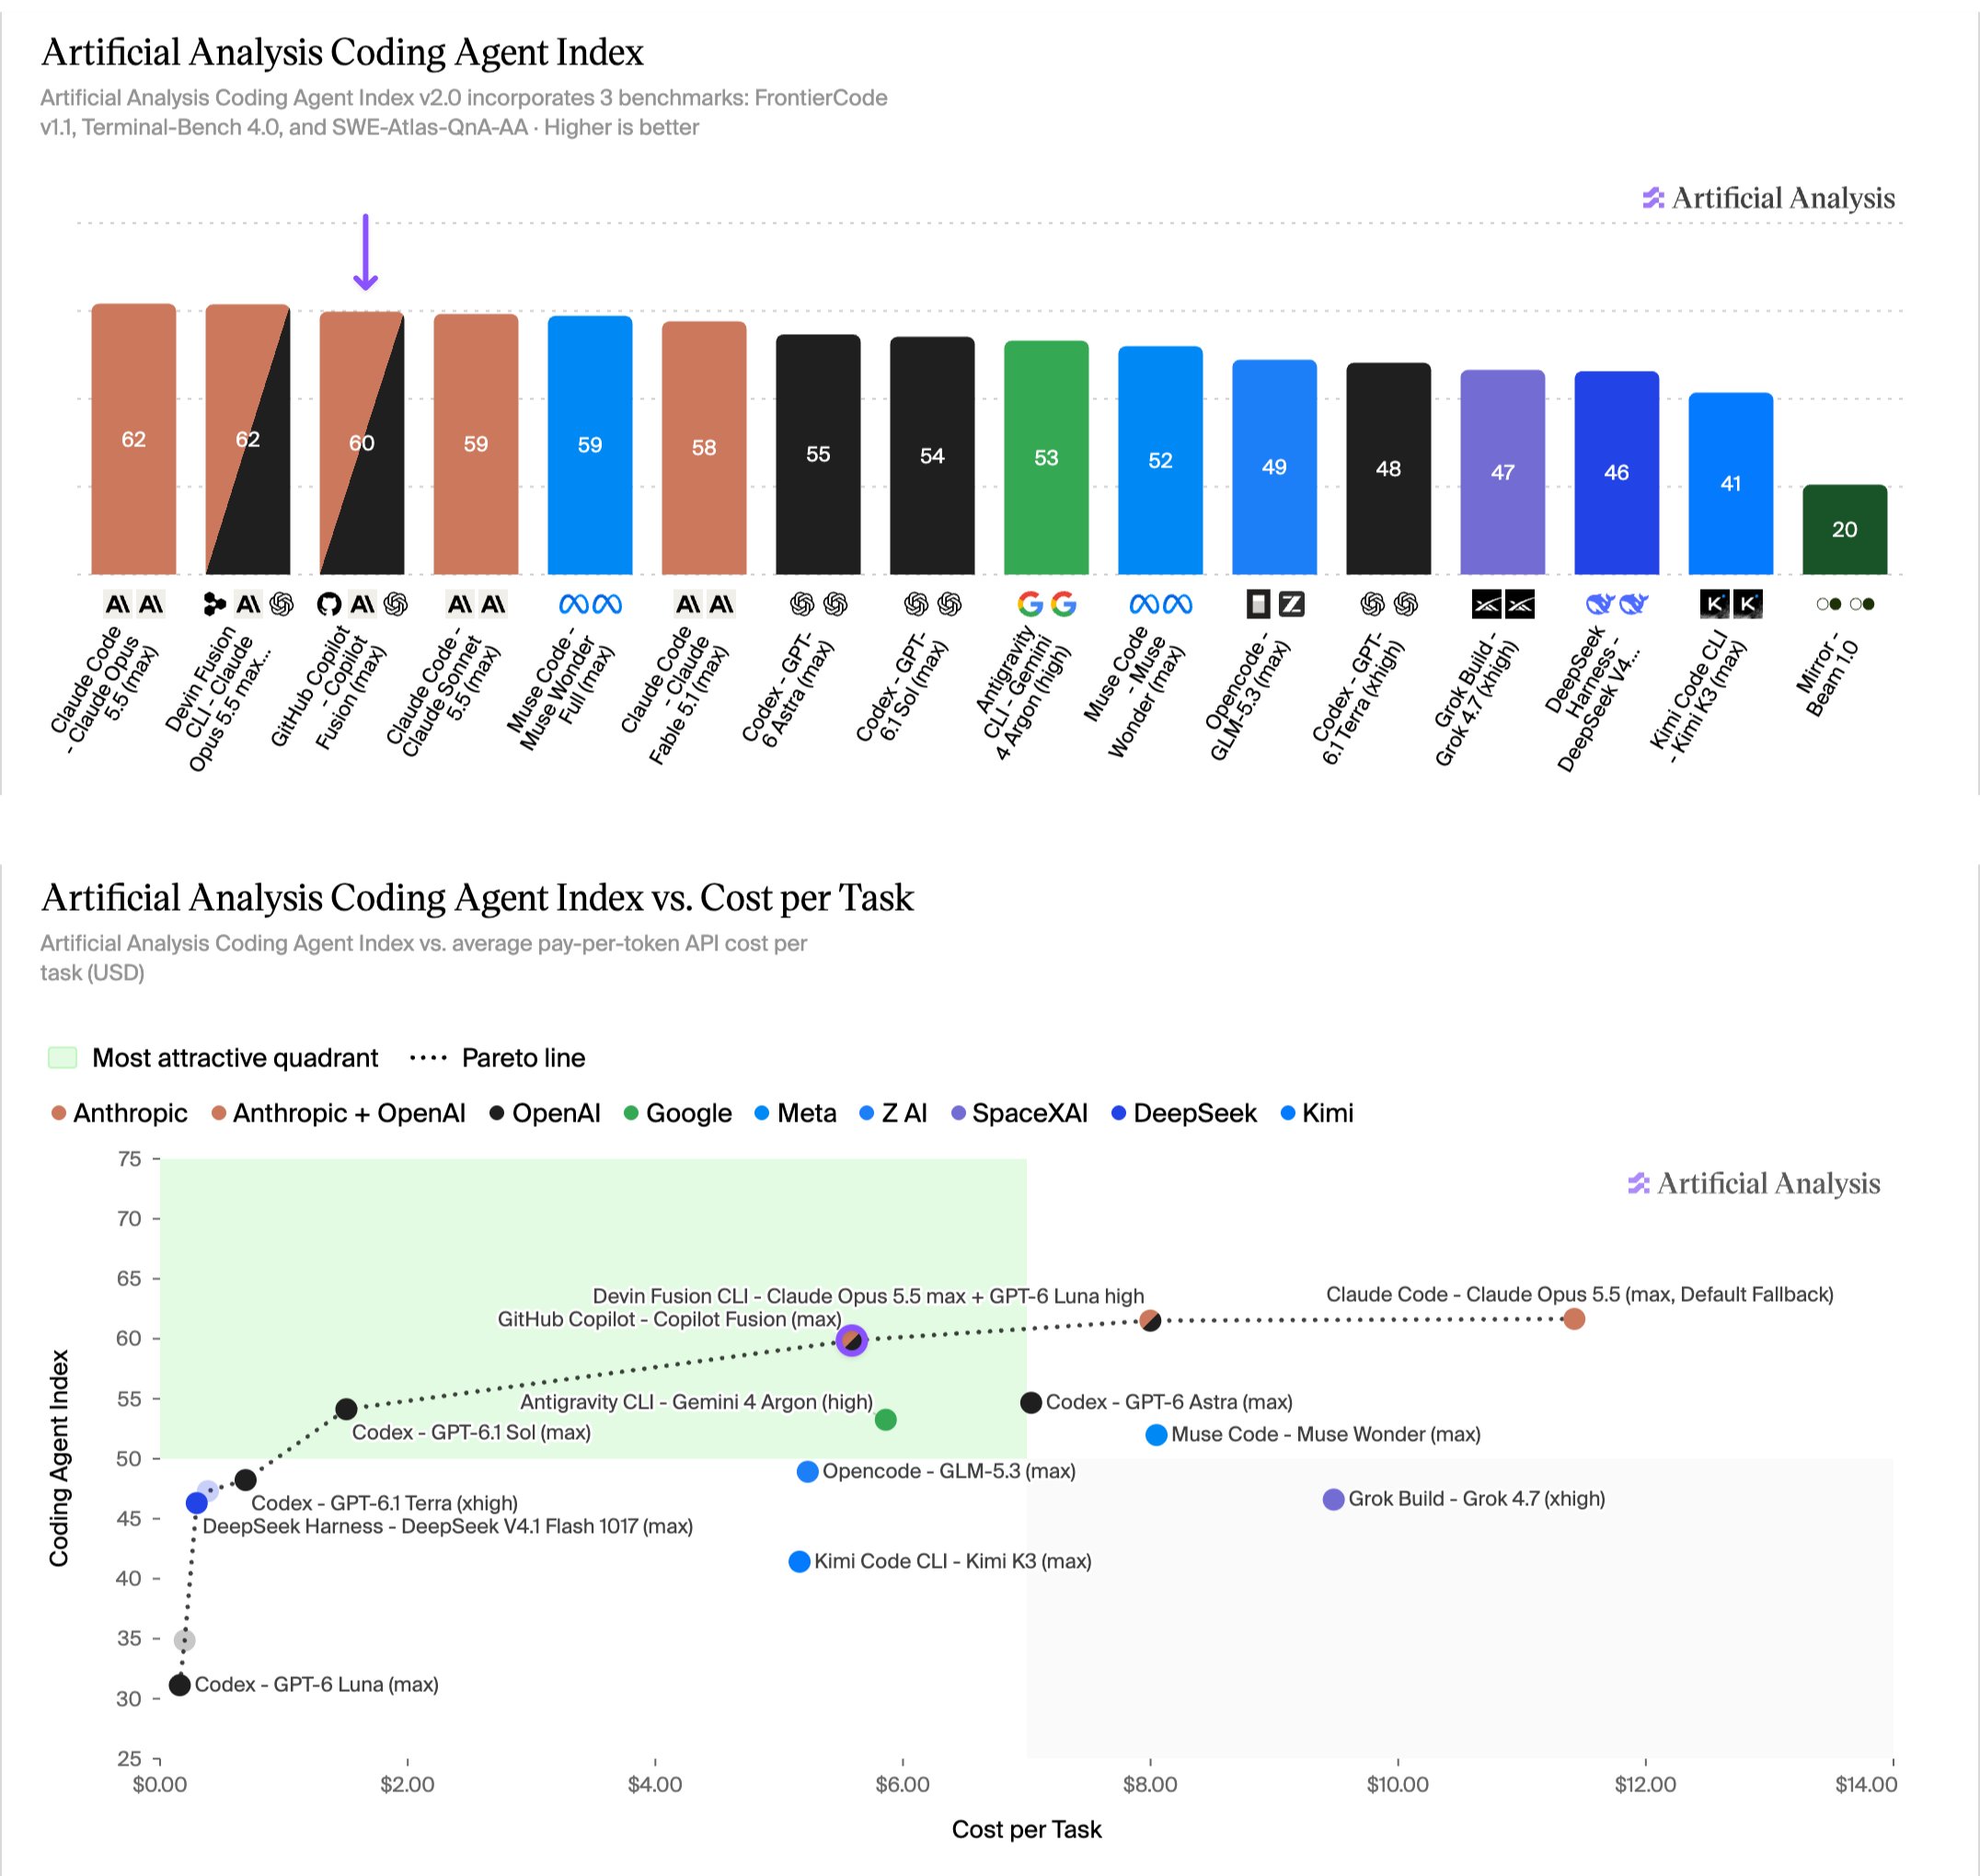
GitHub has released Copilot Fusion in GitHub Copilot, which orchestrates between Anthropic and OpenAI models. It scores 2 points below Opus 5.5 in Claude Code at half the Cost per Task in the Coding Agent Index GitHub describes Copilot Fusion as a runtime orchestration system, which selects and coordinates models to optimize performance, cost, and latency for each task. Copilot Fusion chooses between a number of models from Anthropic and OpenAI, including Claude Opus 5.5, Claude Sonnet 5.5, GPT-6 Astra, and GPT-6 Sol. We benchmarked its max setting in GitHub Copilot CLI in the Artificial Analysis Coding Agent Index v2.0. Token costs are charged based on the underlying models used to complete a request. Key takeaways: ➤ Cost-efficient for near-frontier performance: Copilot Fusion in GitHub Copilot costs $5.59 per task, versus $11.42 for Claude Code with Opus 5.5 (max). Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) scores 62 at $8.00 per task. ➤ Slight lead in Terminal-Bench 4.0: The Coding Agent Index v2.0 weights its three constituent benchmarks equally. Copilot Fusion in GitHub Copilot leads Terminal-Bench 4.0 with a score of 71. It ranks third on FrontierCode in the chart at 51, behind Claude Code with Opus 5.5 (max) at 56 and Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high) at 54. Its SWE-Atlas-QnA-AA score lags at 57, between GPT-6 Astra in Codex and Gemini 4 Argon in Antigravity CLI. ➤ Half the token use of Opus 5.5 in Claude Code: GitHub Copilot Fusion used 7.2M tokens per task in the Coding Agent Index, approximately half of the tokens used by Claude Opus 5.5 in Claude Code, and 30% less than Devin Fusion with Opus 5.5 (max) + GPT-6 Luna (high).