aiIMAGE
RRSI: Regularized self-improvement helps agents generalize
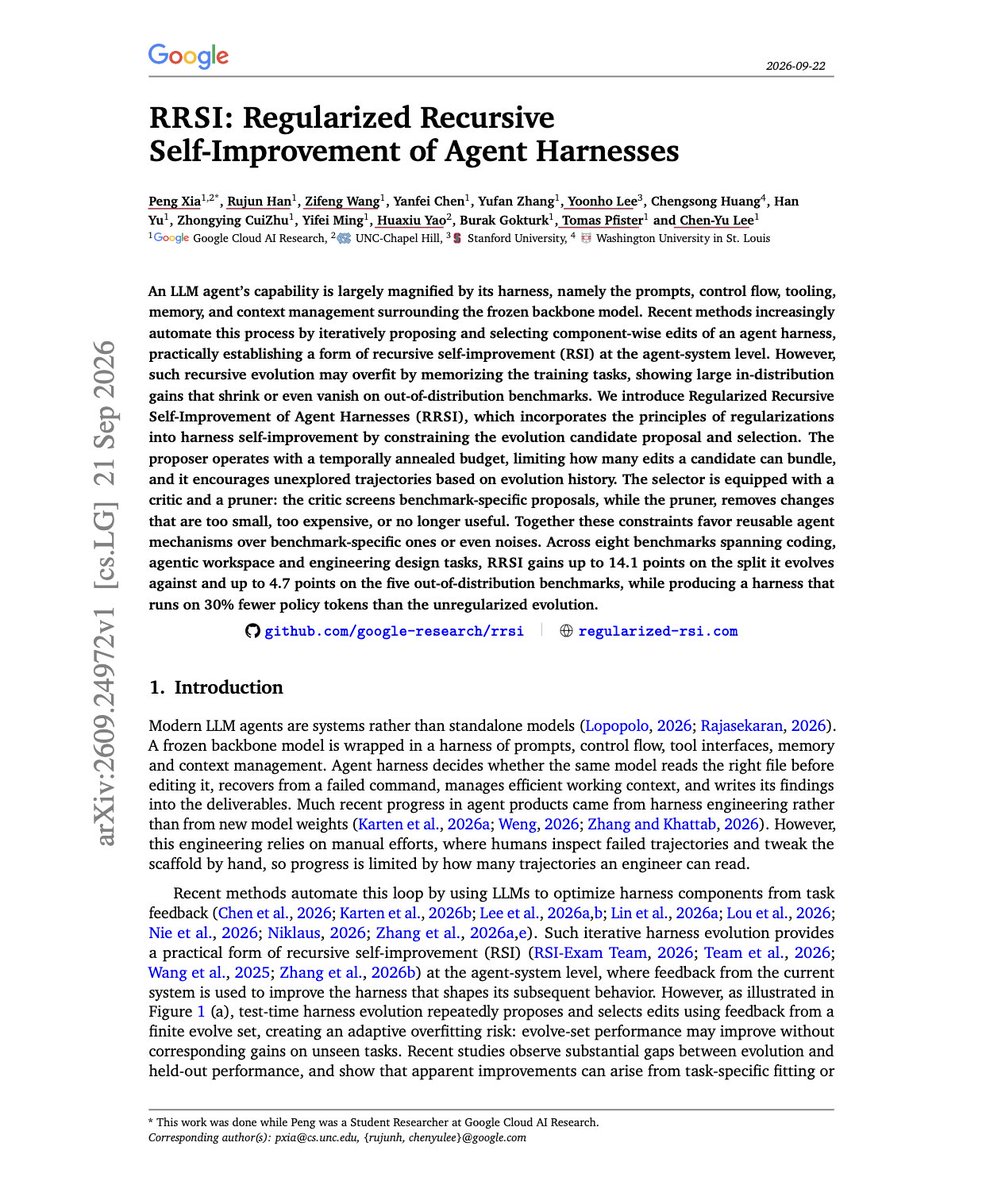
RRSI adds a regularization constraint to agent self-evolution so it favors reusable changes, improving out-of-distribution results on coding and engineering tasks while using 30% fewer tokens.

alphaXiv
@askalphaxivArchived 2026.09.24Originally posted 2026.09.23
alphaXiv @askalphaxivOriginally posted 2026.09.23
"RRSI: Regularized Recursive Self-Improvement of Agent Harnesses" RRSI makes self-improving AI agents generalize instead of just overfitting their benchmarks. So instead of letting self-improvement chase whatever boosts the benchmark, RRSI constrains the evolution process to favor changes that are actually reusable. Across coding, agentic workspace and engineering tasks, RRSI improves OOD benchmarks while using 30% fewer policy tokens than unregularized evolution. https://t.co/2fCZAddXz4
x.com/askalphaxiv/status/2102646972419375462Archived 2026.09.24 11:04