DeepSeek V4.1 Flash at ~100 tok/s locally with Maya-S quant
First try of deepseek-v4.1-flash-1017 on a local rig hits about 100 tok/s with the Maya-S quant, with a caveat that quantization likely costs two or three benchmark points.
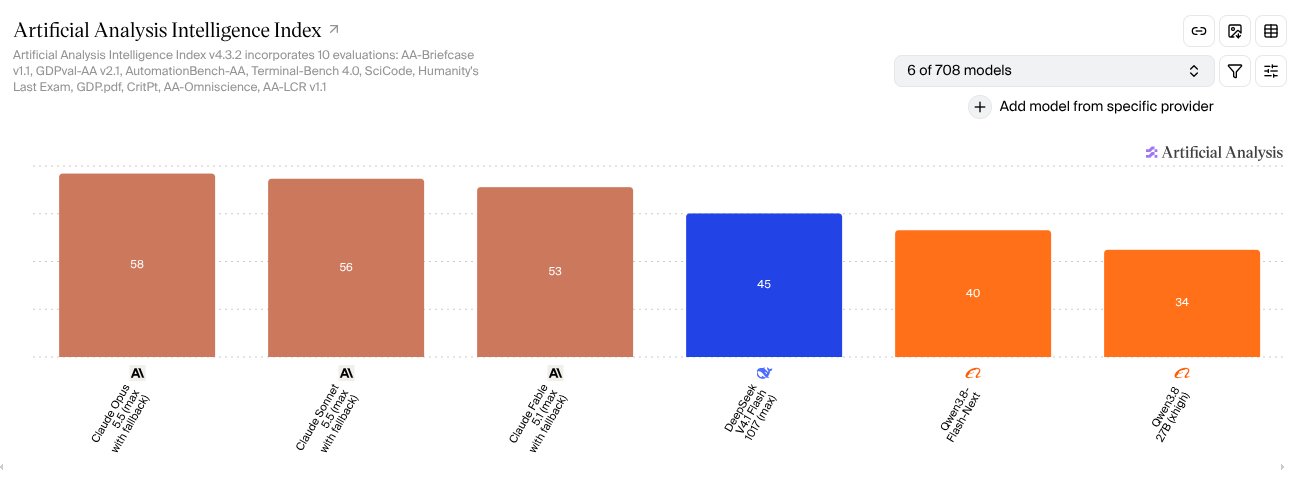
I have not used Opus, Sonnet, or Fable 5.5 for anything serious, so I don't have a good intuitive comparison. Here's how they rank on Artificial Analysis compared to the models I'm running. Much higher, apparently. I only just tried deepseek-v4.1-flash-1017 for the first time this morning. Early test shows about 100tps using the Maya-S quant (meaing probably knock two or three points off its score in the image). The model I actually use most right now is not listed on Artifical Analysis ( @ornith_ 1.5-122B ), but factoring in quantization I'd guess it's on par with Qwen3.8-flash-next in this image. All that to say, these models are more than capable for my engineering and research needs and are getting quite decent performance on the local rig. And the local models will only get smarter from here.