Jev tested as a prompt injection and jailbreak classifier against guardrail models
The author benchmarks Jev as a jailbreak and prompt injection classifier: it beats off-the-shelf guardrails including Meta's on newer attack sets, but loses on older sets and at tight false-alarm budgets, and fails on obscured internal attacks.
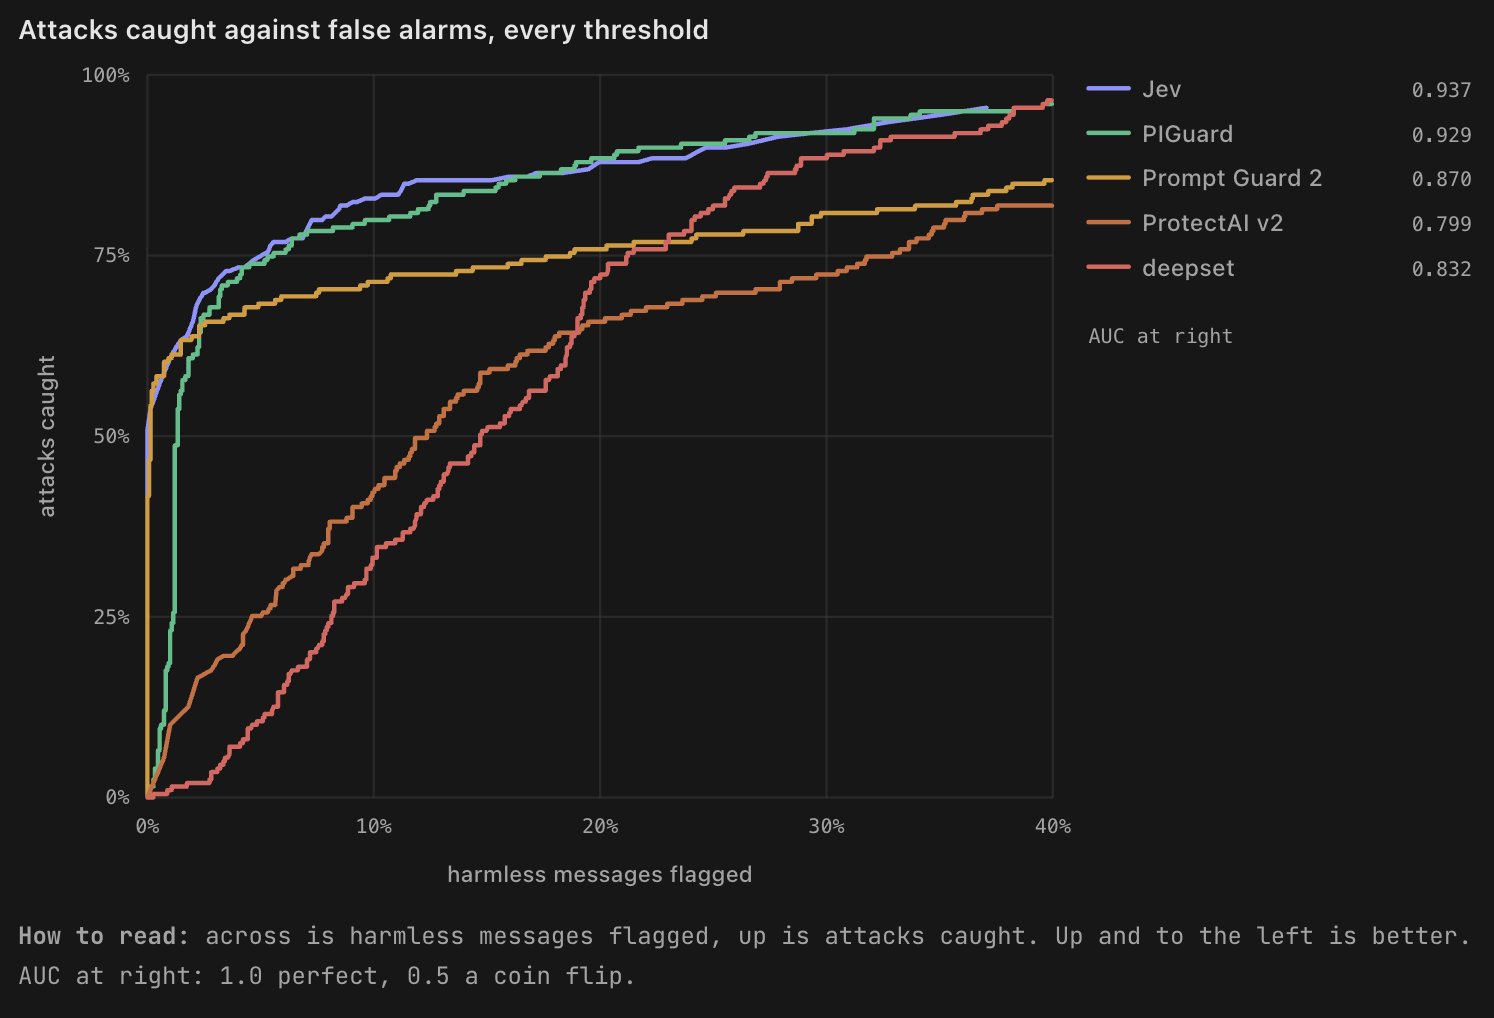
Sharing some prompt injection "jailbreak" benchmarks I've been running with Jev, competing against a bunch of standard guardrail classifiers including Meta's. Part of it is a standard open suite that's getting dated. Jev wins that one outright, and wins the newest attack set too. It loses on the older sets and can't run at a tight false-alarm budget. It failed some of our internal benchmarks when something more nefarious is going on & is obscured, but there's really not any good off the shelf classifier that could be used for those type of scenarios. You can see a glimpse of this with how every model performed poorly at allenai's WildJailbreak. Since the poker eval I've been trying to pin down where Jev fits. My hunch is perfect-information calls with little strategy in them. Still testing it.