deepseek-v4.1IMAGE
DeepSeek V4.1 Flash ternary quantization: 11.8 to 143 tok/s decode, ~92% of FP4 intelligence
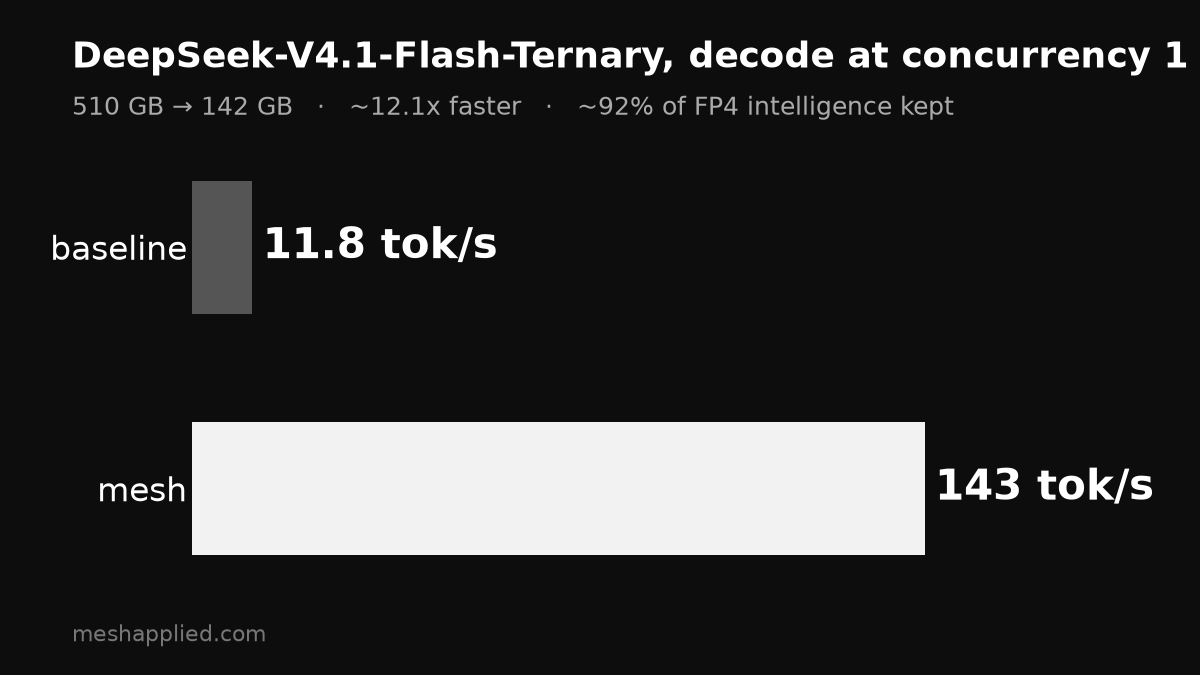
Ternary quantization shrinks the 510 GB base model to a 142 GB pack, speeds decode ~12.1x at concurrency 1 and keeps ~92% of FP4 intelligence, which the author argues suits coding and research agents.
matteo horvath
@buildingmatteoArchived 2 days agoOriginally posted 2026.10.27
matteo horvath @buildingmatteoOriginally posted 2026.10.27
11.8 → 143 tok/s. DeepSeek-V4.1-Flash-Ternary. 510 GB base → 142 GB pack. ~12.1x faster decode at concurrency 1. ~92% of FP4 intelligence kept. ternary is not free and we lose ~8% vs FP4 for coding and research agents, a model you can run 12x more often beats a slightly smarter one you can't.
x.com/buildingmatteo/status/2114833006825480536Archived 2026.10.27 12:08