Fireworks fine-tunes Muse Glimmer to beat Jev on Kalshi
Fireworks fine-tuned Muse Glimmer 30B with SFT and backtested it on Kalshi prediction markets, hitting 58.3% accuracy versus Jev's 47.1% and ending at $1,071 versus $919 on $1,000.
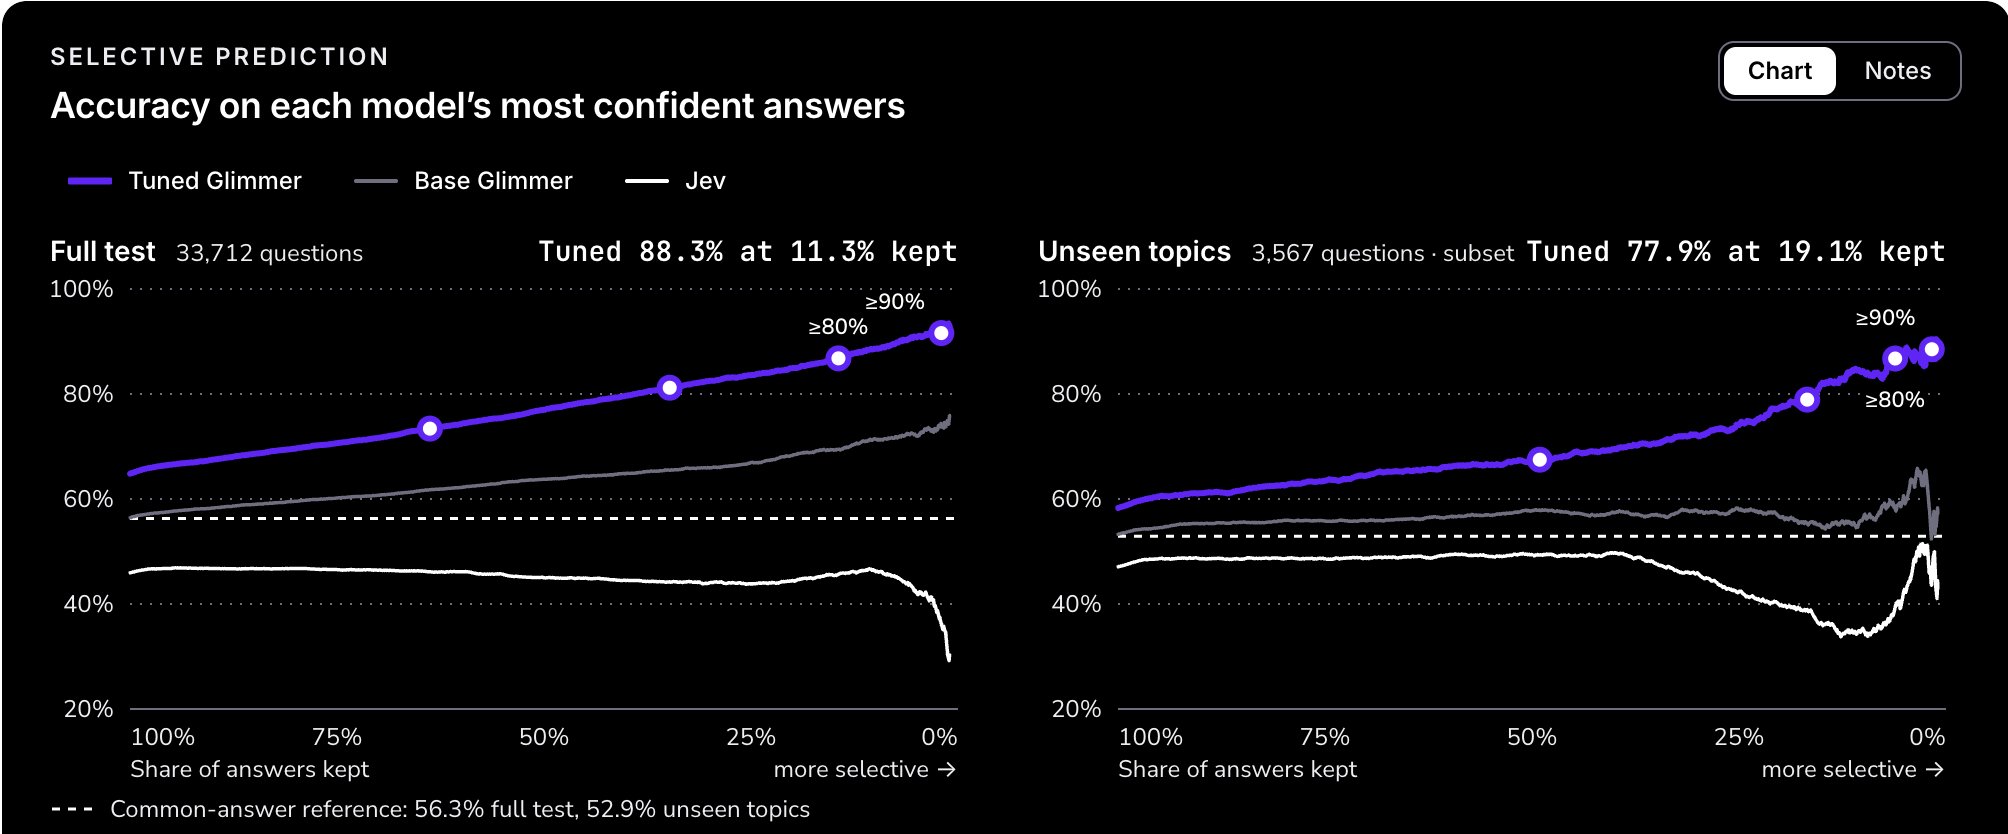
Train @AIatMeta's Muse Glimmer free with the @FireworksAI_HQ Free Weights Club and learn how one SFT run out-bet Jev on @Kalshi prediction markets I’m the product lead for training at Fireworks. Muse Glimmer 30B is now free to fine-tune with SFT through Nov 30. You don’t need a credit card, you don’t have to procure GPUs, and you don’t have to stitch a training stack together. There are three ways in, depending on how much control you want. Bring your examples to Managed Training and we run the job. Write your own loop on the Serverless Training API. Or install our training skills and tell your coding agent what to train. All three run on the same platform that teams use for full-parameter RL at 10,000+ GPU scale, so nothing you start on today needs rebuilding when you grow. This is the first drop of the Free Weights Club. For a limited time, we’ll publish post-training research, a recipe you can reuse, and free training on a featured model. We wanted the first experiment to have a scoreboard, so we trained Glimmer on historical Kalshi markets and put it against Jev. On topic families it never saw in training, tuned Glimmer was right 58.3% of the time. Jev was right 47.1%. In a backtest with $1,000 each, Glimmer finished at $1,071. Jev finished at $919, and base Glimmer at $950. Same model, one training run, and it went from losing money to making it. That’s the specialization argument in miniature. A general model gives you the average of everyone’s tasks. Train on yours and a 30B model can win. Here’s what’s worth stealing from how we did it. Markets settle, which means every question eventually has a right answer. The model saw only the market’s title, description, rules, and date, with no prices and no news. Most teams are sitting on the same kind of data and don’t call it training data: resolved tickets, merged diffs, agent tool calls someone had to fix. Most of the effort went into leakage, because that’s where evals lie to you. We split by time and held out 113 entire topic families, so the test measured generalization instead of recall. We also removed near-duplicates, rules edited after a market opened, and winning options added late. Each one would have improved our numbers without improving the model. The training was one LoRA pass over about 20K questions. Each question has a fixed set of answers, so we trained the model to choose among those answers only, not to predict any word in its vocabulary. All the learning goes into the decision we actually care about. Then we calibrated its confidence on a held-out set, without retraining. When Glimmer said 80% or higher, it was right 86.8% of the time. That covered only about 14% of questions, but those are the calls you can act on. Jev’s probabilities went in raw from its API, which is how most people would use it. To turn predictions into bets, every model got the same rule: buy only when its odds beat the market price plus fees by at least 5¢, and bet more when more confident. Returns are after fees but before liquidity and slippage. To check that a few lucky events weren’t driving the result, we reran the backtest many times on random mixes of events. In 90% of those runs, Glimmer’s return landed between +1.6% and +12.4%. It stayed positive. One serving note. When you only need option probabilities, generating text is wasted work. Our System One API reads the probabilities directly and packs many questions over a shared context into one request. In a separate benchmark on a single B200, the full stack ran 2–3x faster than BF16 chat completions at the median, with up to 3.6x more decisions per second at 16–32 questions per request. You don’t need to care about prediction markets for any of this to apply. Pick the mistake you’re tired of correcting in your day to day work, turn your fixes into examples, and train. It’s free through Nov 30. Inference and evals are billed as usual. shout out to @TranLeDinhQuy for building the whole setup Start training free → http://fireworks.ai/blog/train-muse-glimmer-for-free https://github.com/fw-ai/cookbook/blob/main/training/examples/decision/kalshi_v1/README.md
This post quotes another post: x.com/fireworksai_hq/status/2113011534909800864