Yale physicists re-grade physics benchmarks, find GPT-6 Astra was underrated
A new paper had Yale physicists manually re-grade frontier models' failures on major physics benchmarks and found many were caused by flawed questions and grading, with scores rising sharply once corrected.
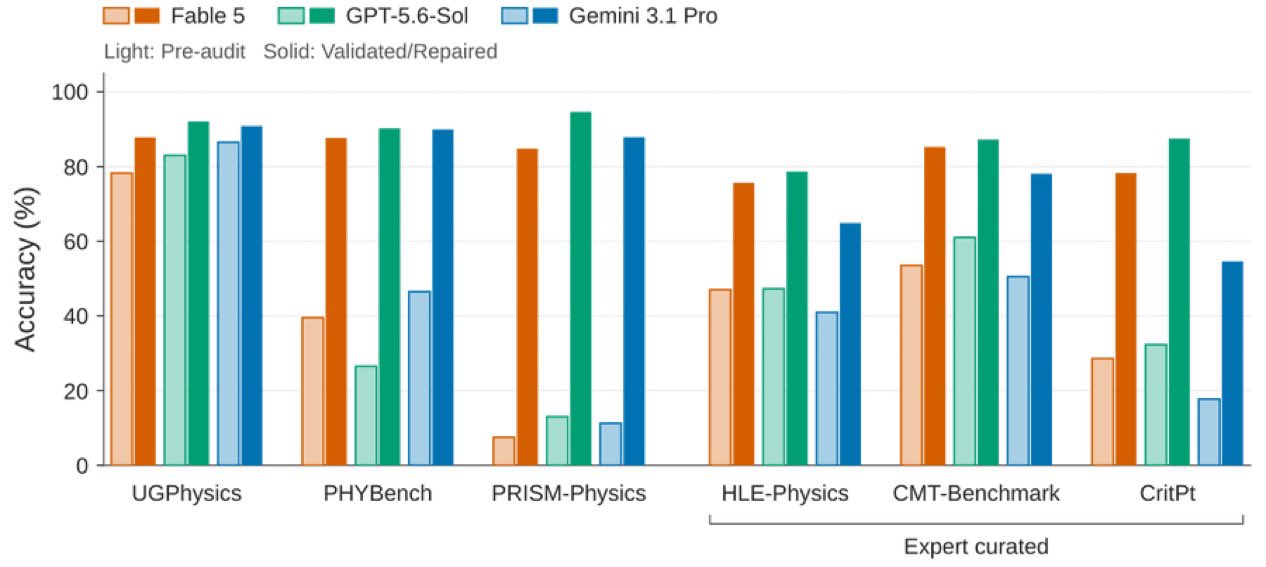
Ever since Artificial Analysis pinned GPT-6 Astra below many others we all felt something was wrong, now we may have evidence. A new paper had Yale physicists manually re-grade the supposed failures of frontier models across major physics benchmarks, and found that a huge amount of the problem was actually the benchmark/grading itself, not the models. This is something @tszzl and many other lab employees note. Once the broken questions and grading were corrected, frontier models nearly saturated several of these benchmarks. GPT-5.6 Sol for example jumps from 47.3% to 78.7% on HLE-Physics mean@4, and hits 94.4% pass@4 on corrected CritPt. This is a pretty brutal indictment of the index and I hope they are able to look into these results!
This post quotes another post: x.com/zeyiandyliu/status/2099559337299443956