Gemini 4 Argon benchmark chart: leads outright on 13 of 19 results
A chart shows Argon leading outright on 13 of 19 results, scoring 84.2% on GraphWalks at 256K-1M tokens and 19.6% on Harvey's legal benchmark, nearly three times the next model, while still trailing Astra and Opus 5.5 on FrontierSWE and Terminal-Bench.
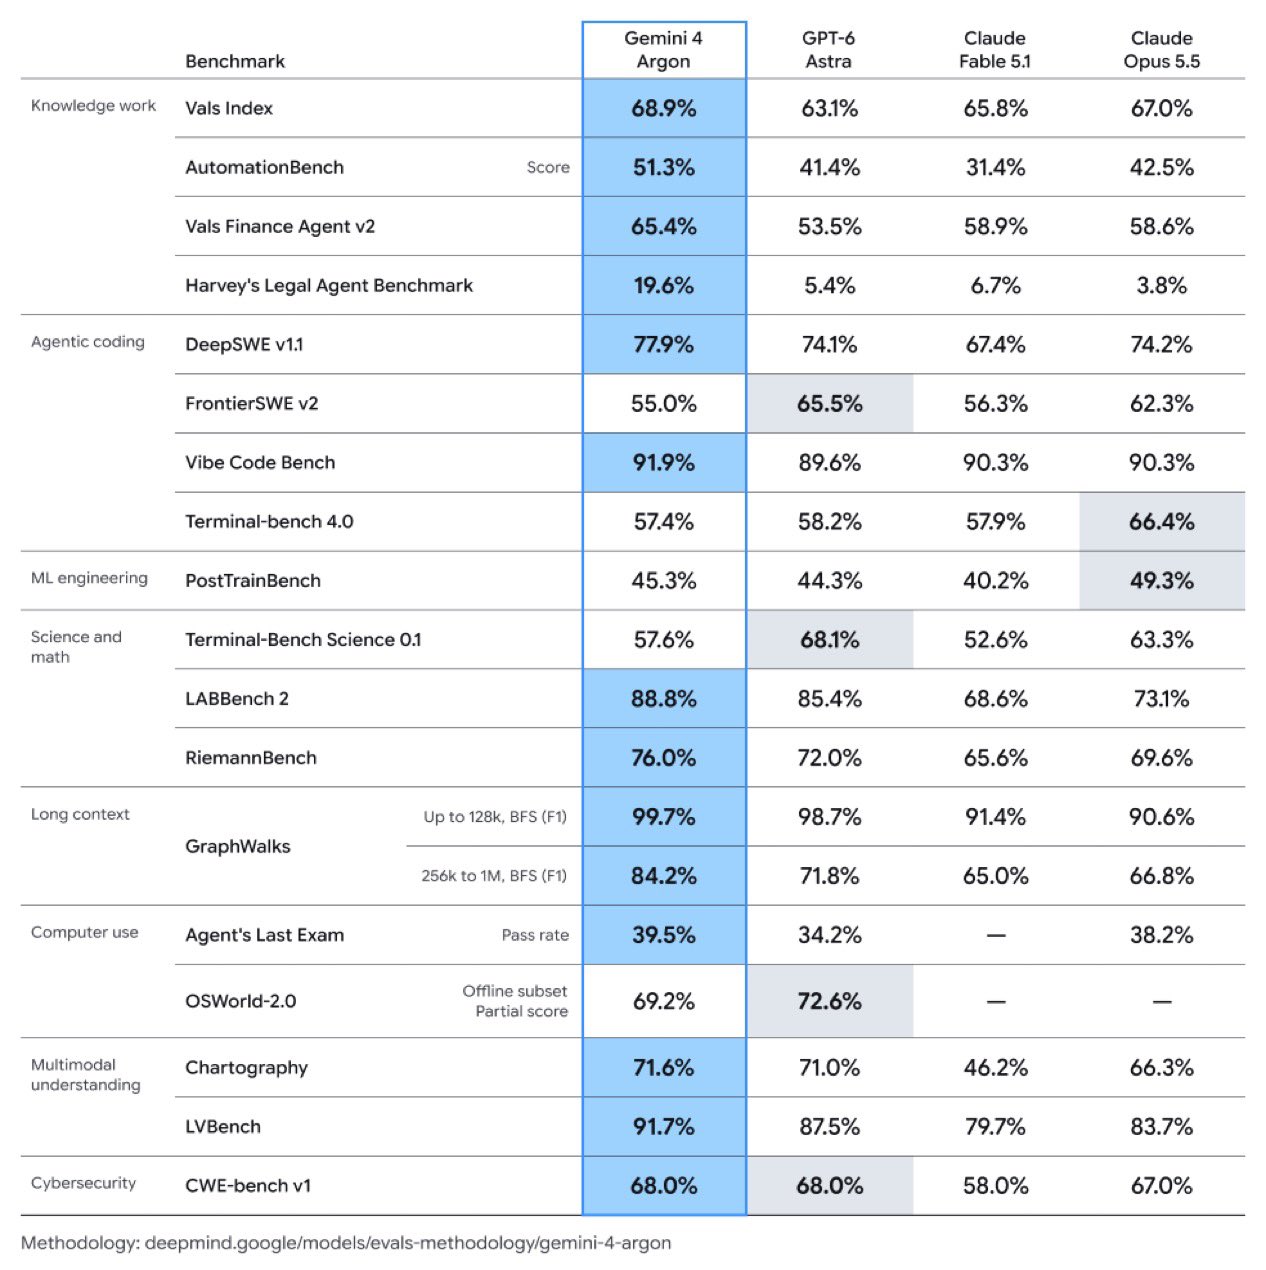
Google has finally released a stable pro model after more than a year and a half of waiting!! Gemini 4 Argon leads outright on 13 of the 19 results on this chart and ties Astra on cybersecurity. The long-context gap is pretty good, (they didn’t report it but they’re still behind Muse 1.3)- 84.2% on GraphWalks at 256K-1M tokens, compared with 71.8% for Astra and 66.8% for Opus 5.5. IMG_2573.jpeg On Harvey’s legal benchmark, it scores 19.6% against 6.7% for the next-best model shown, almost 3x the score. It also leads all four knowledge-work evaluations in this table, including 51.3% on AutomationBench against 42.5% for Opus and 41.4% for Astra. Astra still leads FrontierSWE and Terminal-Bench Science, while Opus 5.5 leads Terminal-Bench 4.0 and PostTrainBench. So the strongest argument for Argon here is the breadth of its results, especially across knowledge work and long-context reasoning.
This post quotes another post: x.com/googledeepmind/status/2105388084154056939