fast-jev-compaction uses Jev to decide which context an agent keeps
A community plugin uses Jev to judge which tool calls and results to retain; in one experiment it matched the reference pass rate but dropped a key piece of evidence.
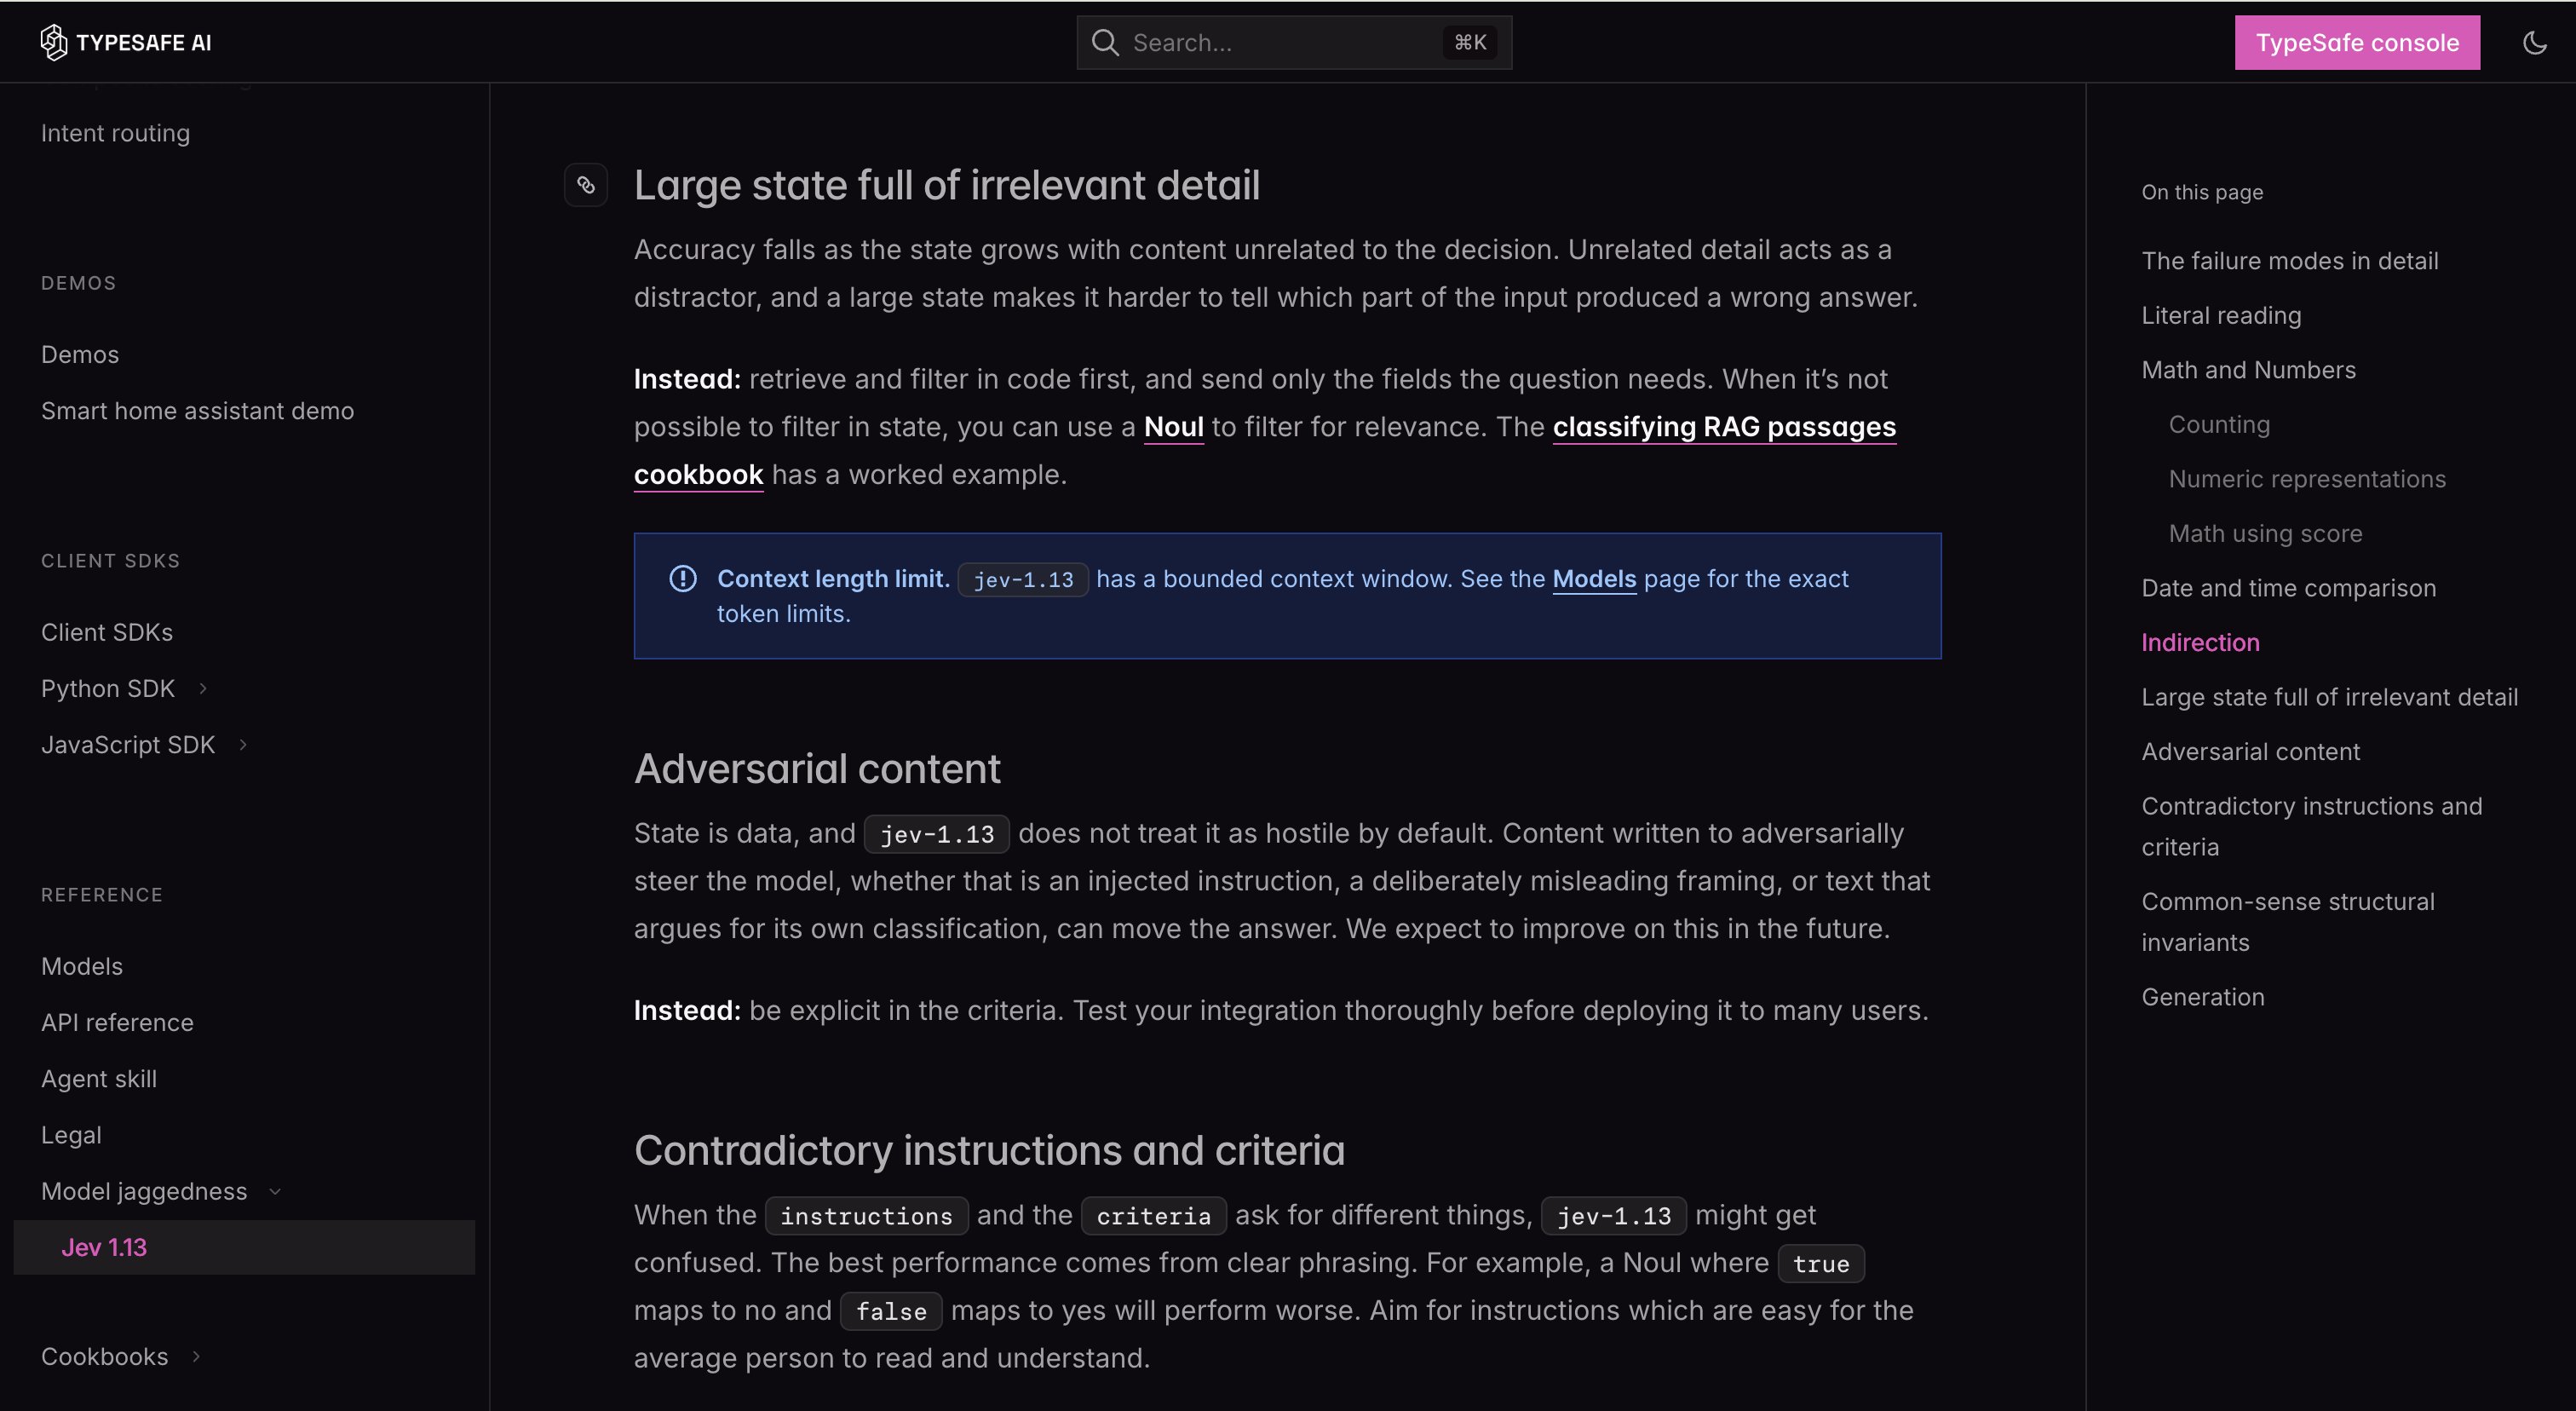
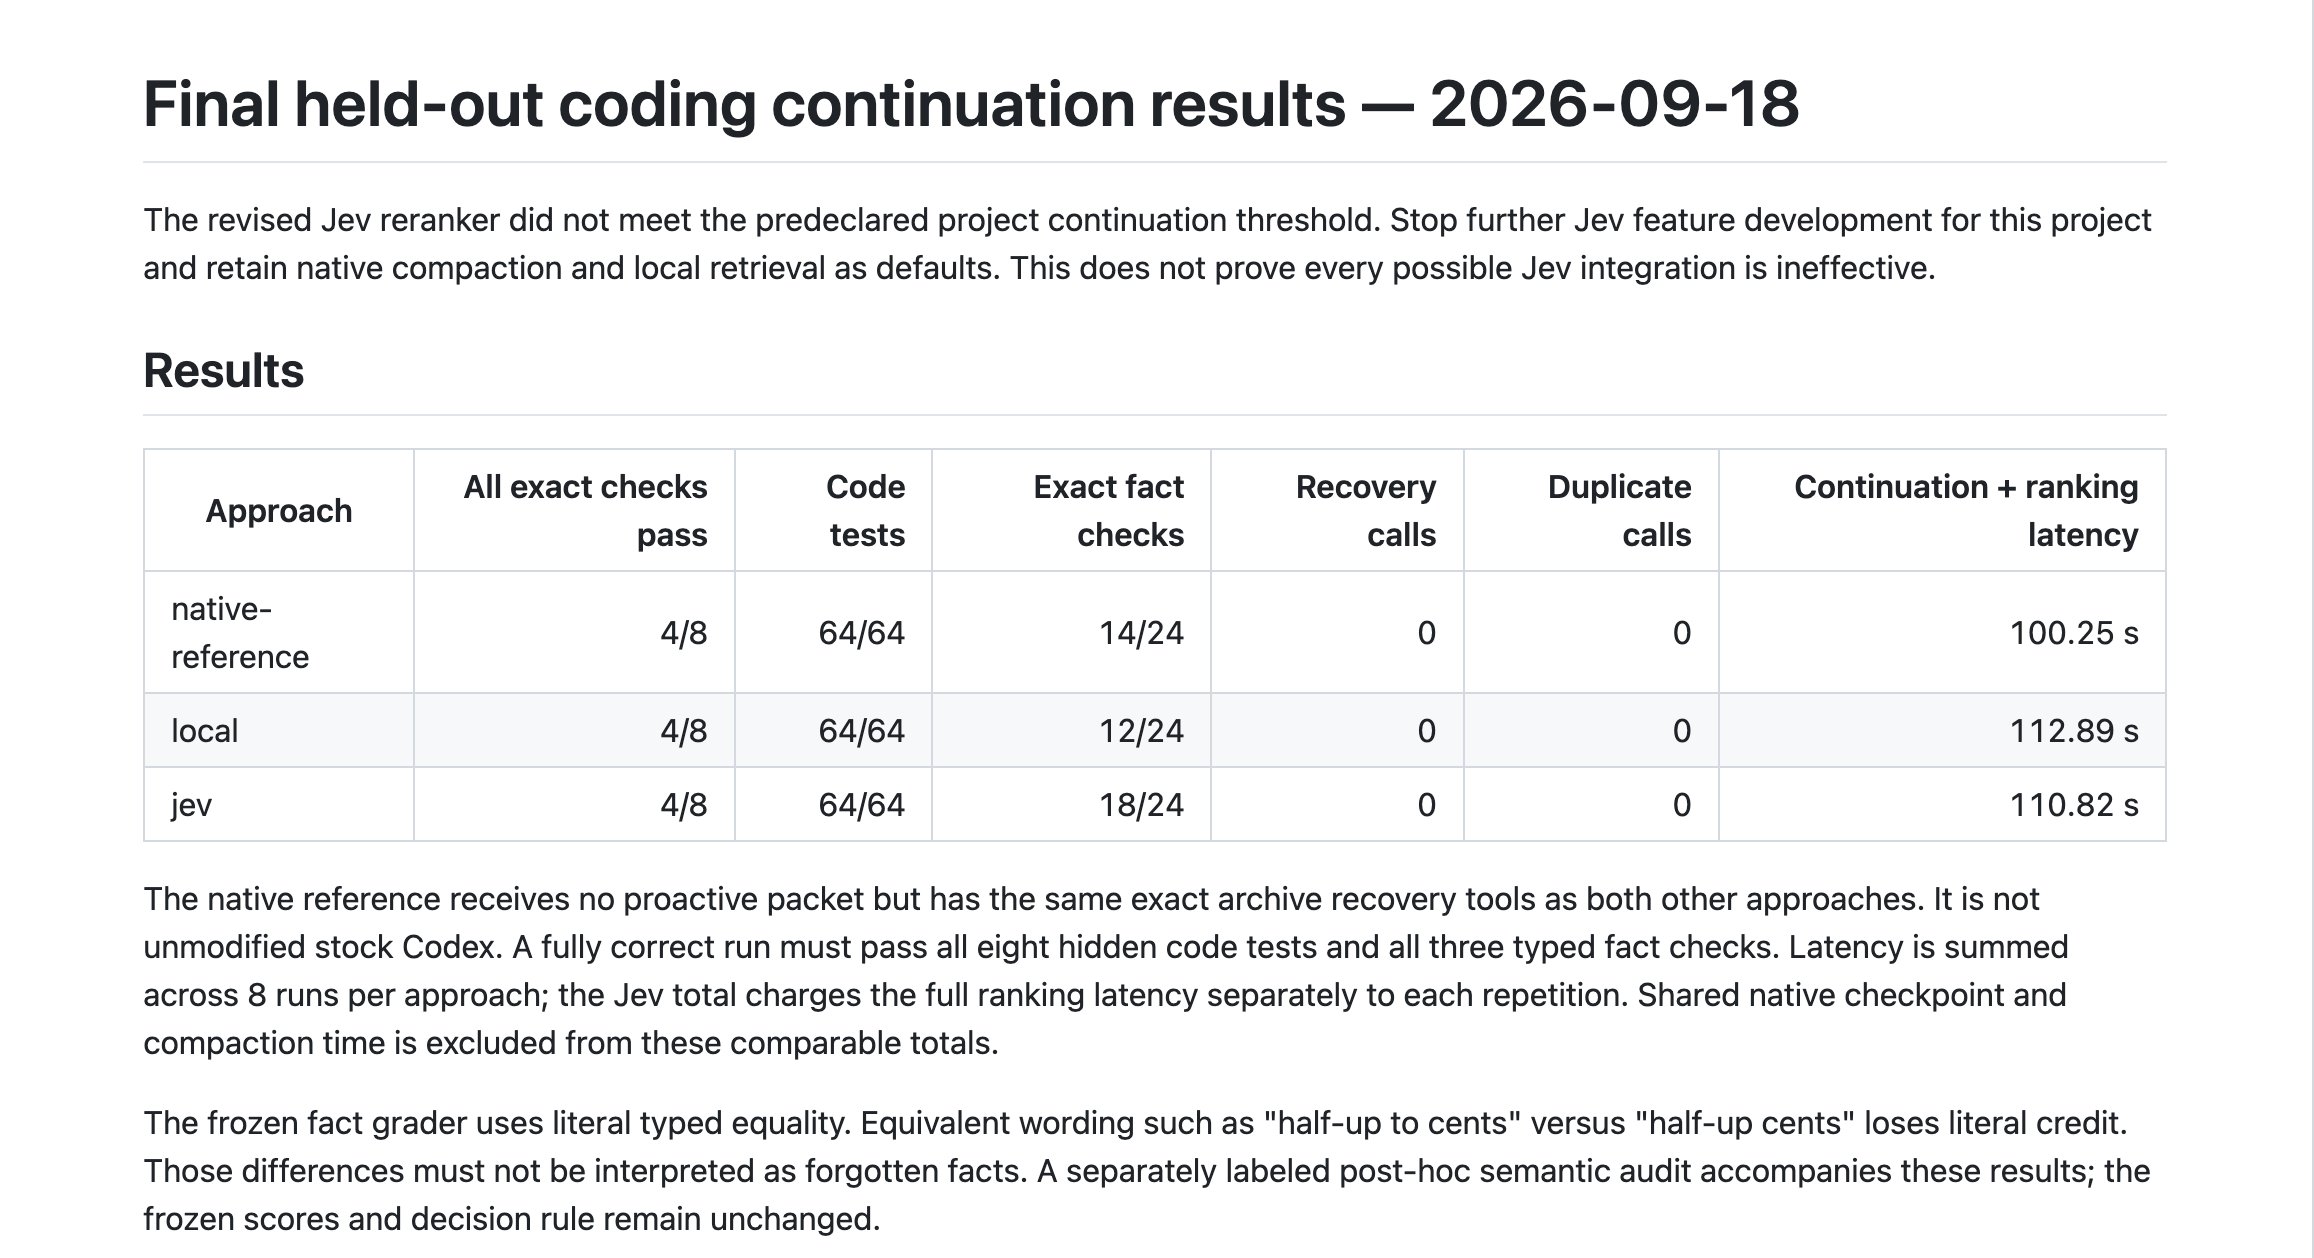
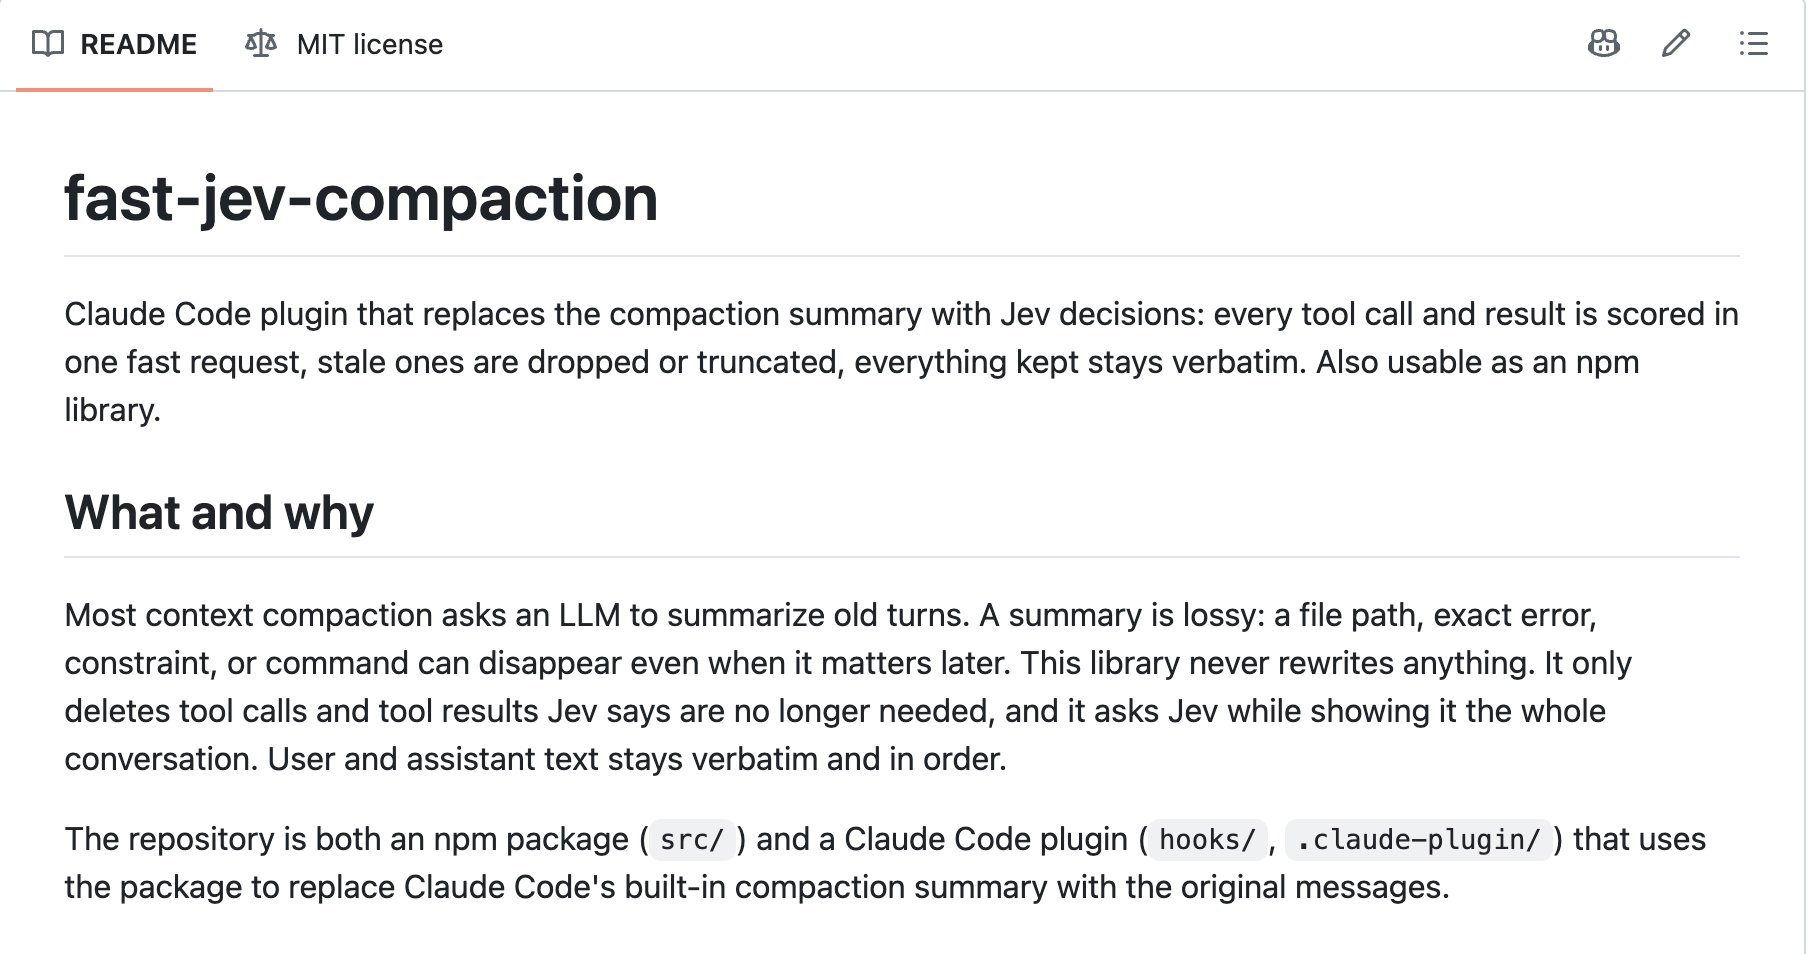
After Jev went viral, does context still matter? Jev let me rethinking a basic assumption: does an agent need the entire conversation at every step? The official docs warn that irrelevant content reduces Jev 1.13’s accuracy. The community plugin fast-jev-compaction uses Jev to decide which tool calls and results to retain. Code deletes or truncates them; user and assistant text stays unchanged in the output. In a small September 18 experiment from a separate project, Jev matched the reference approach’s pass rate. But its selected evidence omitted a 20-minute reservation duration. The original record was still available; the agent never retrieved it. Keeping a complete history and reading it on every call can be separate design choices. Once relevance judgments become cheap enough, constructing context can become part of the model’s ongoing decision-making. Each piece of information should be reassessed against the task at hand.