Beyond the leaderboard: Astra solves in 29 steps, Gemini needs 166
The author notes Astra reached 74.1% with 30k output tokens across 29 steps, while Gemini needed nearly 5x the steps to match, arguing step count matters more than the percentage.
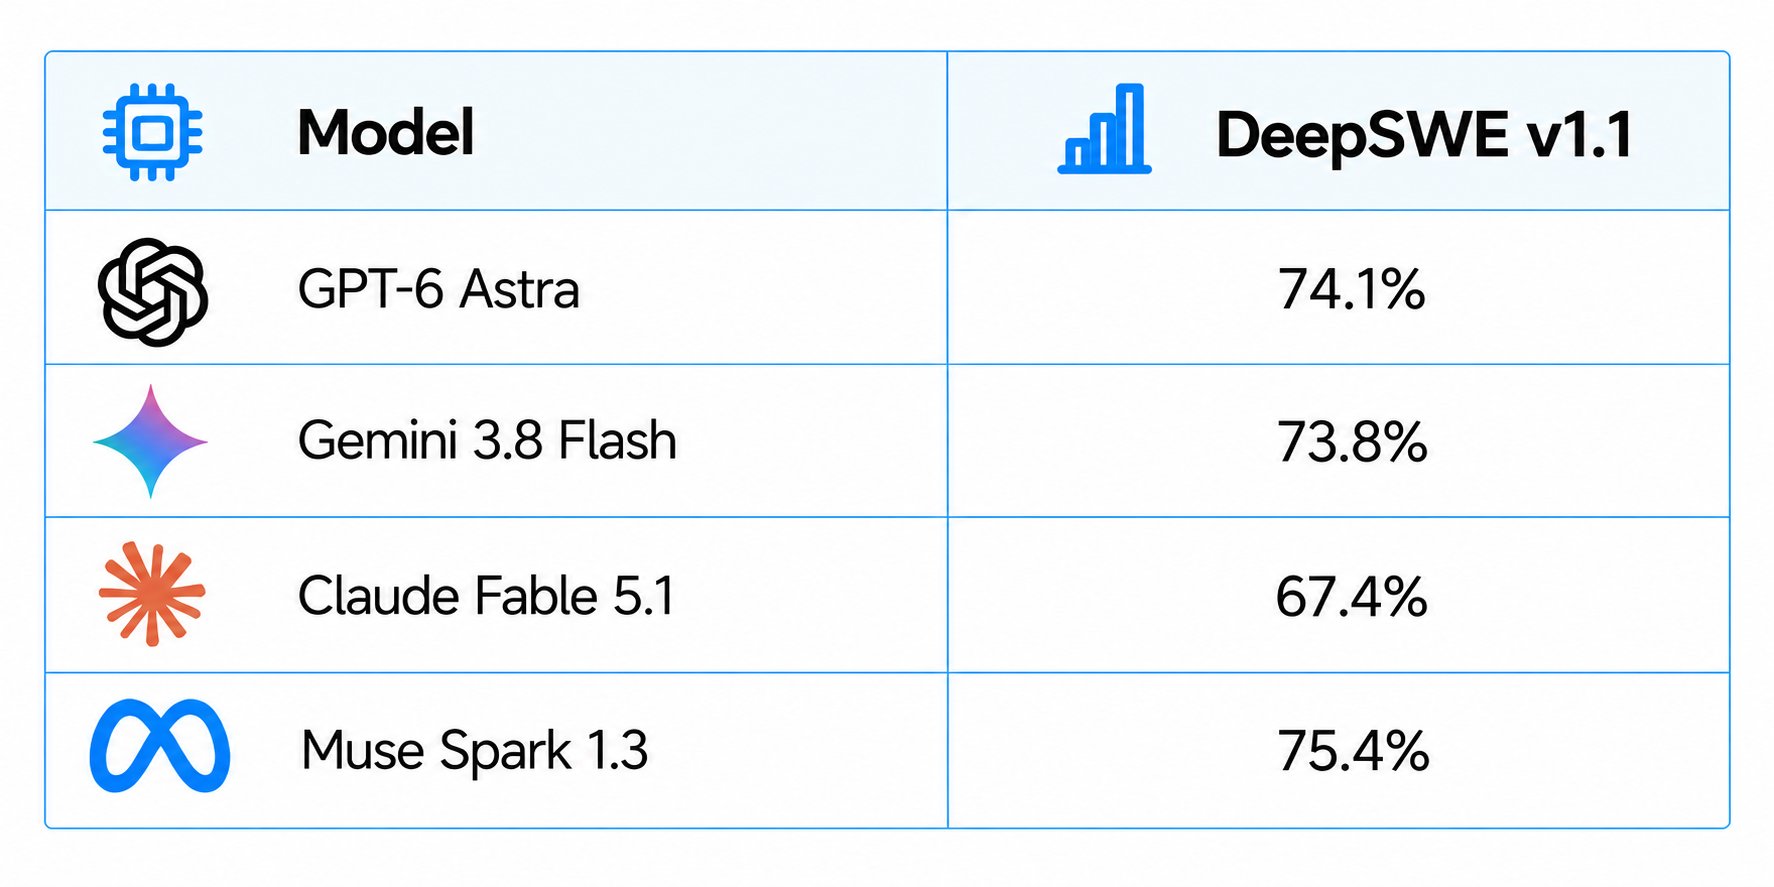
the chart everyone's sharing is missing the actual story muse spark 1.3 tops deepswe v1.1 at 75.4%. gpt-6 astra sits half a point back at 74.1%. gemini 3.8 flash trails by 1.6 points. claude fable 5.1 lands lowest in this specific chart at 67.4%. here's what the chart doesn't show. astra hit its 74.1% using 30k output tokens across 29 steps, roughly $6.52 a run. gemini matched astra within a point using 143k tokens and 166 steps, nearly 5x the steps for a nearly identical score. (nobody talks about the step count. everyone screenshots the percentage.) three points separate the top score from the bottom in this specific chart. three points is not the story. the actual gap is between a model that solves it in 29 moves and one that needs 166. fable 5.1's 67.4% here doesn't match its performance elsewhere either, it leads the broader intelligence index at 66 against astra's 61. one benchmark chart is a snapshot, not a verdict on which model is actually better for your specific workload. still haven't found a single leaderboard that tells the full story on its own. run your own task before trusting a screenshot.
This post quotes another post: x.com/cyrilxbt/status/2097335790015521233