gpt-6IMAGE
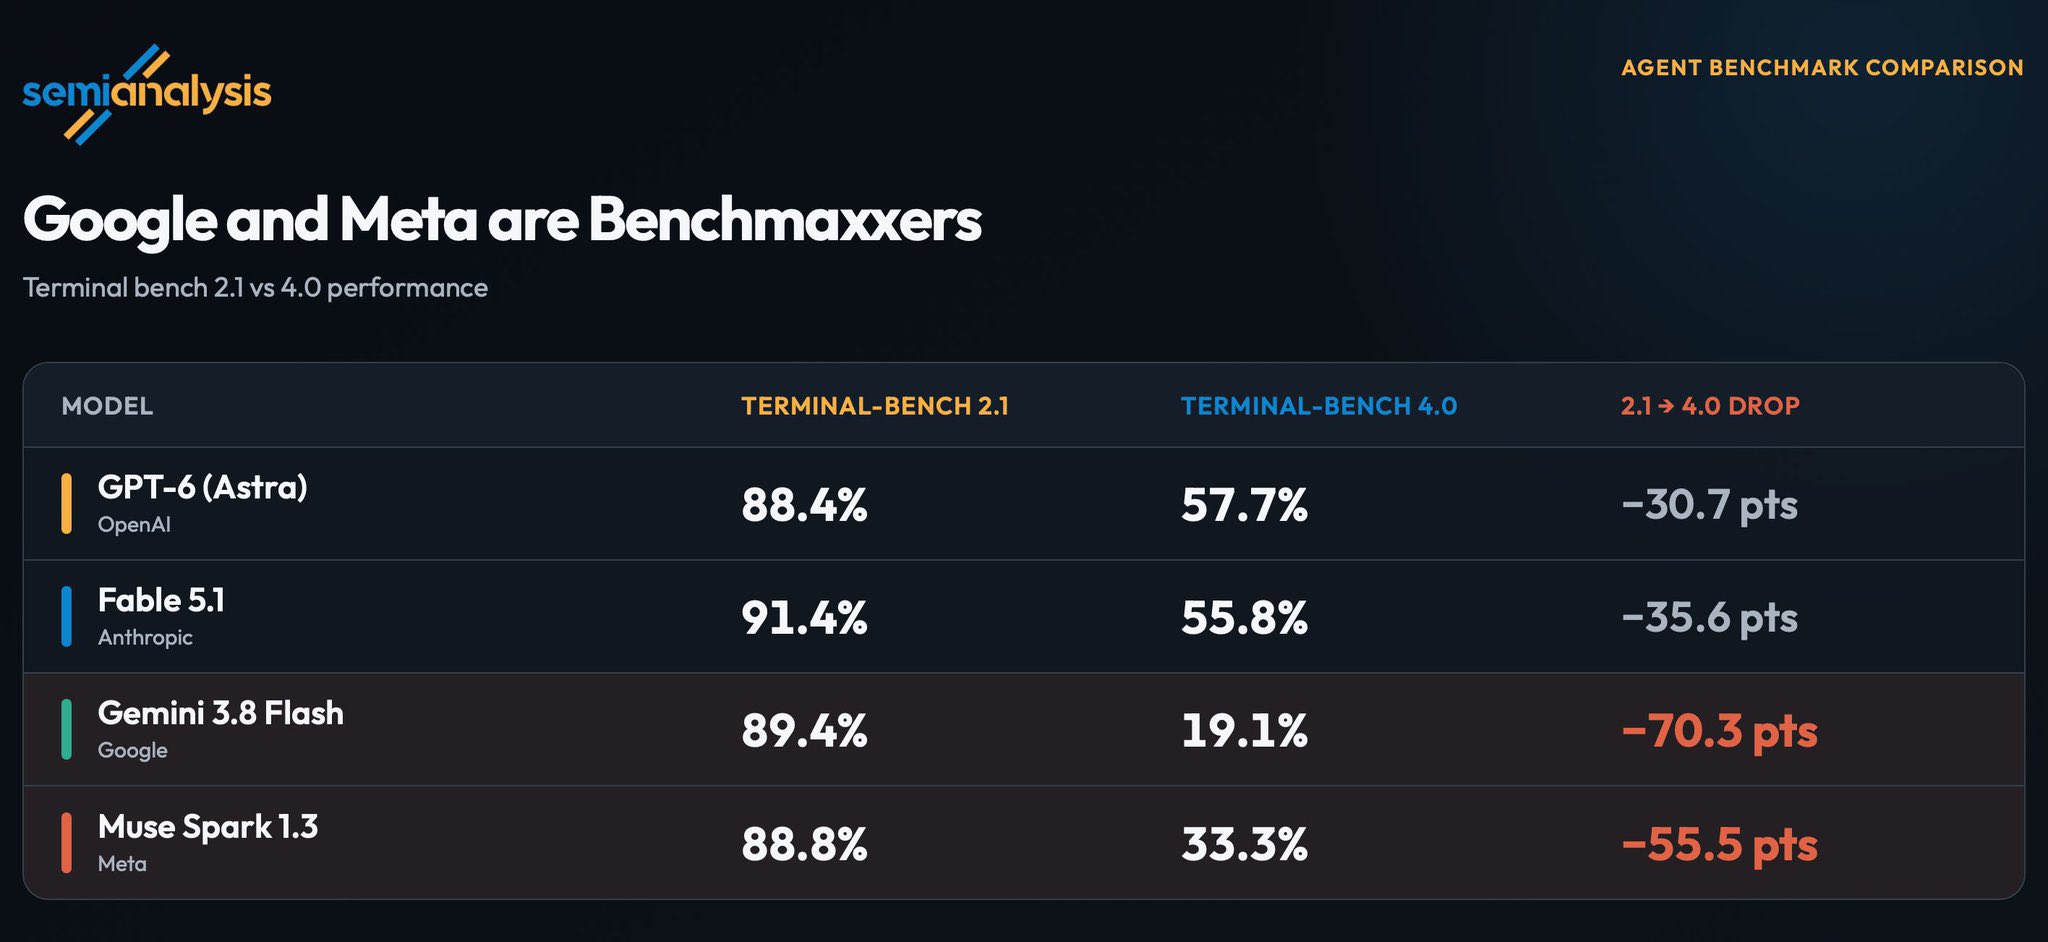
Fresh benchmark drops Gemini 3.8 Flash and Muse Spark 1.3 from ~90% to 19% and 33%
DanDr1s says Gemini 3.8 Flash and Muse Spark 1.3 looked close to Astra on public leaderboards but fell to 19.1% and 33.3% on a new benchmark, while Astra held at around 56–58%.
Dan
@DanDr1sArchived 2026.09.14Originally posted 2026.09.08
Dan @DanDr1sOriginally posted 2026.09.08
Google and Meta are benchmaxxing hard. Gemini 3.8 Flash and Muse Spark 1.3 look almost as good as GPT-6 Astra and Fable 5.1. Then a fresh benchmark drops: Gemini: 89.4% → 19.1% Muse: 88.8% → 33.3% Meanwhile GPT-6 and Fable still score ~56–58%. This is what happens when labs optimize around public benchmarks instead of building models that actually generalize. Benchmark scores are becoming harder and harder to trust.
This post quotes another post: x.com/semianalysis_/status/2097112794717958498
x.com/dandr1s/status/2097261818439684441Archived 2026.09.14 15:41