Asana cuts Codex browser agent cost 4x with prompt caching
On GPT-6.1 Sol, keeping session history stable raised the prompt cache hit rate to 89%, cutting cost per run from $1.97 to $0.47, with four practical habits shared.
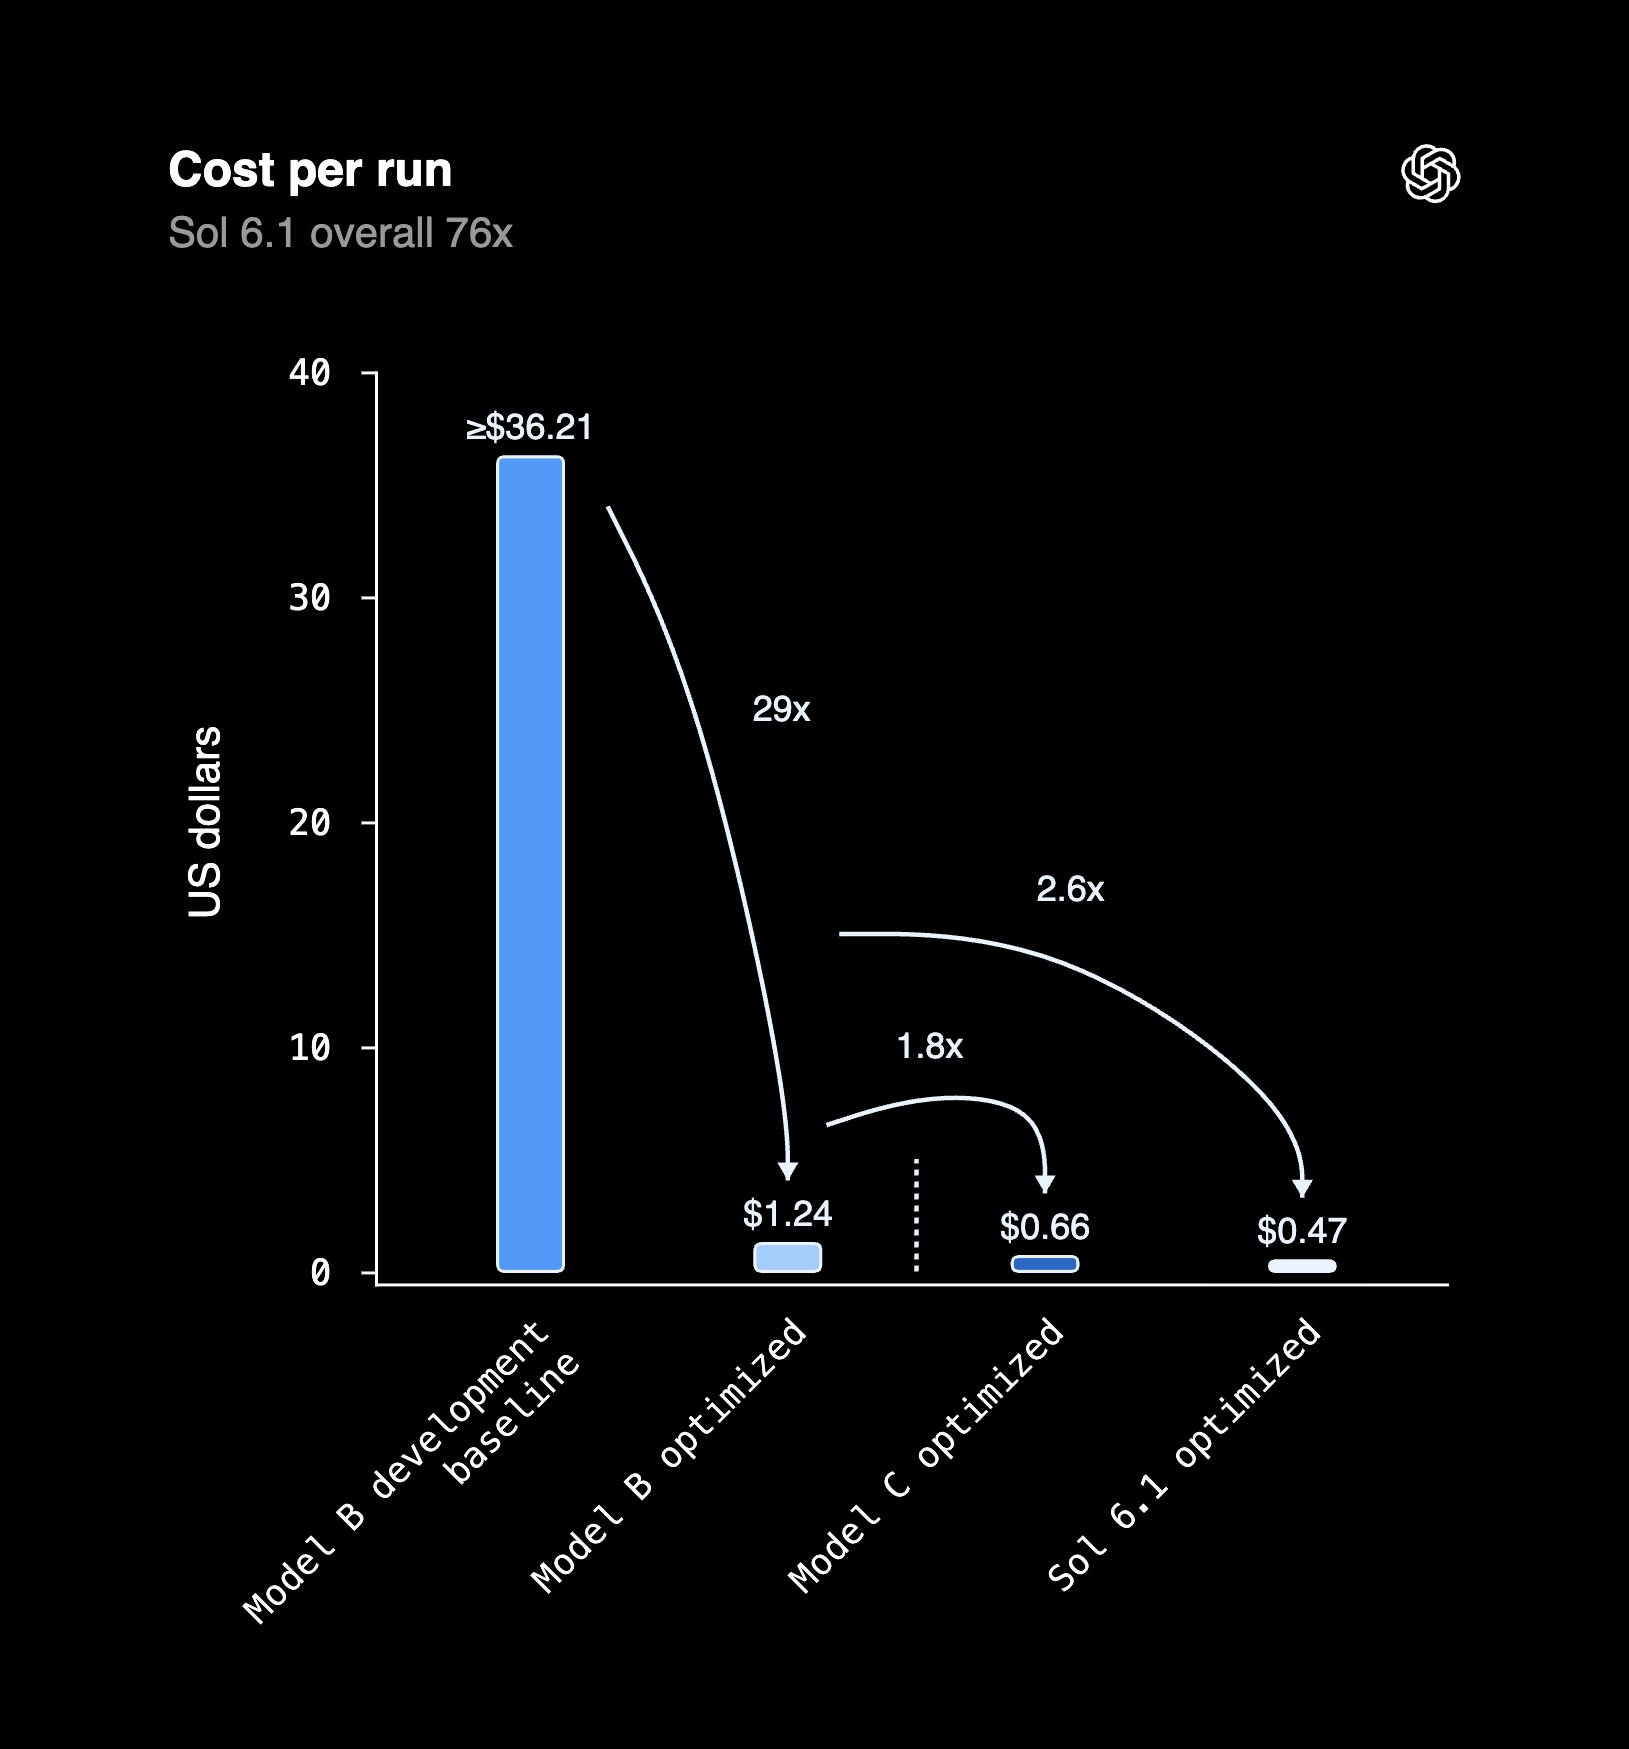
This is amazing. Asana cut a Codex-built browser agent's cost 4x on GPT-6.1 Sol ($1.97 → $0.47 per run) by doing one thing: keeping its history stable so the prompt cache hit 89% of the time. 4 habits you can use today to maximize your cache hit rate: 1. Keep your session append-only. Don't rewrite earlier context, and stay in one long session instead of restarting. 2. Don't switch model, reasoning effort (except GPT-6 Astra), or tools mid-session. Any of them changes the start of the request and breaks the cache. 3. Treat /compact as a cache reset. It rewrites earlier context, so compact deliberately, not by habit. 4. Measure it. Run codex exec --json "<task>" and divide cached_input_tokens by input_tokens. Works well for individuals, and even better for teams as the efficiencies compound the more tokens you use.