gpt-6IMAGE
Same task benchmarked across Astra, Sol 6.1 and Grok 4.7
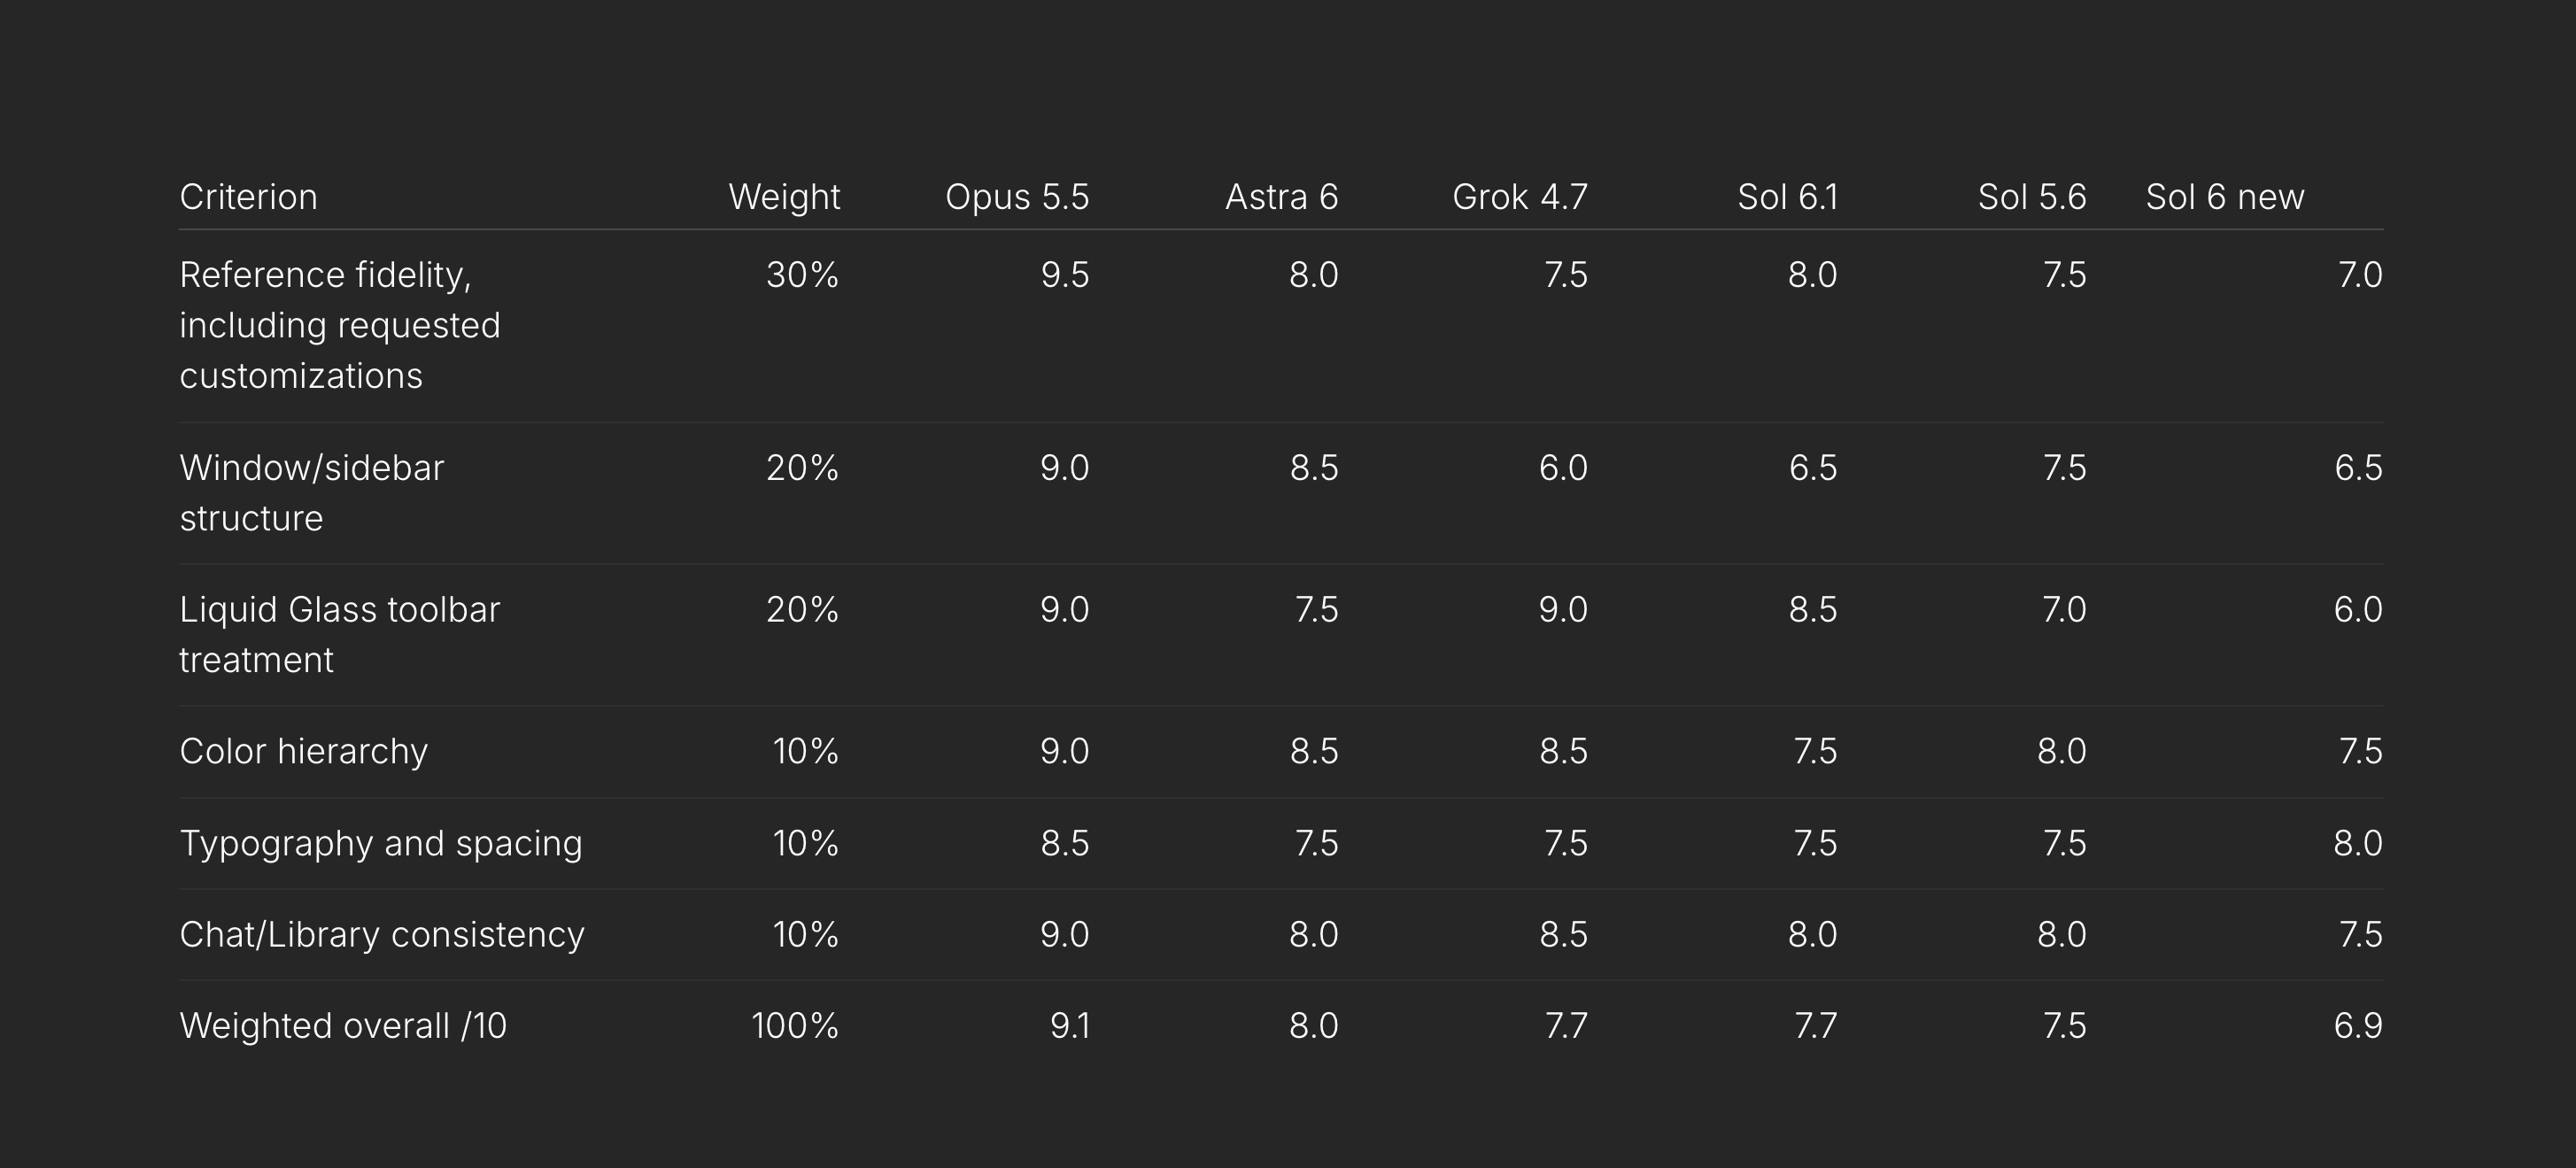
The author gave the same task to several models: Opus 5.5 scored 9.1 to lead, Astra 8.0, and Sol 6.1 and Grok 4.7 tied at 7.7.
Daniel Nguyen
@daniel_nguyenxArchived 2026.10.01Originally posted 2026.09.30
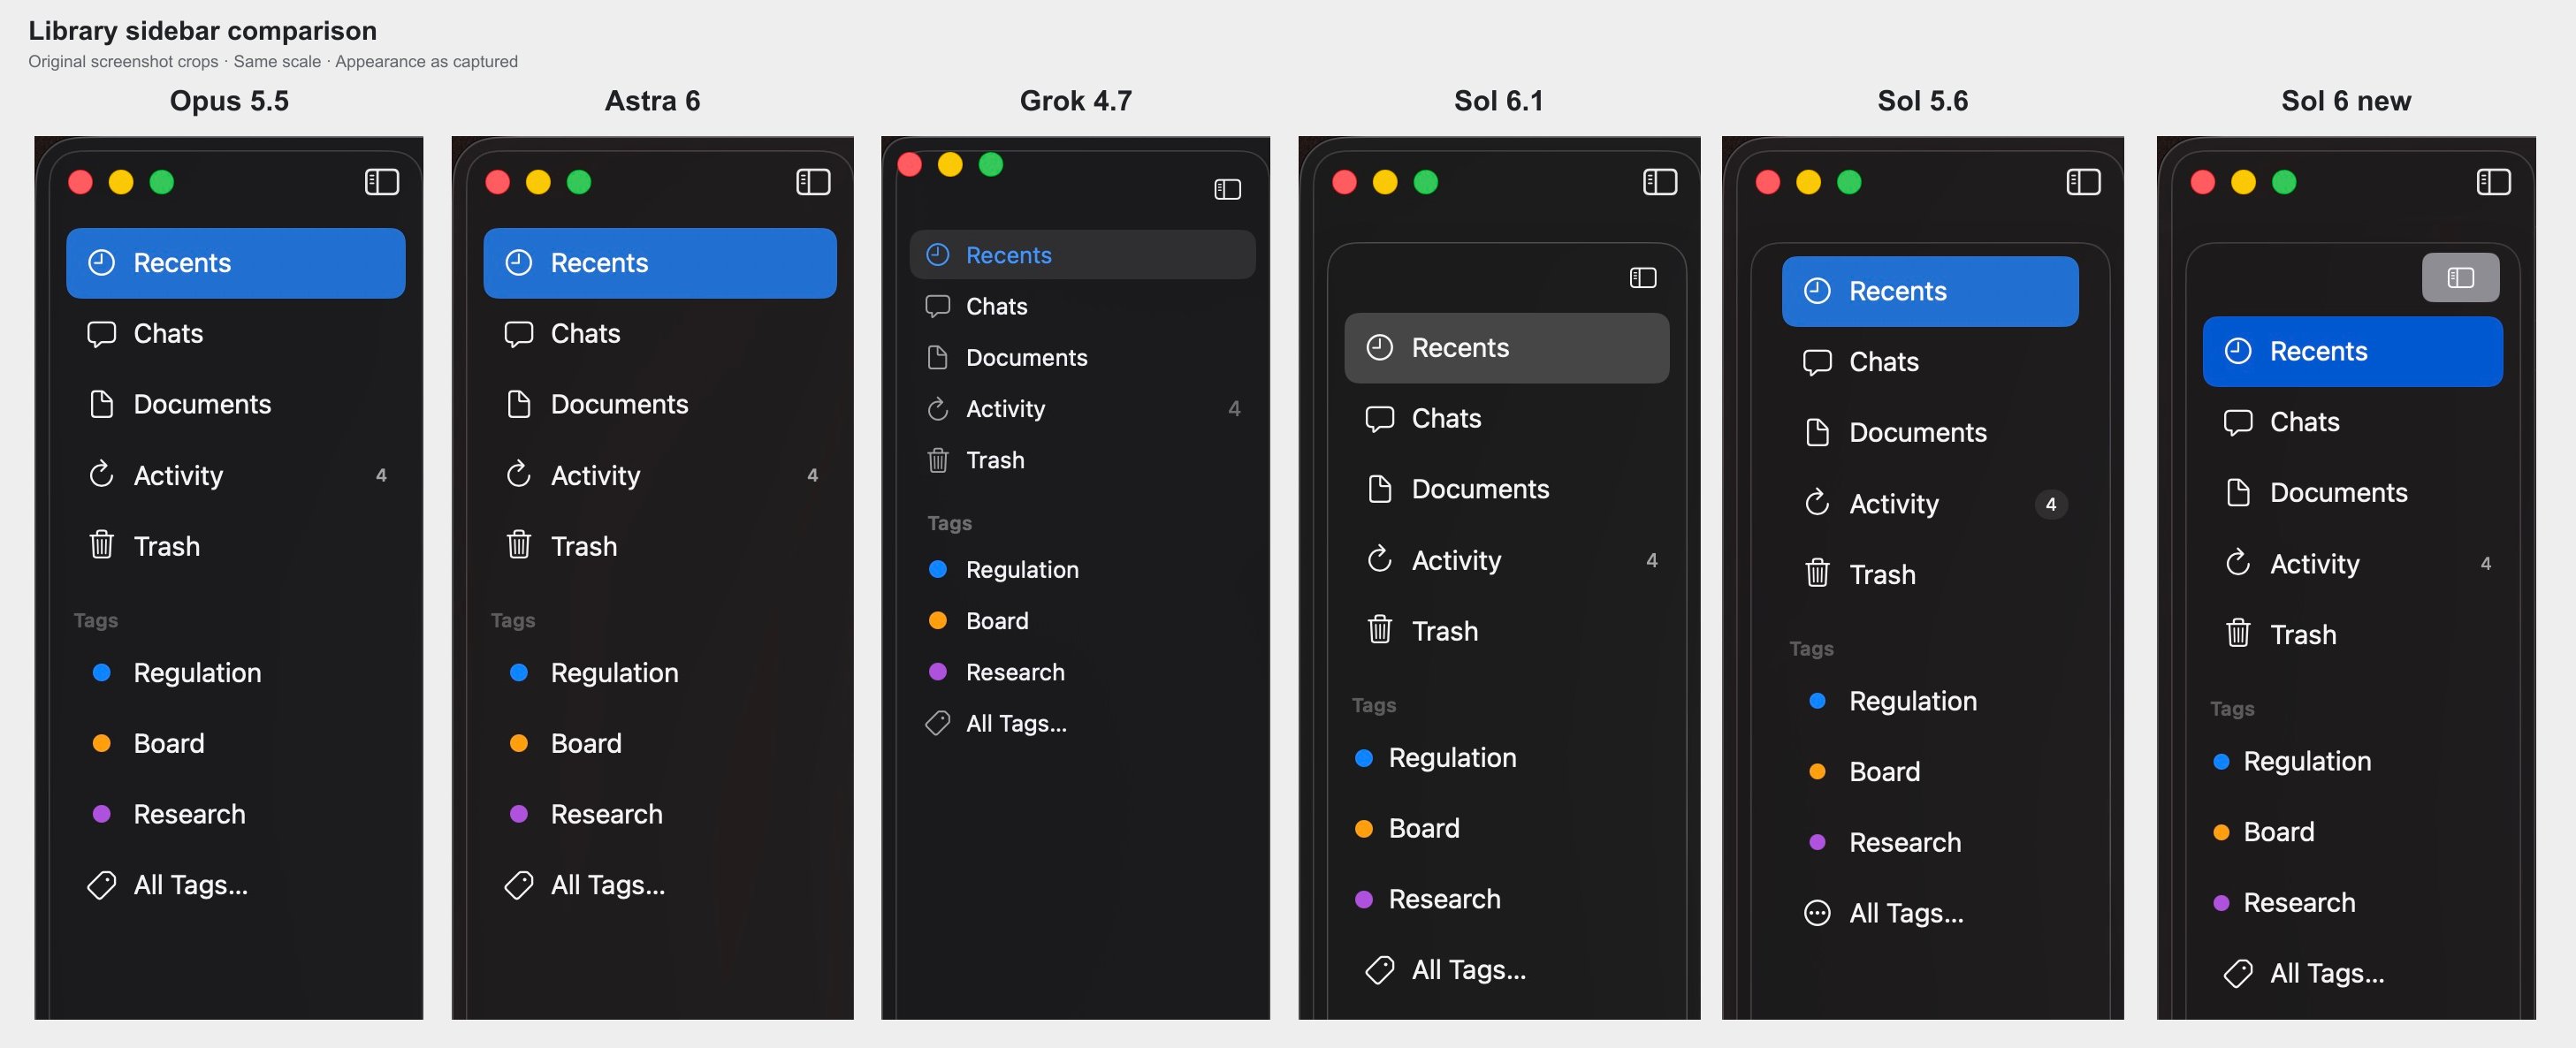
Daniel Nguyen @daniel_nguyenxOriginally posted 2026.09.30
I gave the same task to GPT-6 Astra, GPT-6.1 Sol and Grok 4.7 (all with xhigh reasoning) and here is the result. Overall score: - Opus 5.5: 9.1 - Astra: 8.0 - Grok 4.7 and Sol 6.1: 7.7 - Sol 5.6: 7.5 - Sol 6: 6.9 Opus 5.5 is still a clear winner.
This post quotes another post: x.com/daniel_nguyenx/status/2104152983797895634
x.com/daniel_nguyenx/status/2105109077999444106Archived 2026.10.01 10:13