Cisco tests TypeSafe Jev against purpose-built classifiers
Cisco compared TypeSafe's Jev with a purpose-built classifier: the specialized model had better recall under strict false-positive budgets, while zero-shot Jev came close to a 31B LLM judge, suggesting the two are complementary.
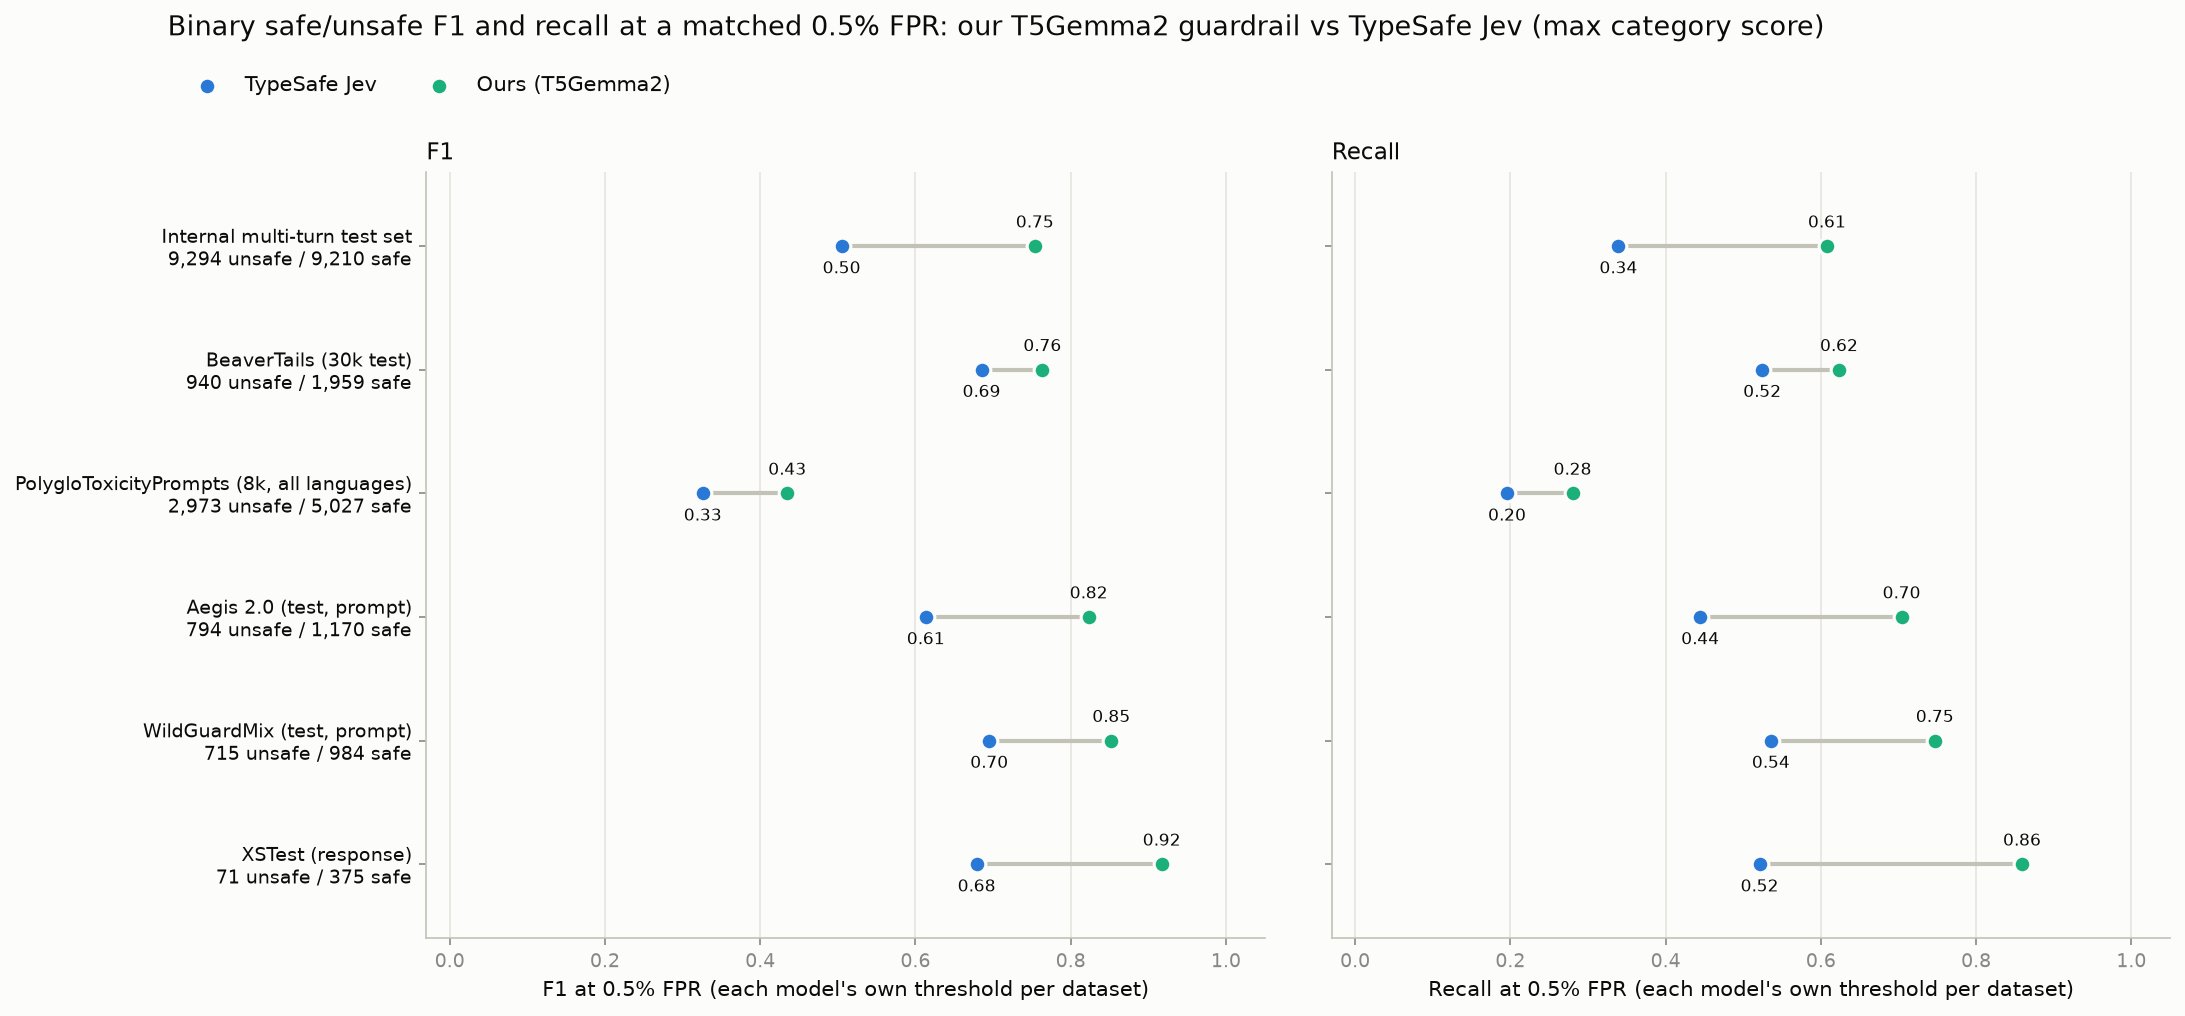
Here at @CiscoAI we tested TypeSafe's Jev against a traditional, purpose-built classifier just so we understand these new class of models better. What we learned was: 1. Policy-specific training still delivers the best recall at strict false-positive budgets. 2. Jev holds up surprisingly well when zero-shot, landing close to a 31B-parameter LLM judge. TLDR: These aren’t competitors so much as complements. Use the classifier model for large volume of known categories, and a decision model for new or shifting categories. Read more here: https://blogs.cisco.com/ai/jev-decision-models-on-trial