Splitting execution from judgment across 300 agents with Jev
After three months of agent self-review the author found it was self-endorsement, so execution moved to a Kimi cluster while Jev decides which agent runs next, whether a result passes and when to stop.
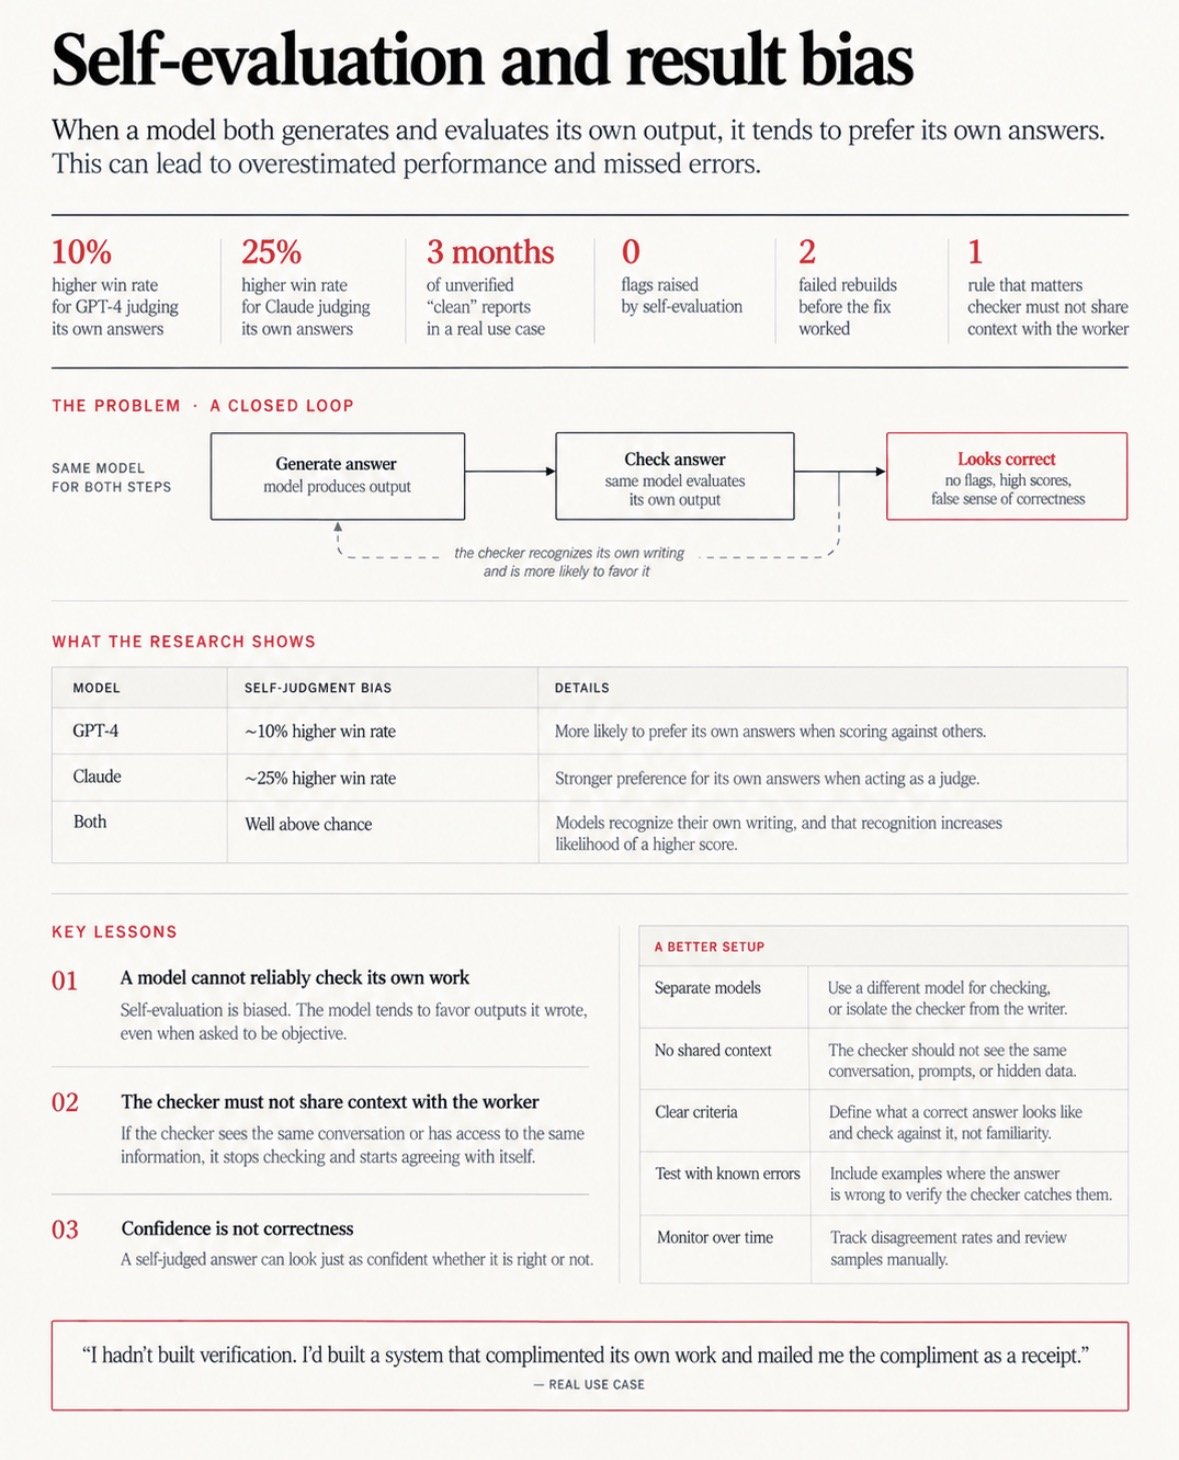
I let one agent grade its own work for three months Everything looked clean because the same model that wrote the answer was also deciding whether the answer deserved to pass. That is not verification, it is the same reasoning approving itself twice The fix is architectural Separate the worker from the judge That same principle becomes even more important when you move from one agent to hundreds. A swarm can research, build, test, and execute at scale, but letting the swarm decide whether its own work is good enough recreates the exact same problem This is where a separate decision layer starts to matter Kimi handles execution across hundreds of agents. Jev sits outside that work and decides which agent runs next, whether a result passes, what happens after a failure, and when the whole loop should stop Execution and judgment become two different jobs Now the system is not asking the worker whether the worker did well. It is giving the result to a separate layer with a different role and a narrow decision to make The video shows why self-review can look reliable while quietly agreeing with itself The article below shows how to separate execution from decision making and turn a 300-agent swarm into a loop that can route, score, recover, and stop without a human watching every turn
This post quotes another post: x.com/0xricker/status/2102396090012115030