GPT-6 Astra reaches 24.8x speedup on KernelBench-Mega
The author tested DeepSeek V4.1 Flash on kernel optimization and compared results: GPT-6 Astra at 24.8x and Fable 5 at 24.6x, while noting a persistent accumulator that is never zeroed.
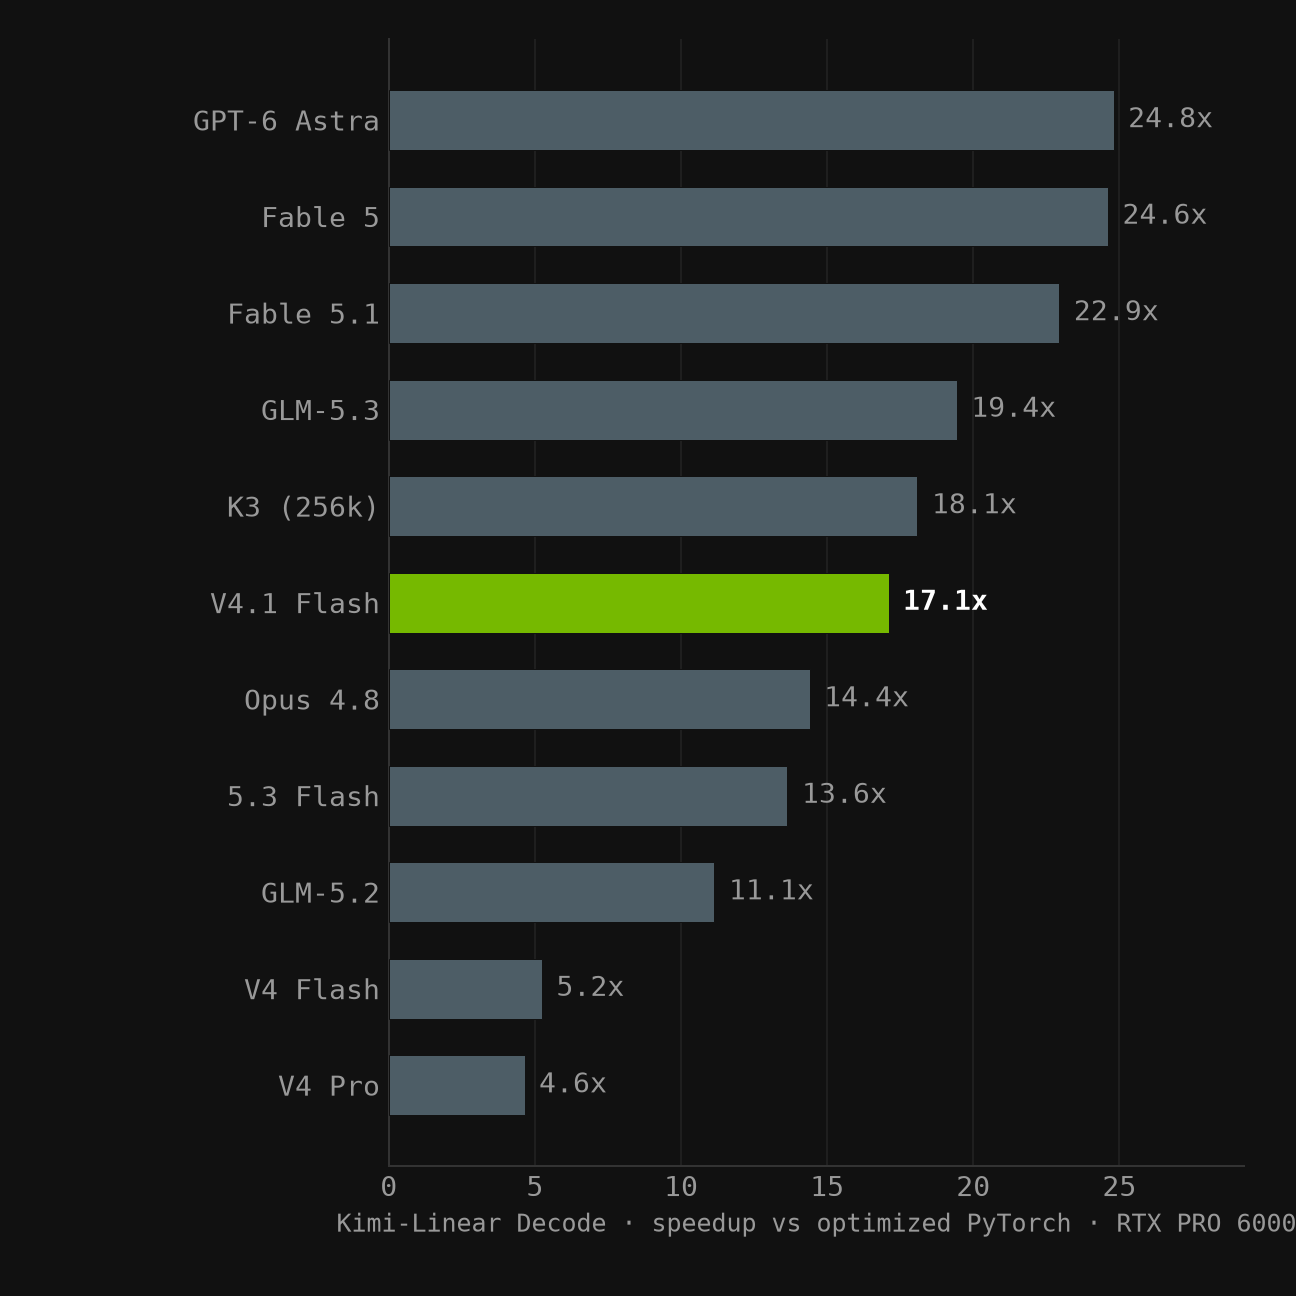
DeepSeek V4.1 Flash on KernelBench-Mega. Kimi-Linear Decode for RTX PRO 6000 at 17.1x the optimized PyTorch baseline. GPT-6 Astra is 24.8x, Fable 5 is 24.6x, V4 Pro was 4.6x. One cooperative launch, 19 grid barriers, everything per token inside it: int4 dequant GEMVs with the zero point folded into the FMAs, the short conv, the gated-delta state update, absorbed MLA over the latent cache with a cross-block softmax merge, router plus eight routed experts. 15.8x at 2K context, 17.8x at 16K. 3.2 hours on an unlimited budget, exited on its own. The thing to know: a persistent atomicAdd accumulator is never zeroed, so from the second KDA layer on, every layer inherits the previous one's activations. Output cosine 0.9997 on the first token and 0.98 on the next, which passes the 0.98 gate. Zeroing it costs nothing. It stands as interesting, not clean. For this model for DeepSeek, I have not used it much, so I figure I'll at least test it before using it, but it's been a decent general task delegator for now. I haven't really pushed the limits of the model except for this benchmark. https://kernelbench.com/mega