DeepSeek V4.1 Flash on a 4x DGX Spark cluster: 142 tok/s code, 5.1K tok/s prefill at 256K
Using SGLang, TP4, dual RoCE rails and speculative decoding on four DGX Sparks, V4.1 Flash hits 142.4 tok/s on code, 126.7 tok/s at 64K context, and 71/75 on qeval.
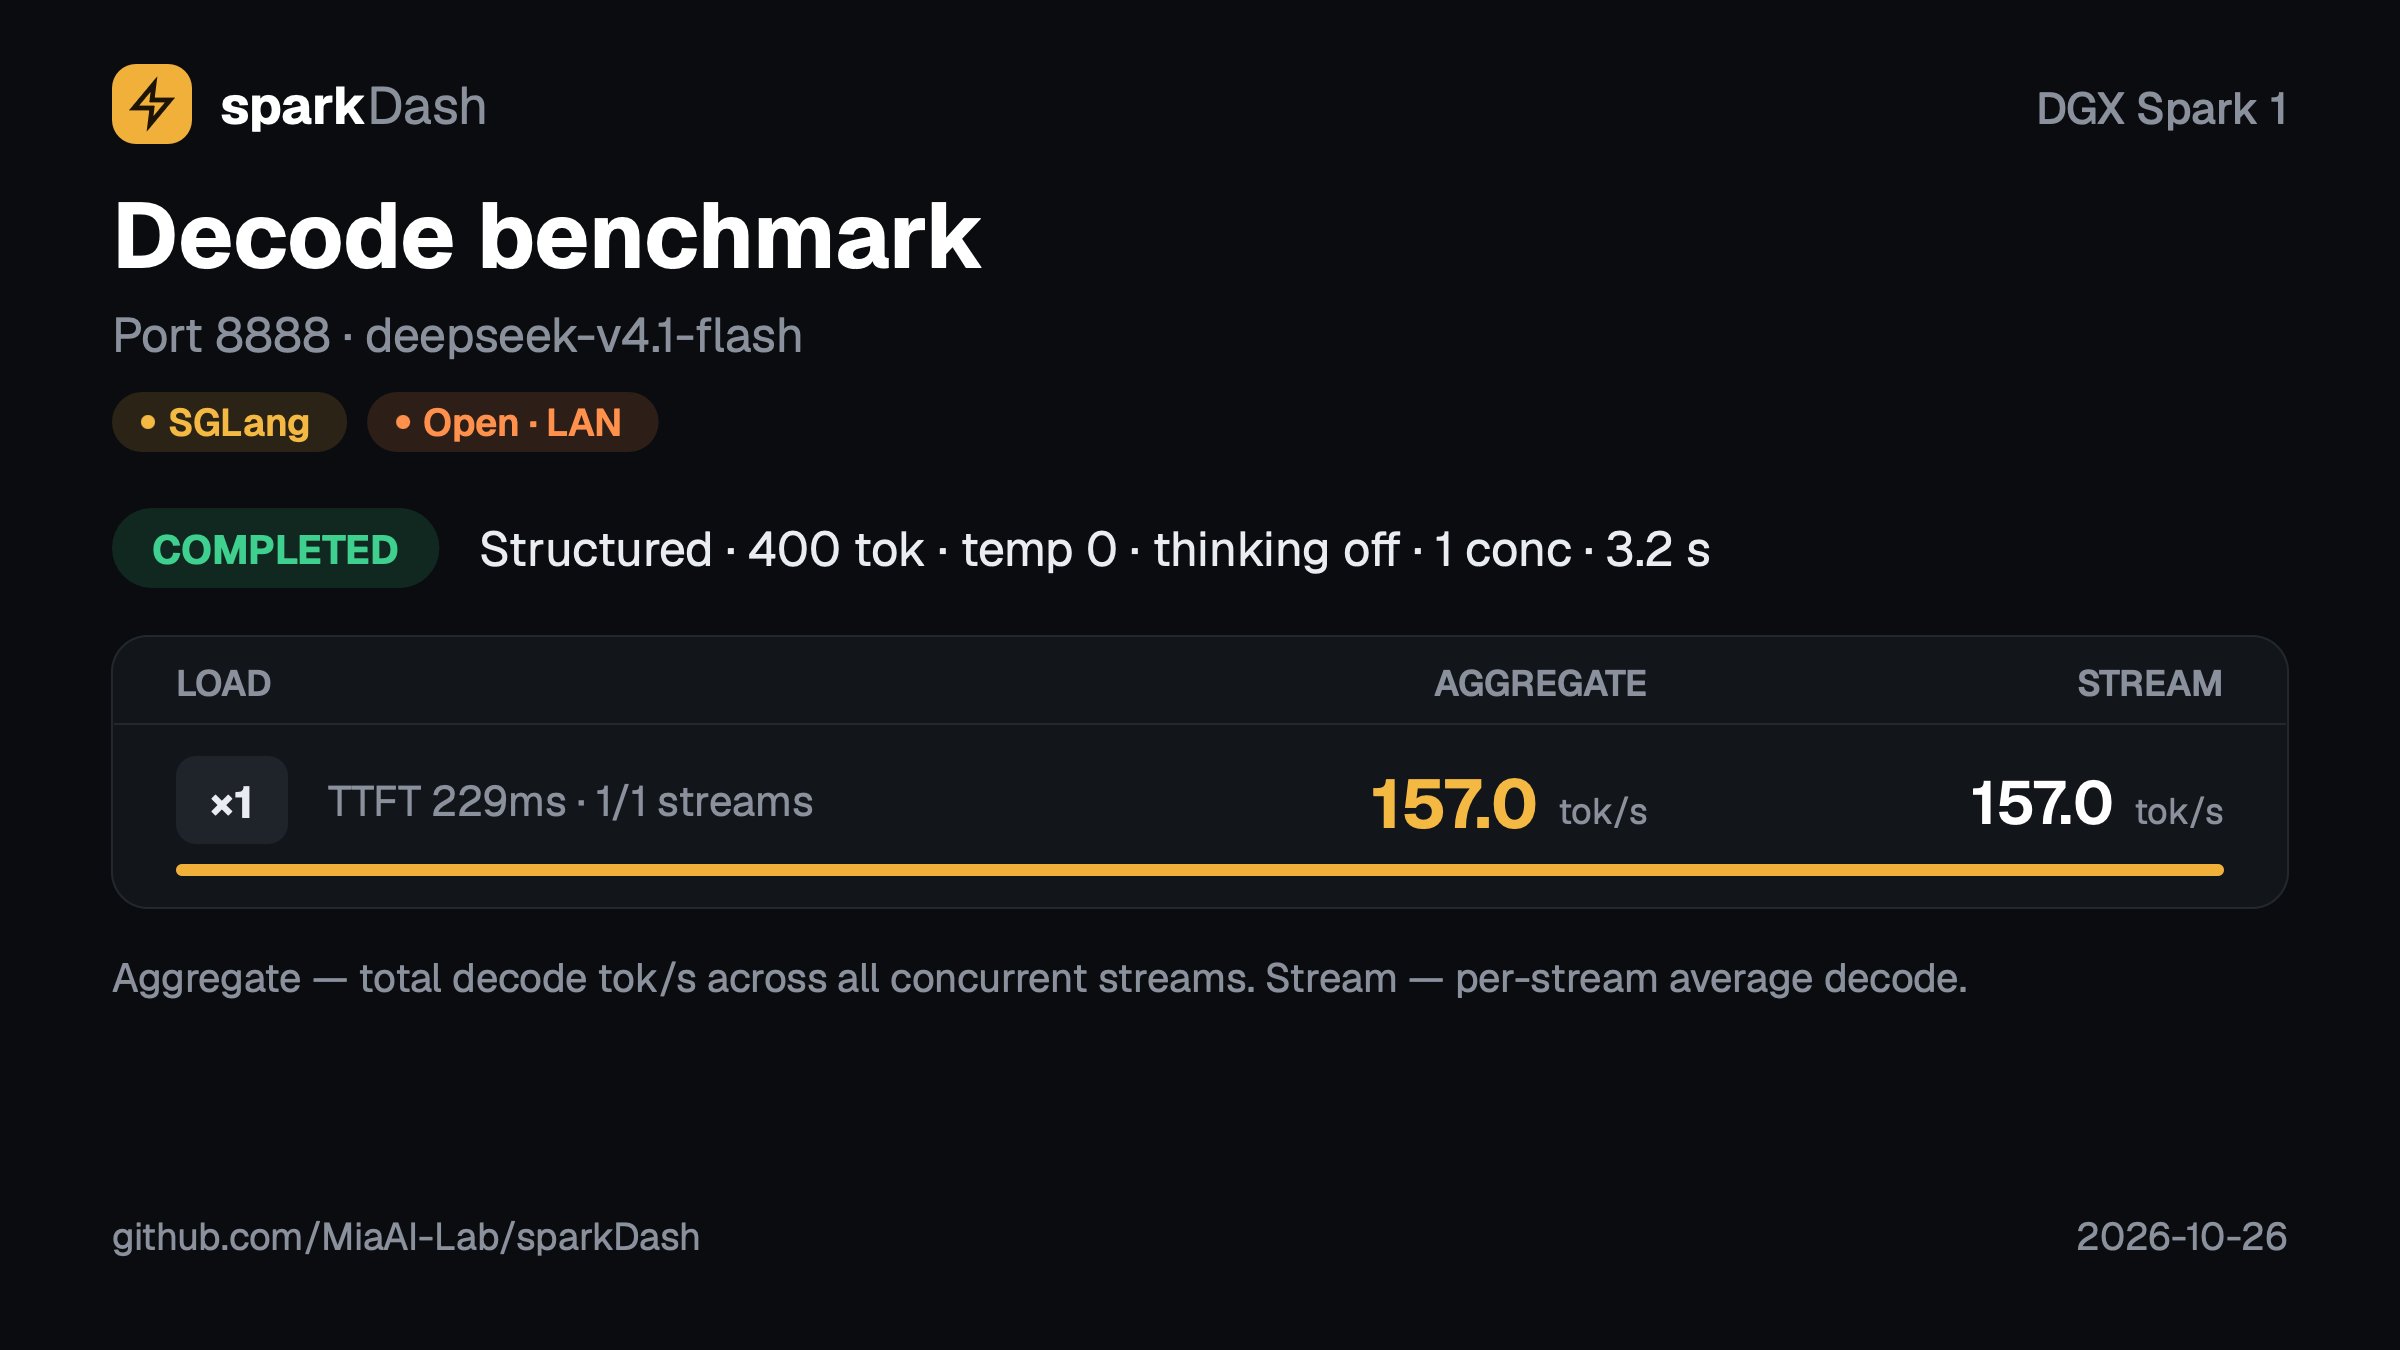
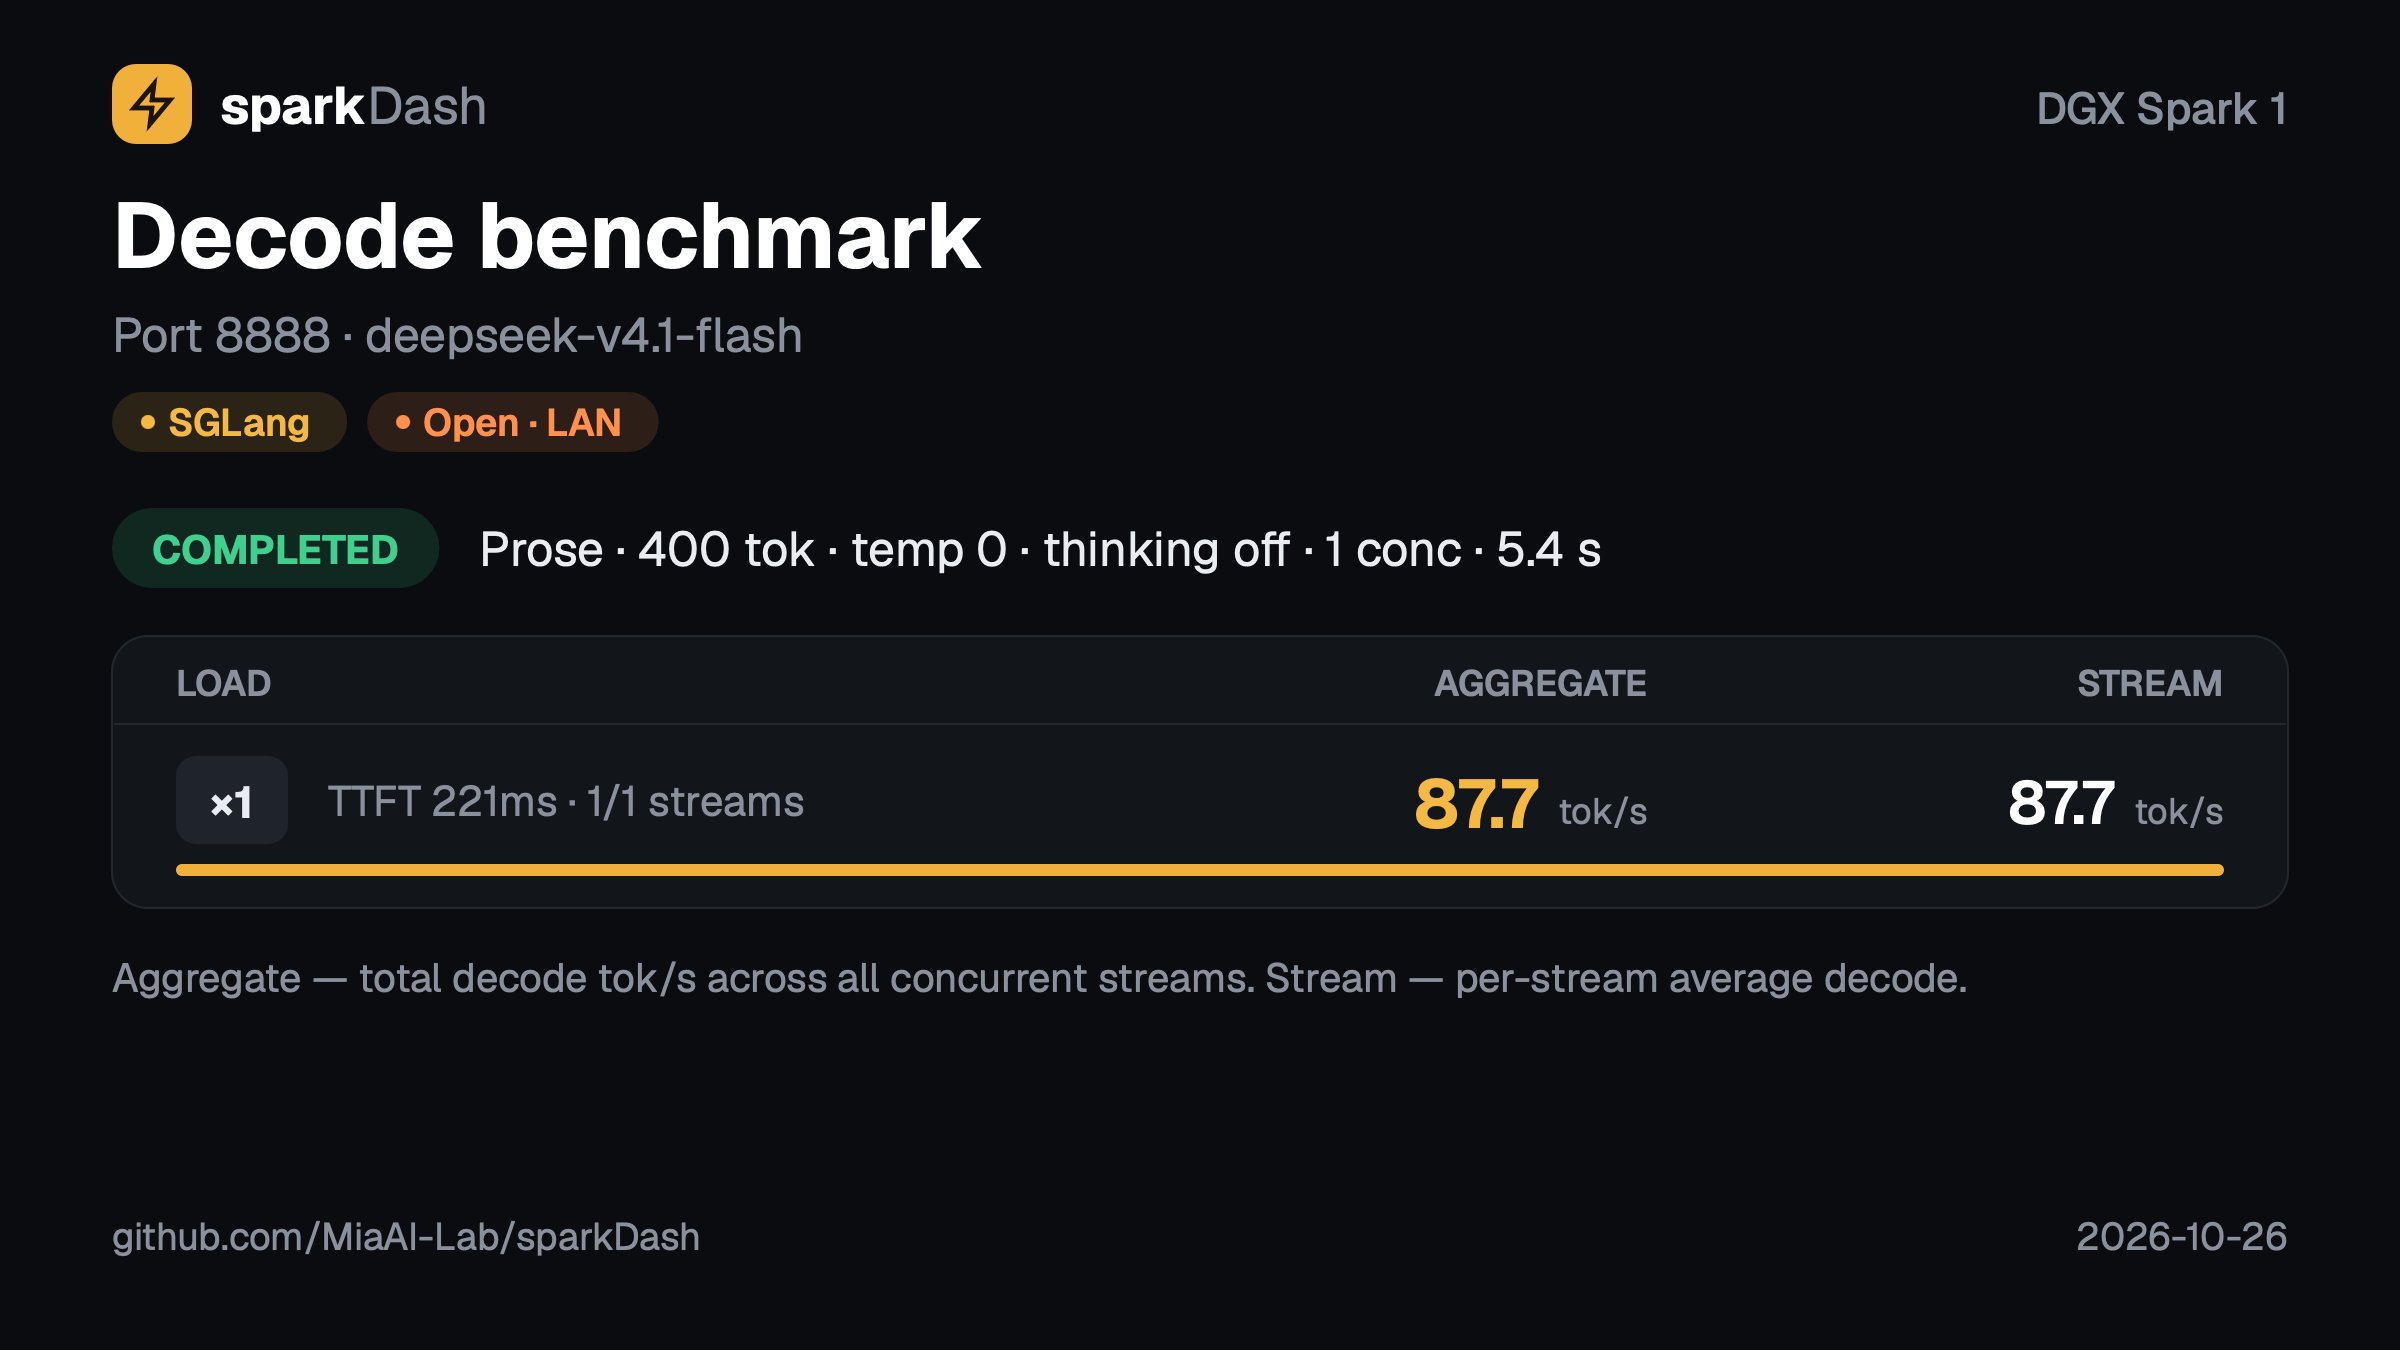
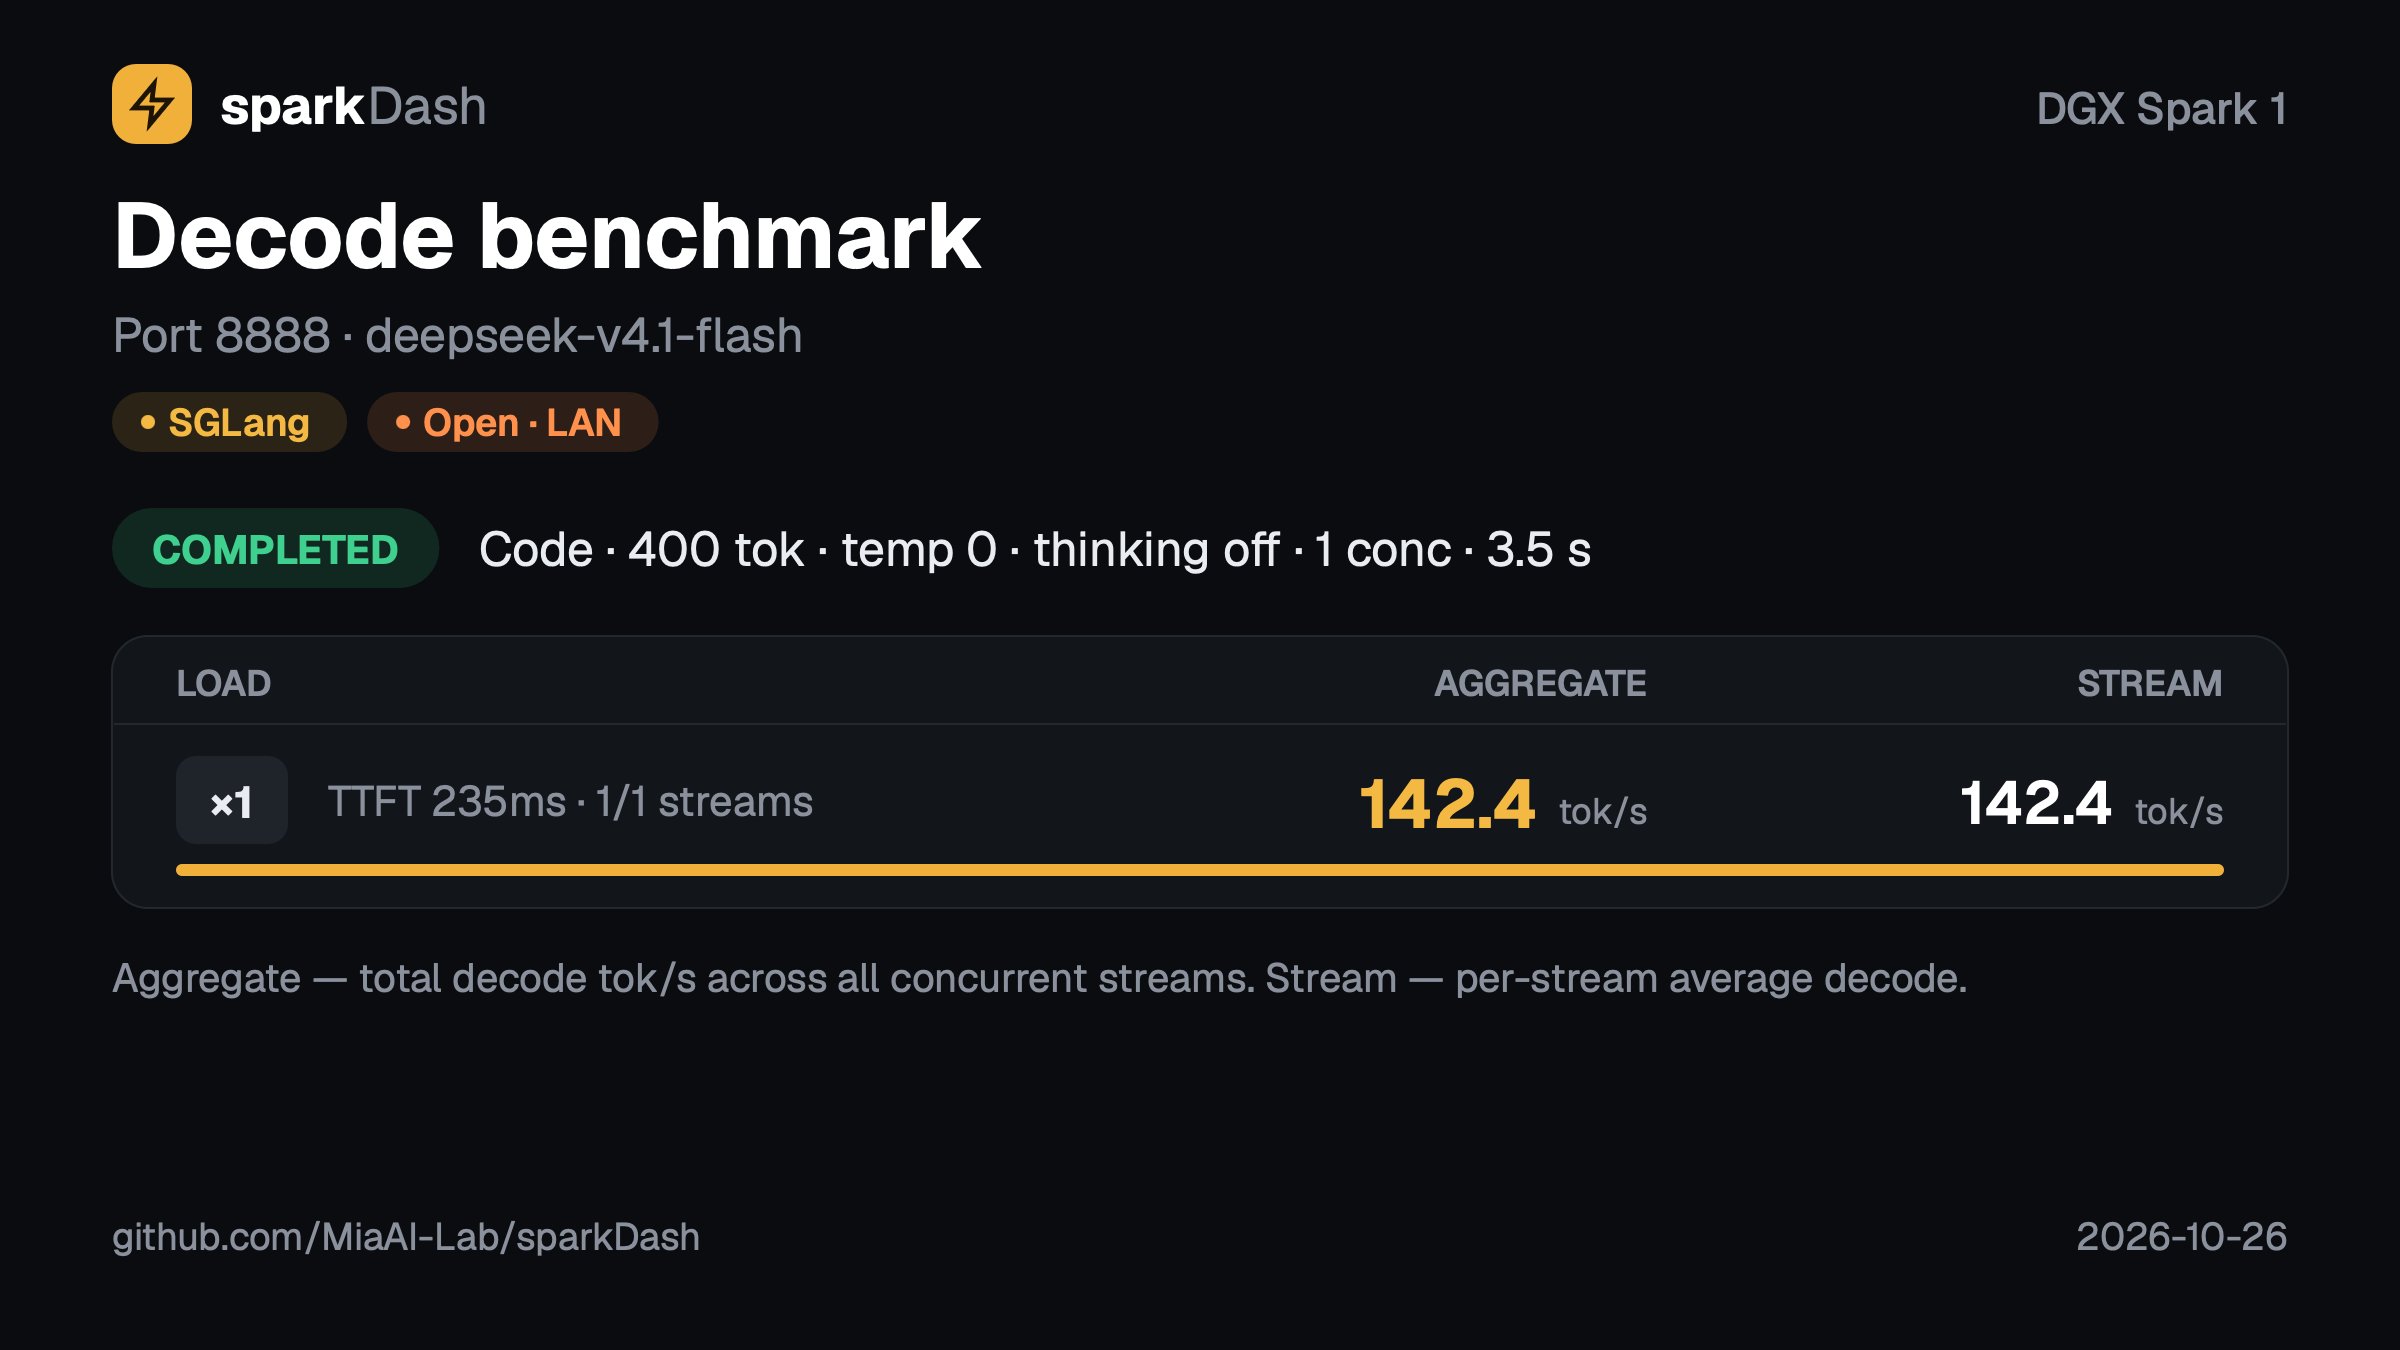
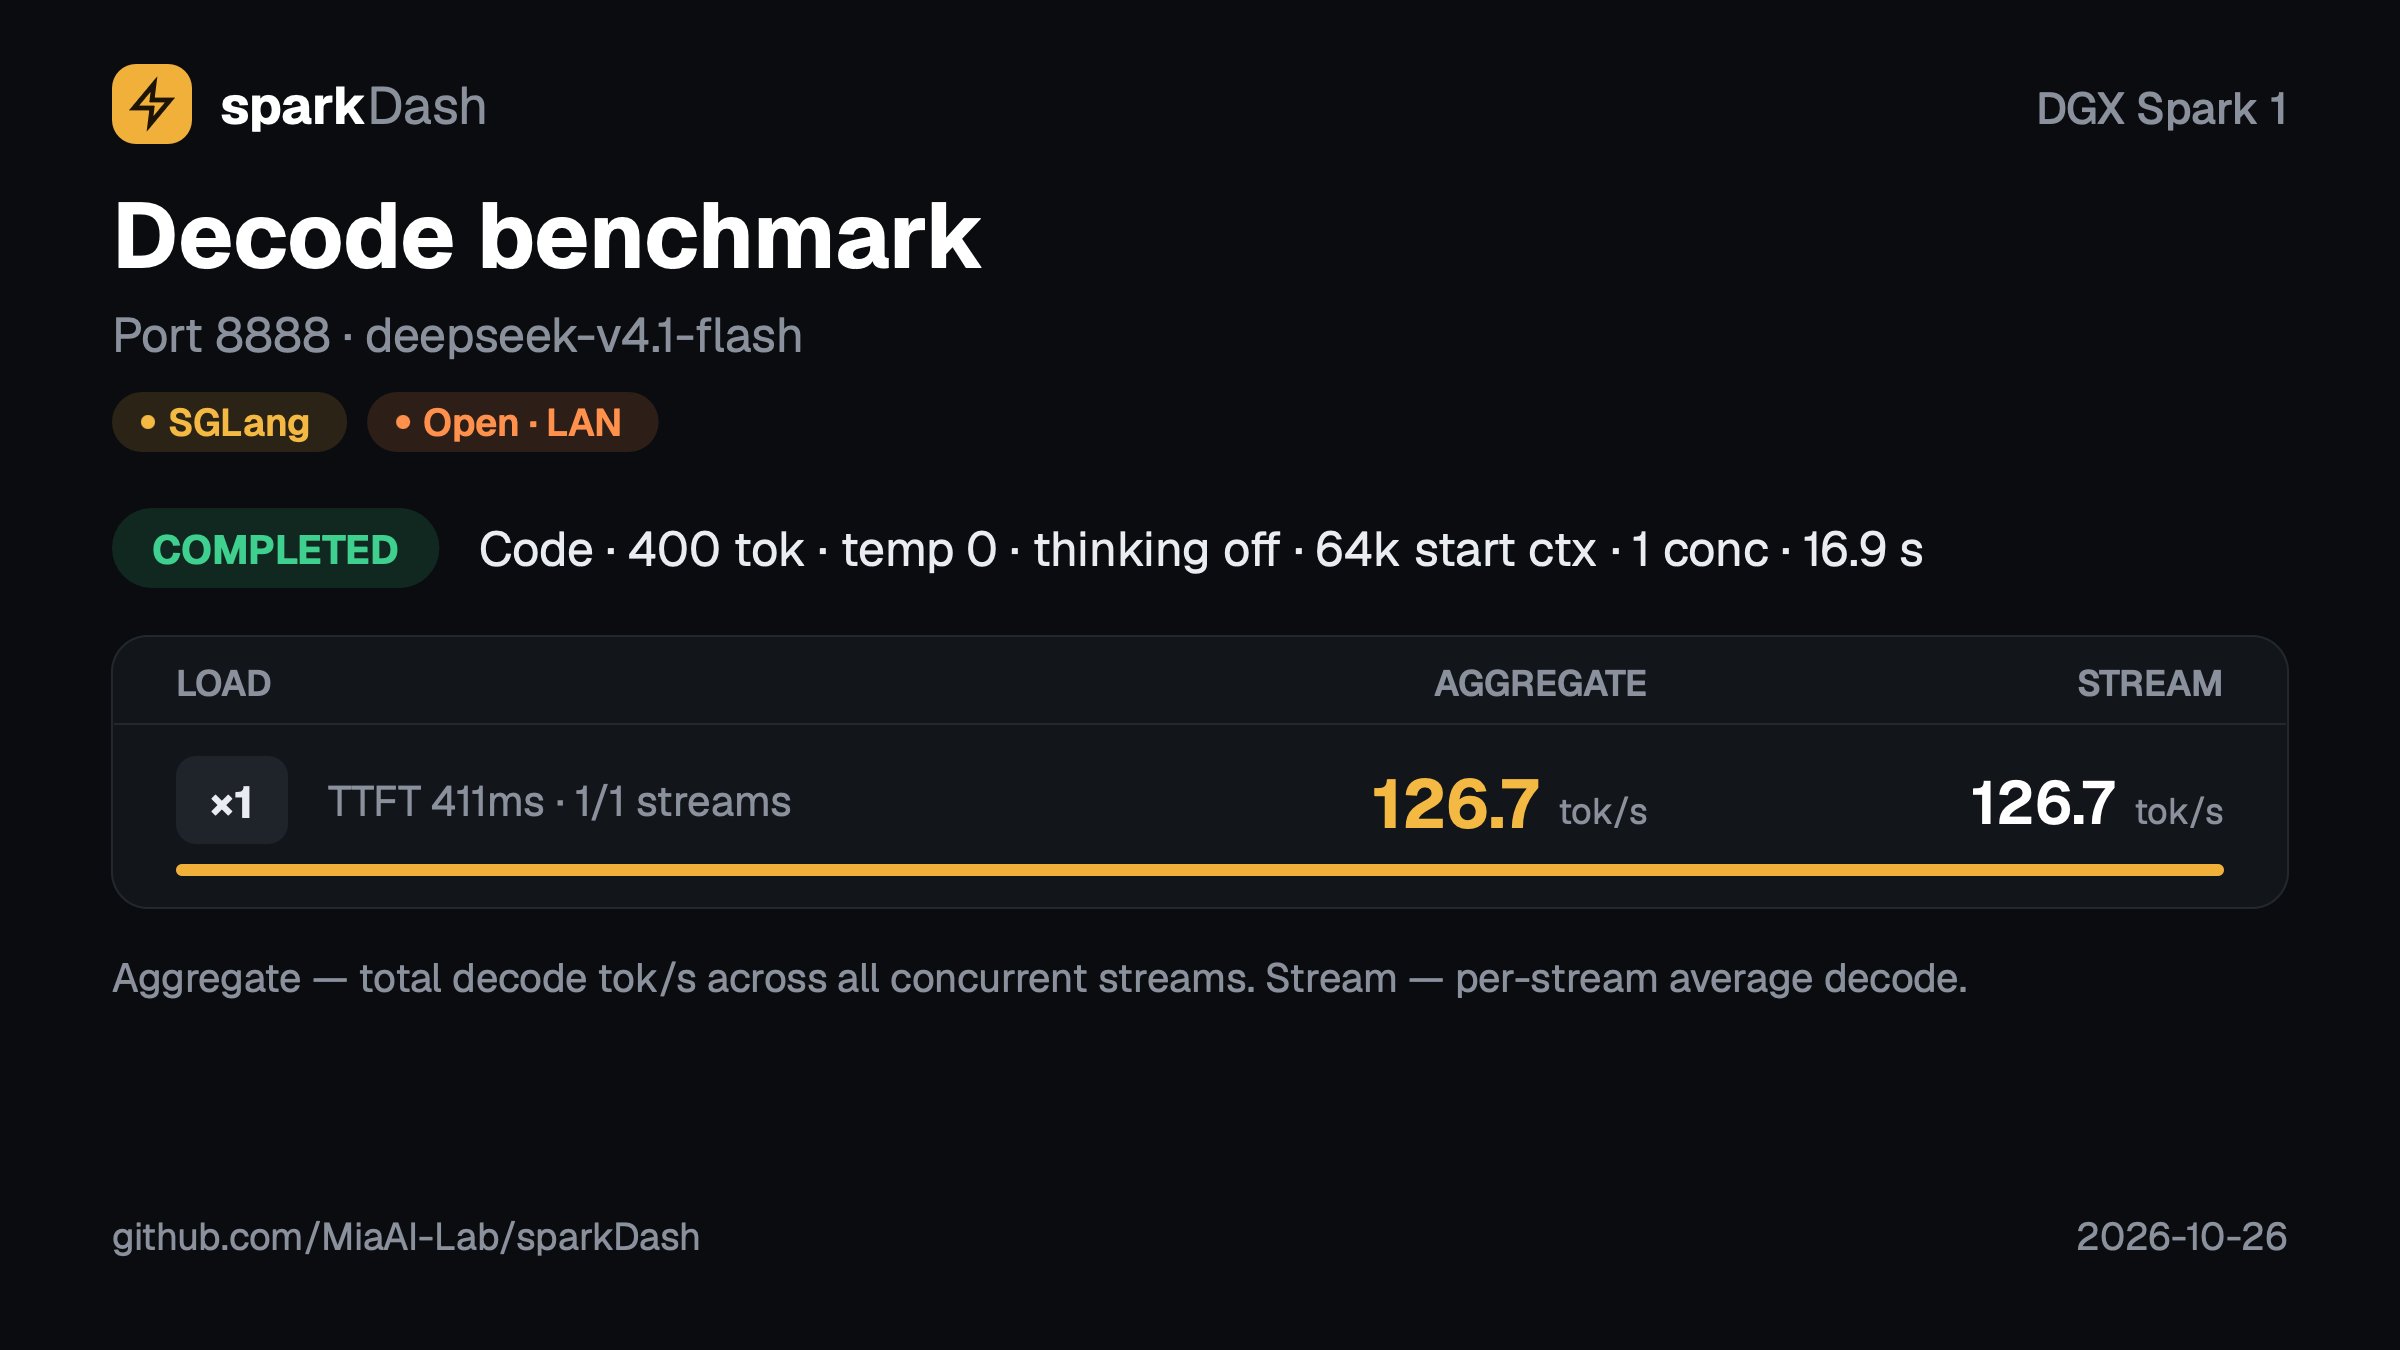
Finally got DeepSeek-V4.1-Flash-1017 running properly across my 4× NVIDIA DGX Spark cluster. Repo: https://github.com/knapcio/DeepSeek-V4.1-Flash-4x-DGX-Spark-TP4 Model: deepseek-ai/DeepSeek-V4.1-Flash-1017 revision: 1bae0e1088993b9b82de08f59de5be5a34e42170 My setup: • 4× DGX Spark / GB10 • TP4 / EP1 • SGLang canary • 2× 200GbE RoCE rails through MikroTik CRS812 • RoCEnante • B12X-next routed MoE • DSpark speculative decoding, block size 5 • packed local Engram shards on every node • FP8 KV cache • 1,048,576 context • 16 concurrent requests Production settings: • CHUNKED_PREFILL_SIZE=8192 • MEM_FRACTION_STATIC=0.78 • HEAD_MEM_FRACTION_STATIC=0.78 • DSV41_CACHE_GIB=4 • NCCL_IB_TC=104 • NCCL_PROTO=^LL128 • NCCL_MAX_NCHANNELS=8 Also patched the older RoCEnante path so it actually honors NCCL_IB_TC=104 instead of silently using TC0 Runtime validation: • RoCEnante active on both rails • B12X next active at EP1 • shared expert K pad 576→640 accepted by b12x • RoCE compact gather active • all 4 containers healthy • qeval: 71/75 sparkDash results: Structured C1: 157.0 tok/s - TTFT 229 ms Prose C1: 87.7 tok/s - TTFT 221 ms Code C1: 142.4 tok/s - TTFT 235 ms Code C1 @ 64K context: 126.7 tok/s - TTFT 411 ms Prefill: 64K: 5,953.7 tok/s 128K: 6,026.2 tok/s 256K: 5,137.9 tok/s This is the first DeepSeek V4.1 Flash setup on my Sparks where the whole stack - model, RoCE, NCCL, MoE, Engram and speculative decoding -feels properly tuned as one system rather than a collection of individual optimizations. Very impressive work in the @majewskizby repo.