Storyboard prompt template for animation, compared across four models
A 2x2 grid prompt template generates storyboard images for animation videos, controlling style by era, production tier and time, with results compared across GPT Image 2.5, Nano Banana, Seedream 5.0 Pro and Reve.
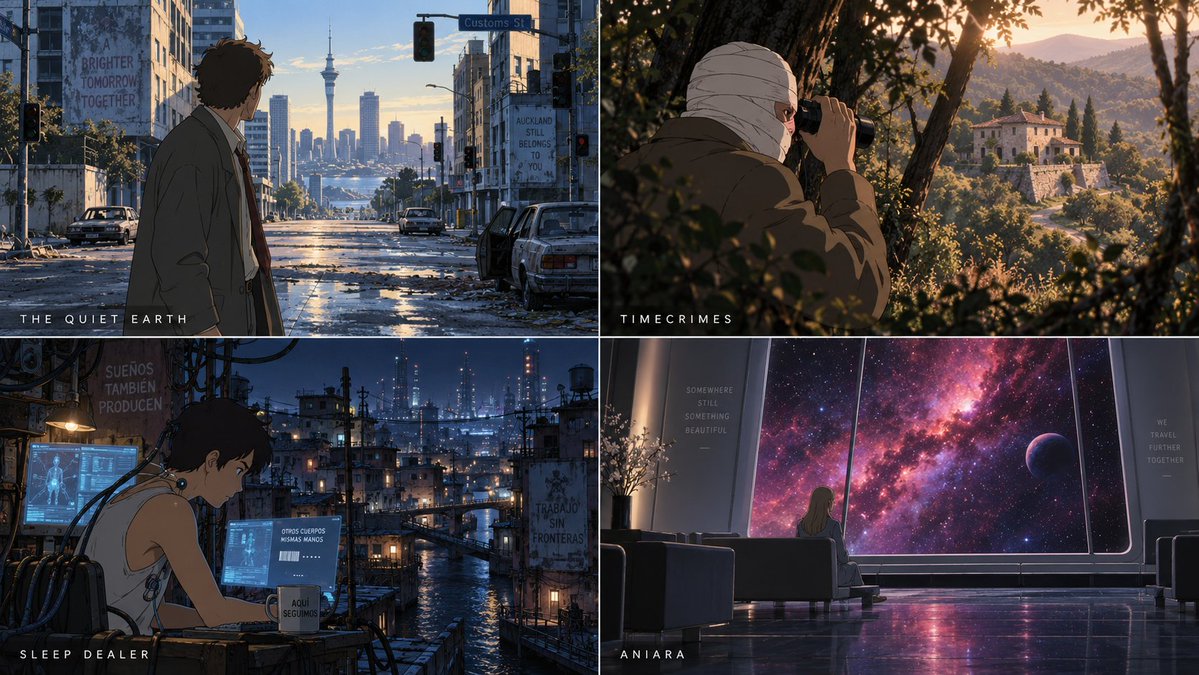
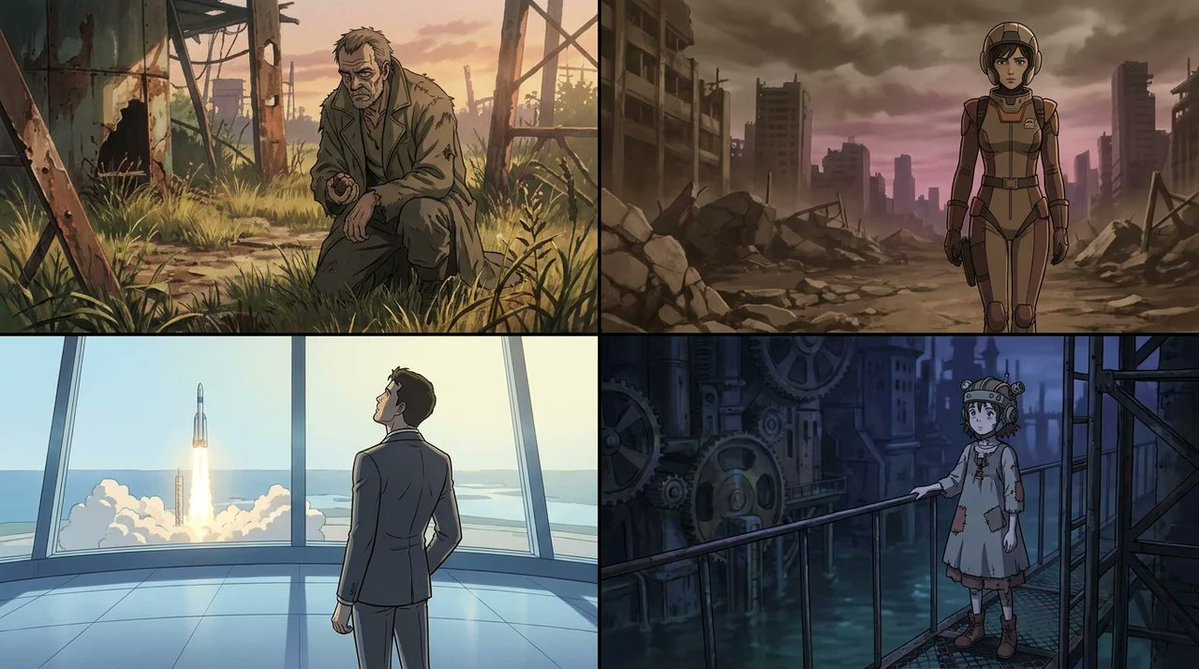
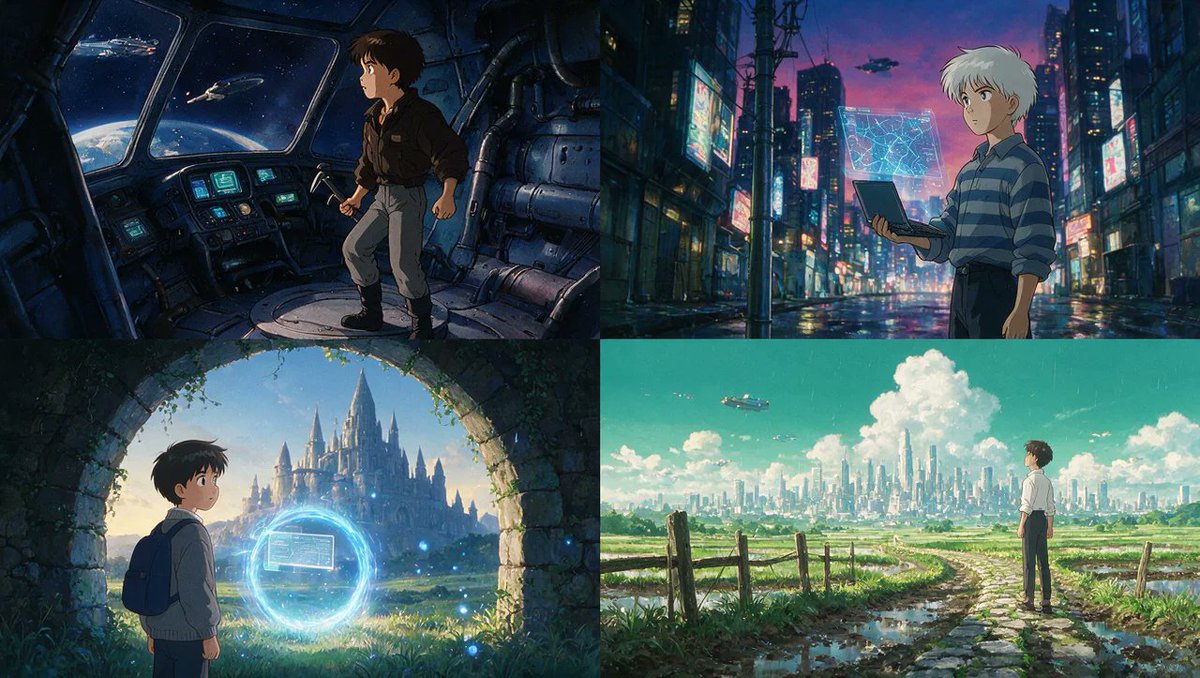
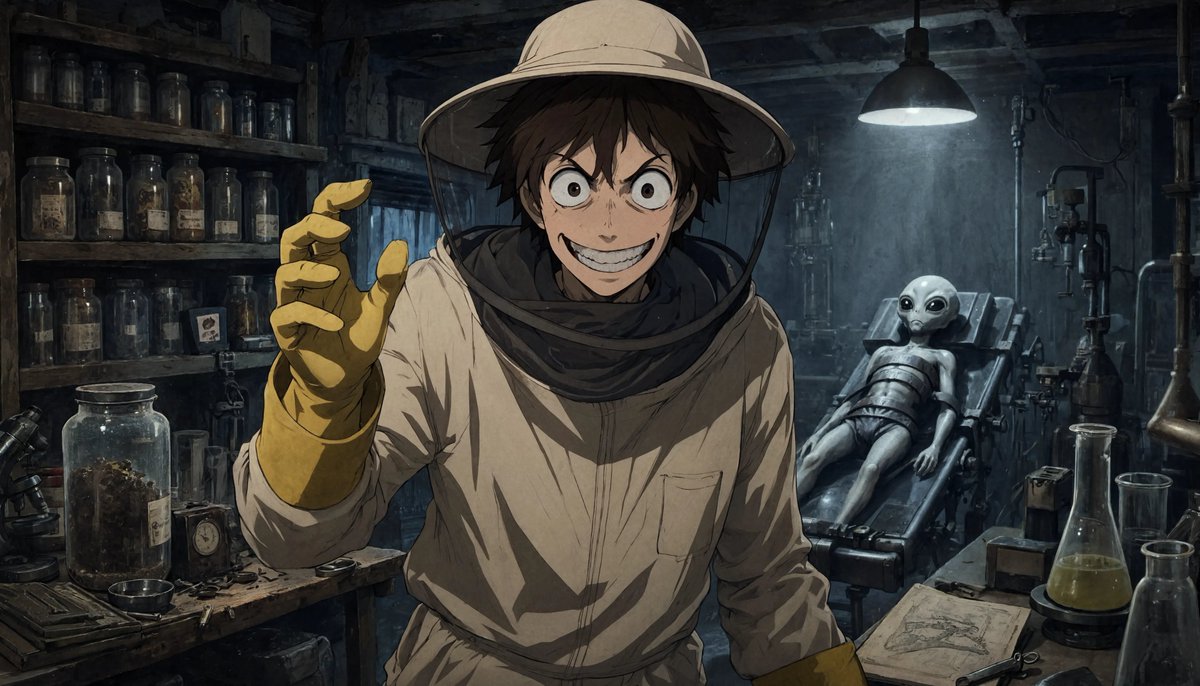
A prompt template for generating images for image to video prompts for animation videos. GPT Image 2.5, Nano Banana, Seedream 5.0 Pro vs. Reve Prompt: 2x2 grid, 16:9, do this for 4 underrated international scifi movies: // FN: anime_still(CHARACTER, SETTING, TIME, ERA, TIER, MOOD) INPUT CHARACTER = $ infer SETTING = $ infer TIME = $ infer ERA = $ infer TIER = $ infer MOOD = $ infer DISPATCH :: ERA → production reality 1980-92 cel : hand-painted, RICH saturated paint, visible cel dust and fine scratches, slight registration wobble, 1 shadow step, dark brown-black line, painted BG with heavy brush texture 1993-99 cel→digital : transitional, cleaner paint, 1–2 steps, first digital compositing, BG still painted, slight color banding 2000-10 digital : flat digital paint, 2 steps common, rim light appears, BG digitally painted but still soft-edged and detailed 2011+ digital : 2 steps + gradient allowed ONLY in the photography pass, heavy bloom and diffusion, BG photo-referenced, thin lines DISPATCH :: TIER → detail budget (this is the realism lever) tv_weekly : minimal line count, simple shadow shapes, BG reused-looking, character held on 3s, no complex effects tv_premium: more line detail in key frames, 2-step shadow on the face film : dense linework, complex shadow shapes following real anatomy, highly detailed BG, subtle effects layer, held poses are rare ova : film detail, darker palette, more mature proportions DISPATCH :: TIME → palette swatch set + shadow direction + photography grade morning : cool blues and pale yellow, long shadows, clean bloom midday : high-key, minimal shadow, saturated greens outside late_afternoon : warm ochre/rose BG, LONG horizontal shadows, heavy bloom through windows, dust motes, orange gradient map over all dusk : magenta-to-indigo BG, silhouettes, warm rim on one edge night : deep blue-violet, cool shadow swatch, practicals as bloom sources, character lit only where a light source justifies INVARIANT LAWS // do not vary with any input L_BG : painted, NO outlines, MORE detail than the character L_LINE : constant weight, tapered ends, dark brown not black for skin L_FILL : flat, no gradient, no texture, no noise L_SHADOW : hard-edged, {ERA.steps} step(s), a SEPARATE cooler swatch — not the base color multiplied. The boundary is a drawn line. L_HIGHLIGHT : flat, hard, sparse. Hair gets ONE band. Eye catchlight is a fixed shape that does NOT track the light source. L_FX : drawn discrete elements, never particle simulation L_PHOTO : the ONLY layer permitted soft gradients — bloom, diffusion, grade, grain, applied to the flattened stack FORBIDDEN ✗ gradient shading on the character ✗ soft shadow edges ✗ outlines on background elements ✗ character out-detailing the BG ✗ line weight varying with light ✗ per-pixel specular on skin ✗ photographic DOF on the BG (painted soft ≠ lens blur) RENDER Anime still, {ERA.medium}, {TIER} production. {CHARACTER} in {SETTING}, {TIME}. {TIME.palette}. Background painted with {L_BG}. Character in {L_LINE}, {L_FILL}, shadows as {ERA.steps} hard-edged step(s) in a cooler swatch with no soft falloff anywhere. {L_HIGHLIGHT}. {TIME.fx}. Over everything: {L_PHOTO}. {MOOD.pose_hold}. AUDIT shadow_boundary_gradient ≈ 0px · shadow_steps == ERA.steps detail(BG) > detail(character) · line_weight_variance ≈ 0 every soft gradient originates in L_PHOTO