Jev on long-horizon browser tasks: 1/20 vs 17/20
A developer benchmarked Jev on long-horizon browser tasks and it scored 1/20 against 17/20 for BrowserCode + Luna, though it is extremely fast; he is trying to compensate for weak reasoning with better memory and search.
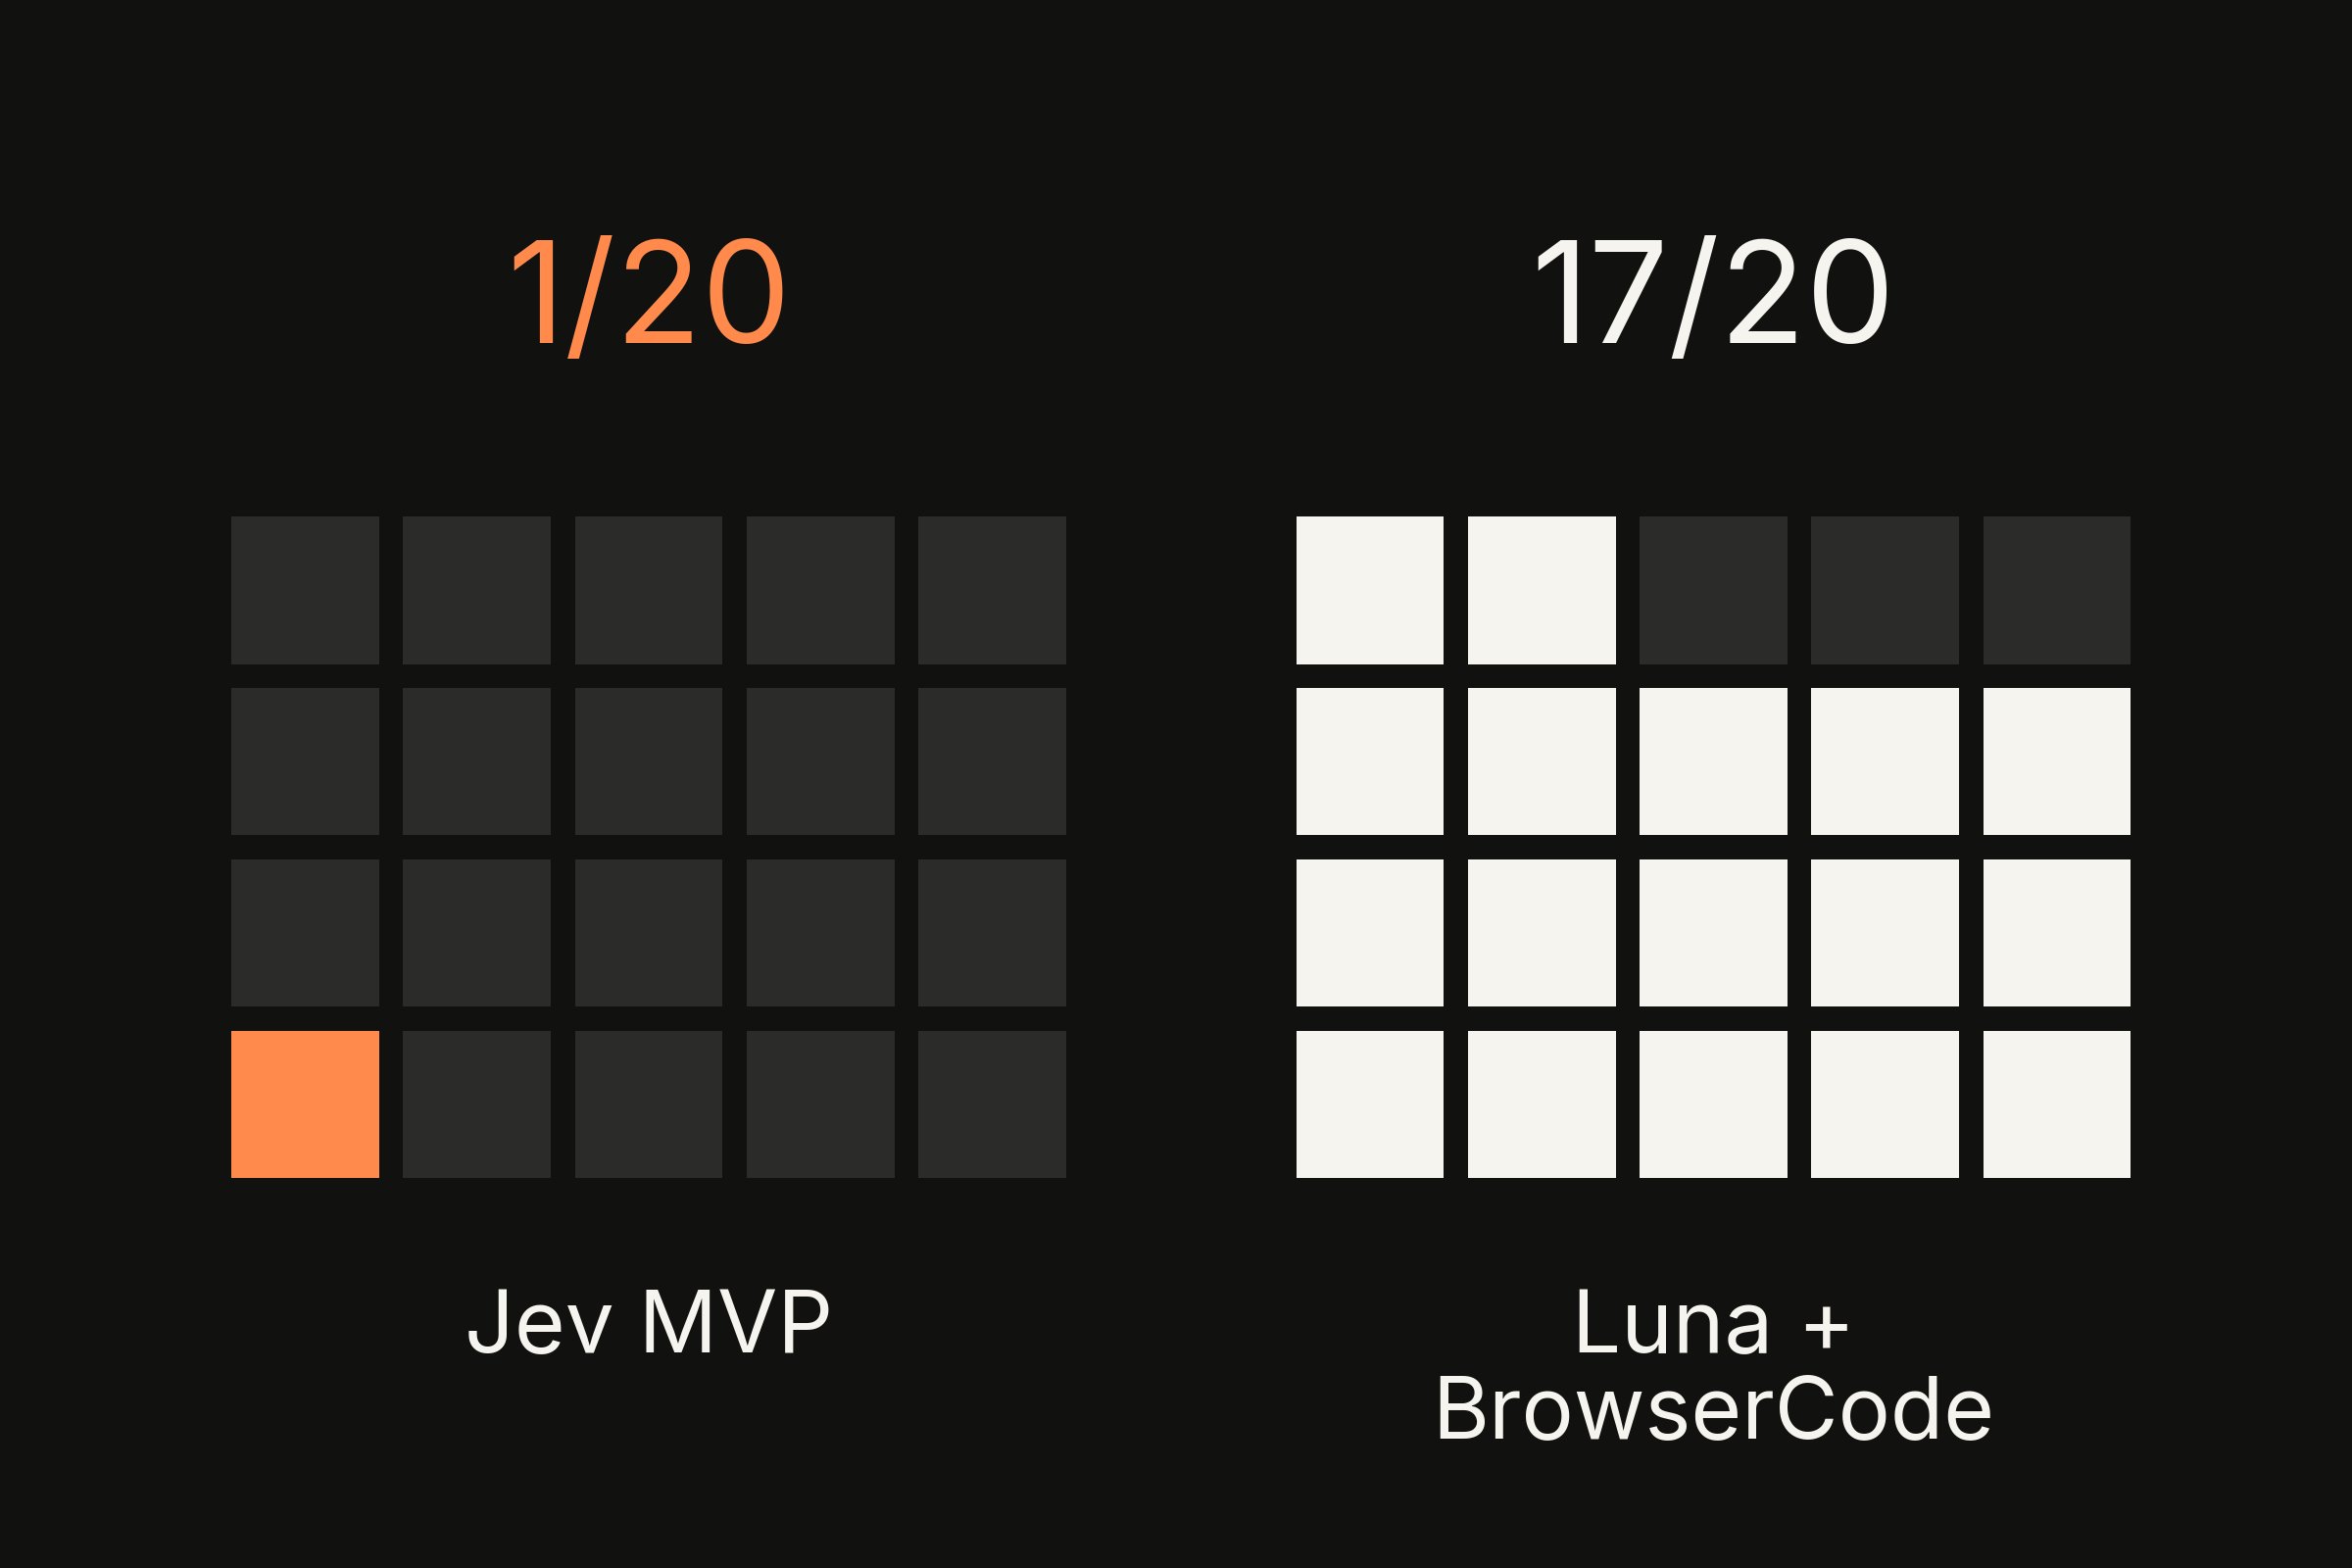
Jev agent got 1/20 vs 17/20 for BrowserCode + Luna on our long horizon task benchmarks. The speed is INSANE. Feels like early Browser Use.(loads of potential, unsolved problems) Browser use is very complex state space search. Very often you just have to think hard or go back. A model with 0 reasoning ability simply can't do that (yet?). Can we get that behavior with better memory + search, without adding a reasoning model? Really hope I can make this work.
This post quotes another post: “Browser Use + Jev finds flights in 7 seconds for about $0.0039”