Developer tests Jev's probability calibration: fails 7 of 8 datasets
A developer replicated Jev's low-latency decision API with Qwen and DiffusionGemma and ran 16.5k predictions to question its calibration, arguing that structured outputs and cost advantages can be matched by off-the-shelf models.
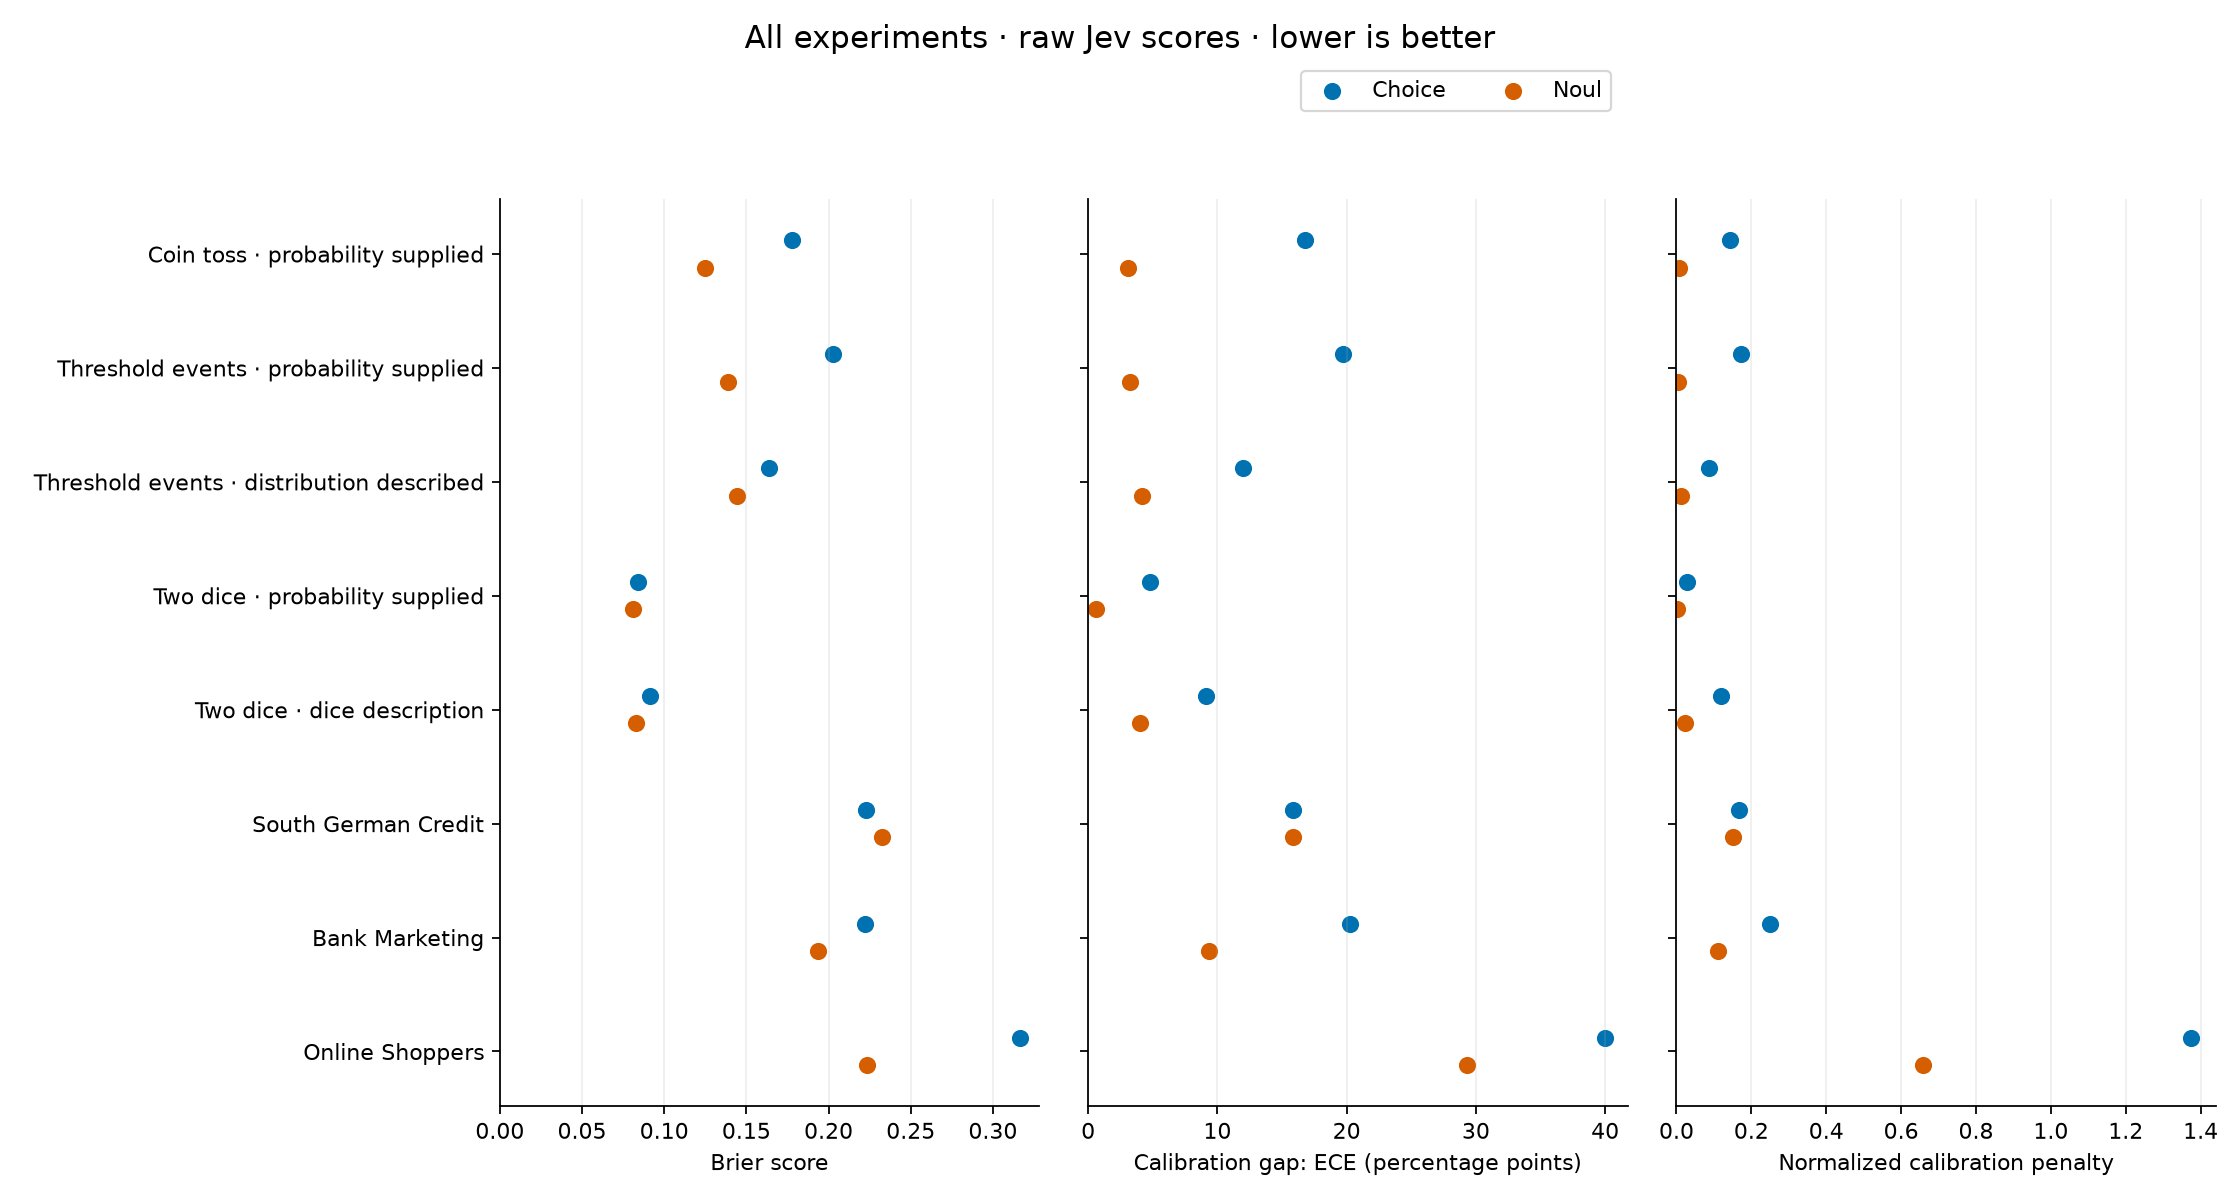
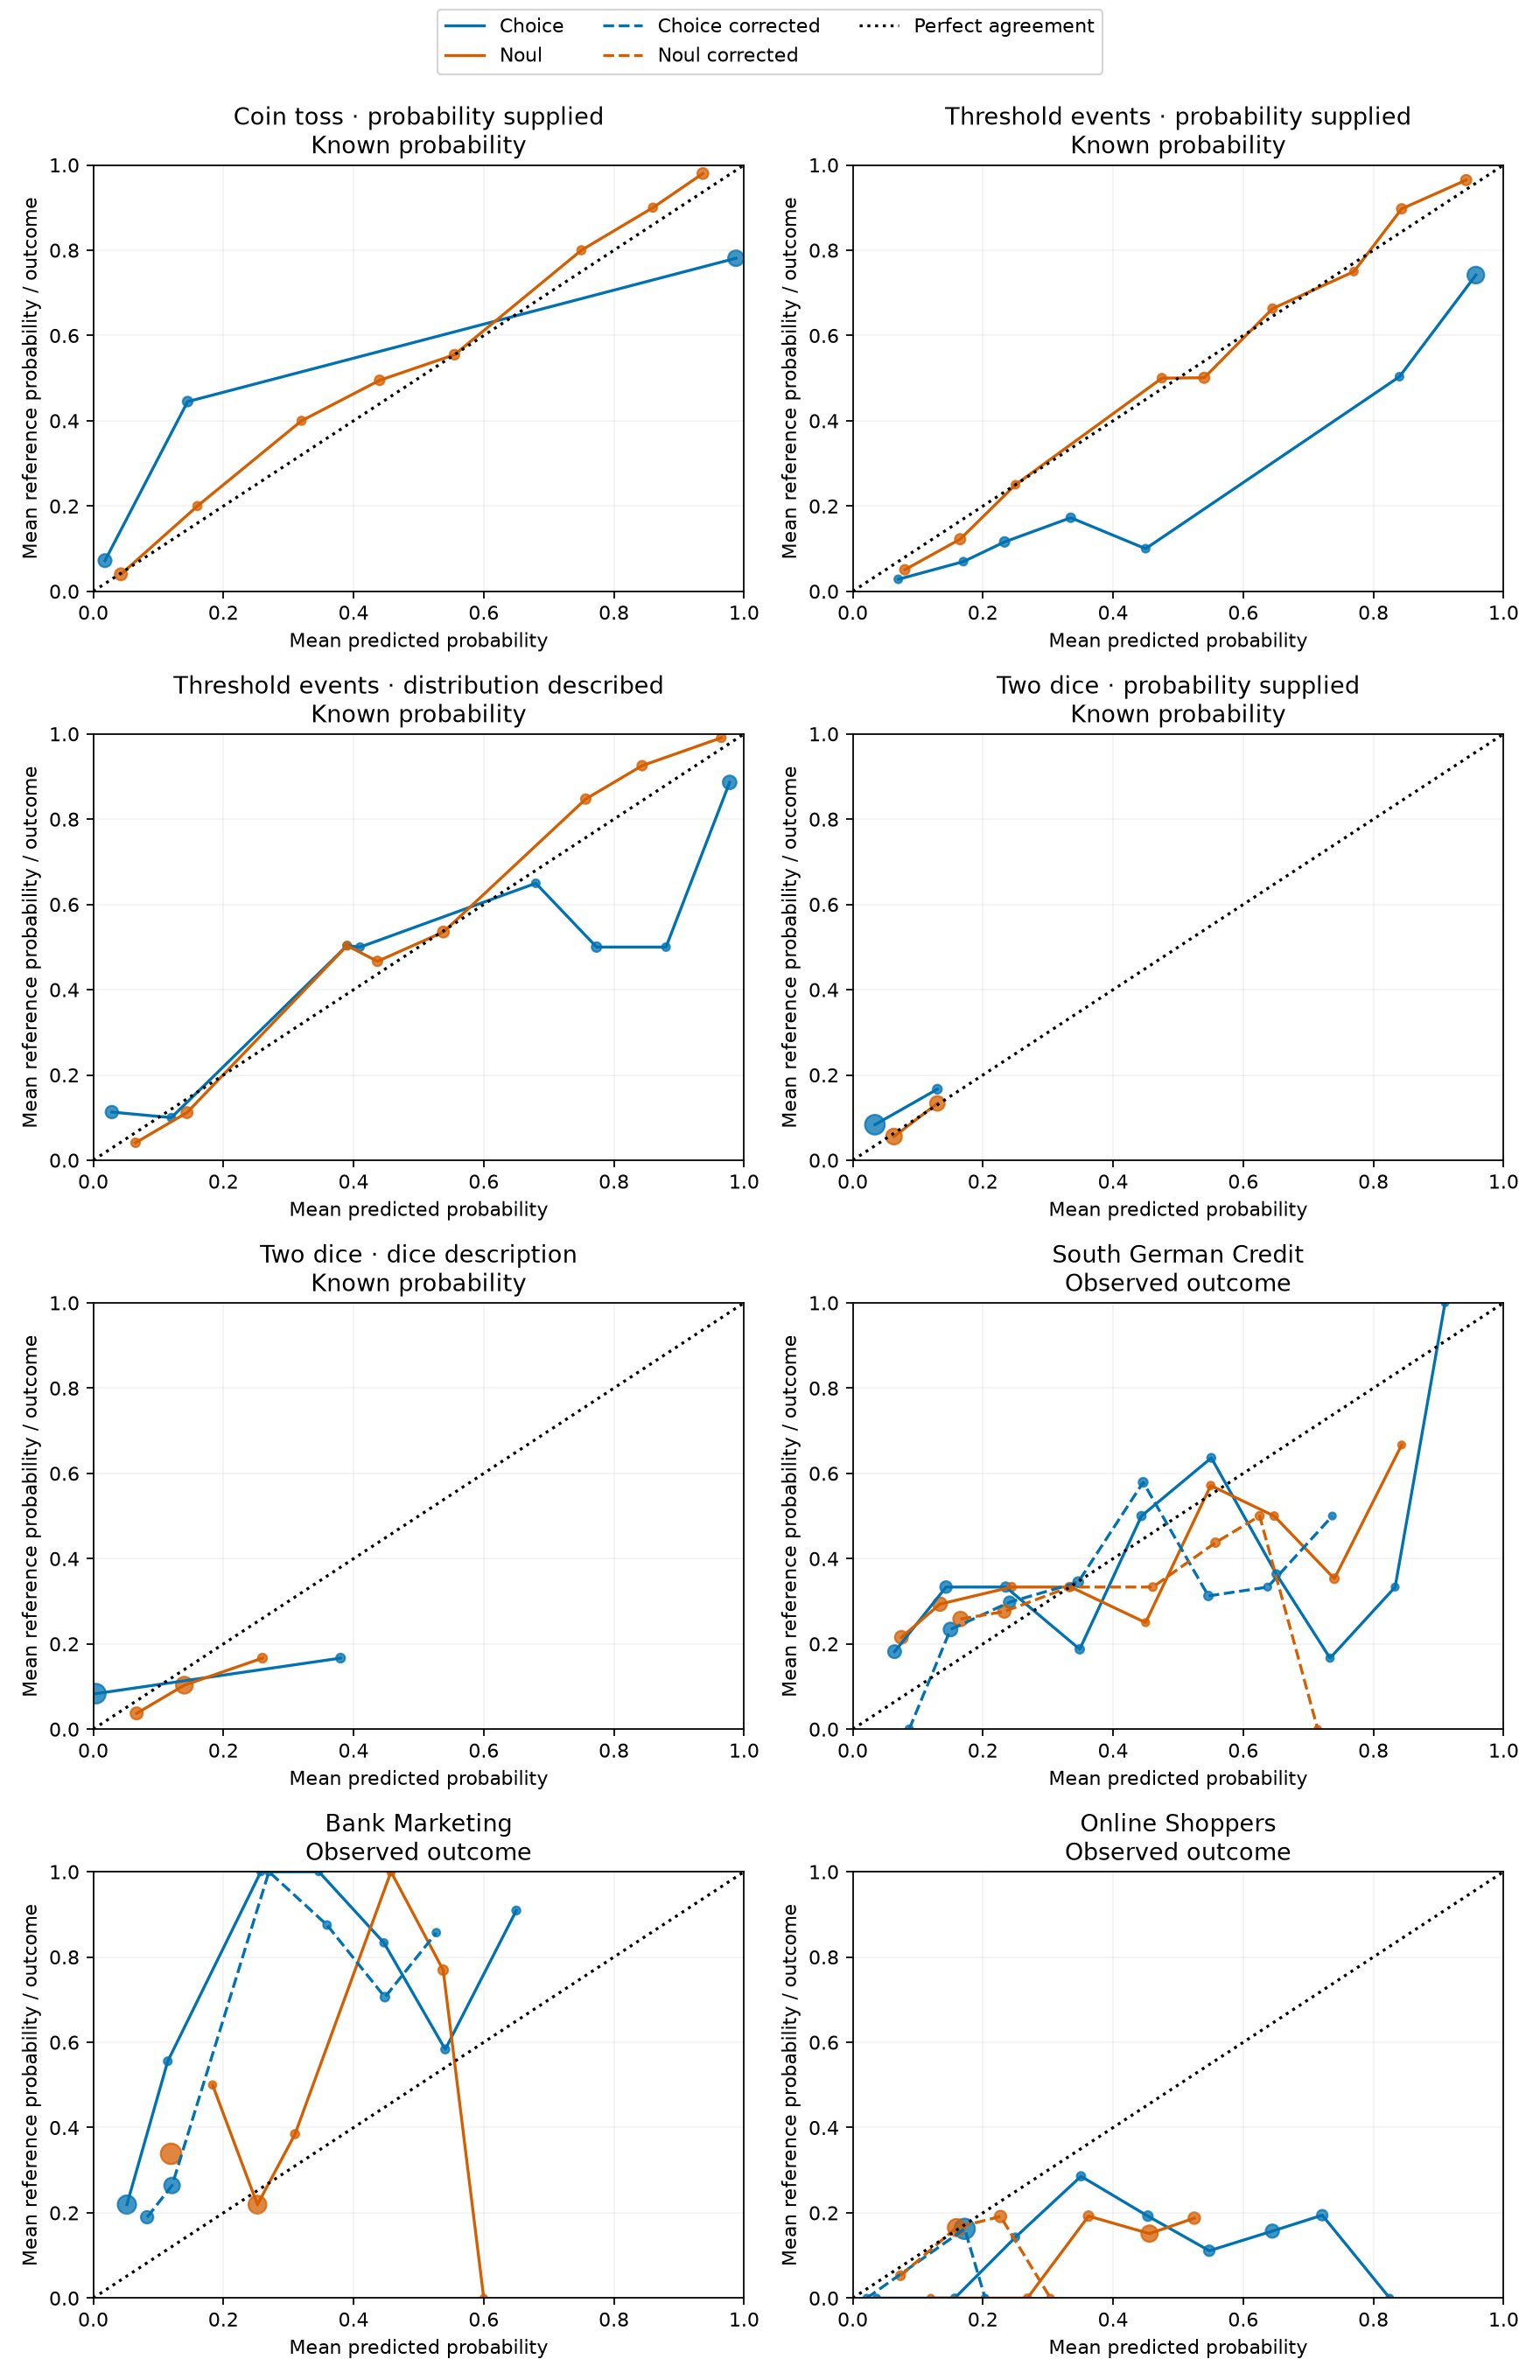
Jev looks interesting, but its differentiator, probability caliberation, is underwhelming. Structured outputs, latency, and cost can be replicated w/ off-the-shelf models. And I find it's biggest Aside from the 'System One' branding, Jev has 4 main promises: caliberated probabilities, structured outputs, low latency, and low cost. Cost and latency. Smaller LLM have similar cost and latency profile vs Jev. @ekzhang1 built a Jev-compatible API w/ Qwen-3.6-35b-a3b and SGLang doing 64 decisions/sec. https://x.com/ekzhang1/status/2100651678110515383. @mmastrac built it w/ DiffusionGemma and VLLM with similar latency vs Jev on DGX Spark. https://x.com/mmastrac/status/2100626204554592508?s=20. So, fast decision APIs are reproducible with existing models. Structured outputs. This is a capability trained into all autoregresive language models since 2023. Jev provides a similar abstractions to @deliprao 's AutoRubrics https://x.com/deliprao/status/2101732243848732895?s=20. Perhaps I am not applied or product minded enough, or i've been thinking too much about evaluations and alignments, the most useful application for Jev off the top of my head is as an LLM or search rubrics / preference model with its calibrated probabilities. But I am skeptical about its broad calibration claims, which it calls RLCD (calibrated decisions). What does it calibrate to? Calibrations is highly dependent on the known probability of the distribution q. @predict_addict ran 16.5k predictions across 8 datasets and found caliberation failures on 7/8. https://x.com/predict_addict/status/2101404670488875042. My own experiments (coin toss, 2 dice, 3 UCI datasets) shows that Jev has high expected caliberation errors (ECE). This is especially pronounced once we venture out of simulation based experiments. There is real product value here. @pdrmnvd runs poker arena https://x.com/pdrmnvd/status/2101470195428827493?s=20. @ShengyaoZhuang runs reranking with it https://x.com/ShengyaoZhuang/status/2101212268440723895?s=20. @BrainsAndTennis hooked Jev up to play Warcraft 3 https://x.com/BrainsAndTennis/status/2100998807903482364?s=20. And look at that damn Mountain King randomly jerking around. I suspect most of those capabilities come from Jev's base model, not from its RLCD. A durable advantage is consistently more reliable and calibrated probabilities, which translates directly into better decision paired with thresholds. It does not exist yet on Jev, and most capable teams should build from internal.
This post quotes another post: x.com/brainsandtennis/status/2100998807903482364