Gemini Argon vs GPT-6 Astra and Opus 5.5 on joke writing
The author tested frontier models on joke writing: Gemini Argon tried too hard, ChatGPT Astra was decent, and Claude Opus 5.5 spent ten minutes without good criteria.
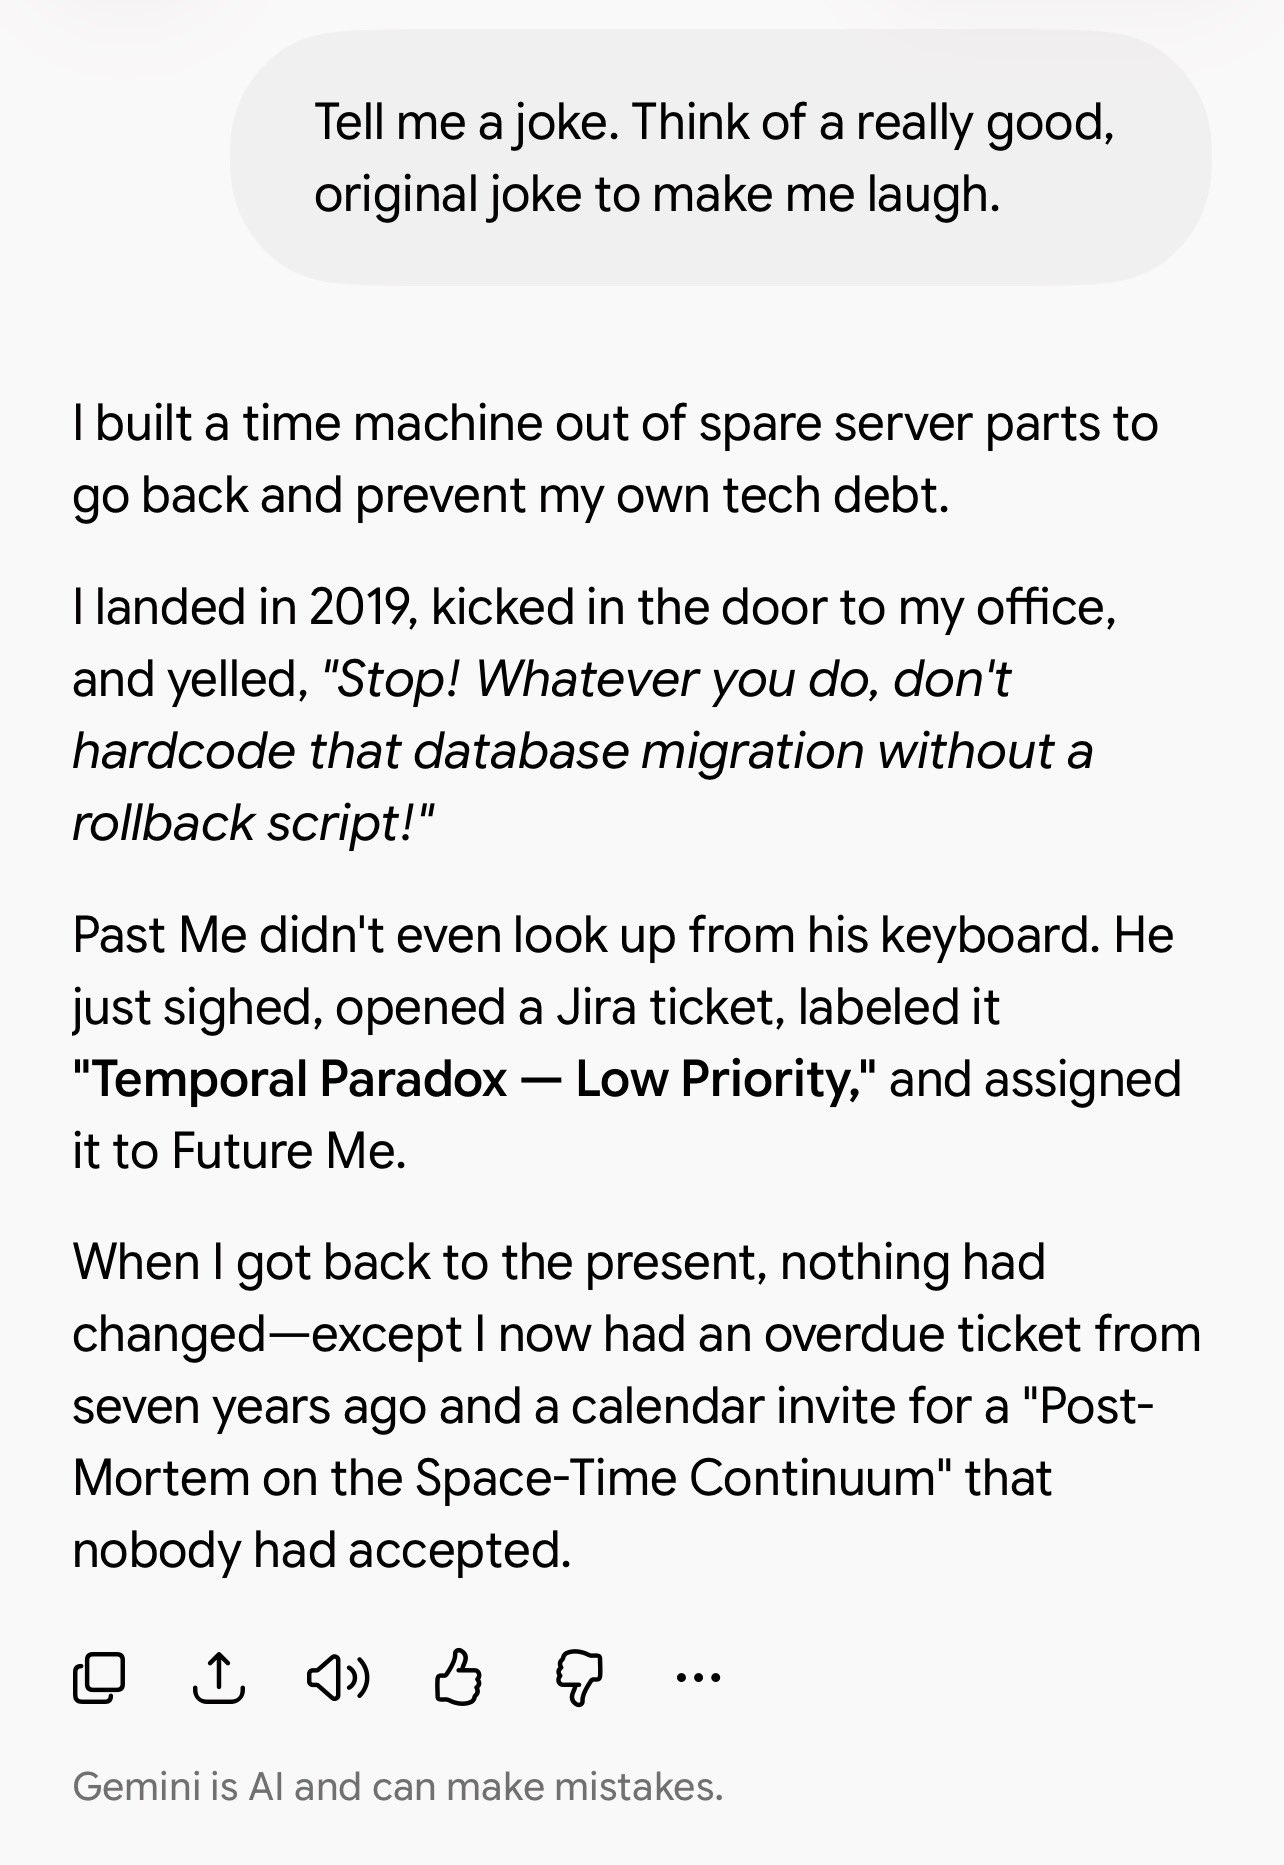
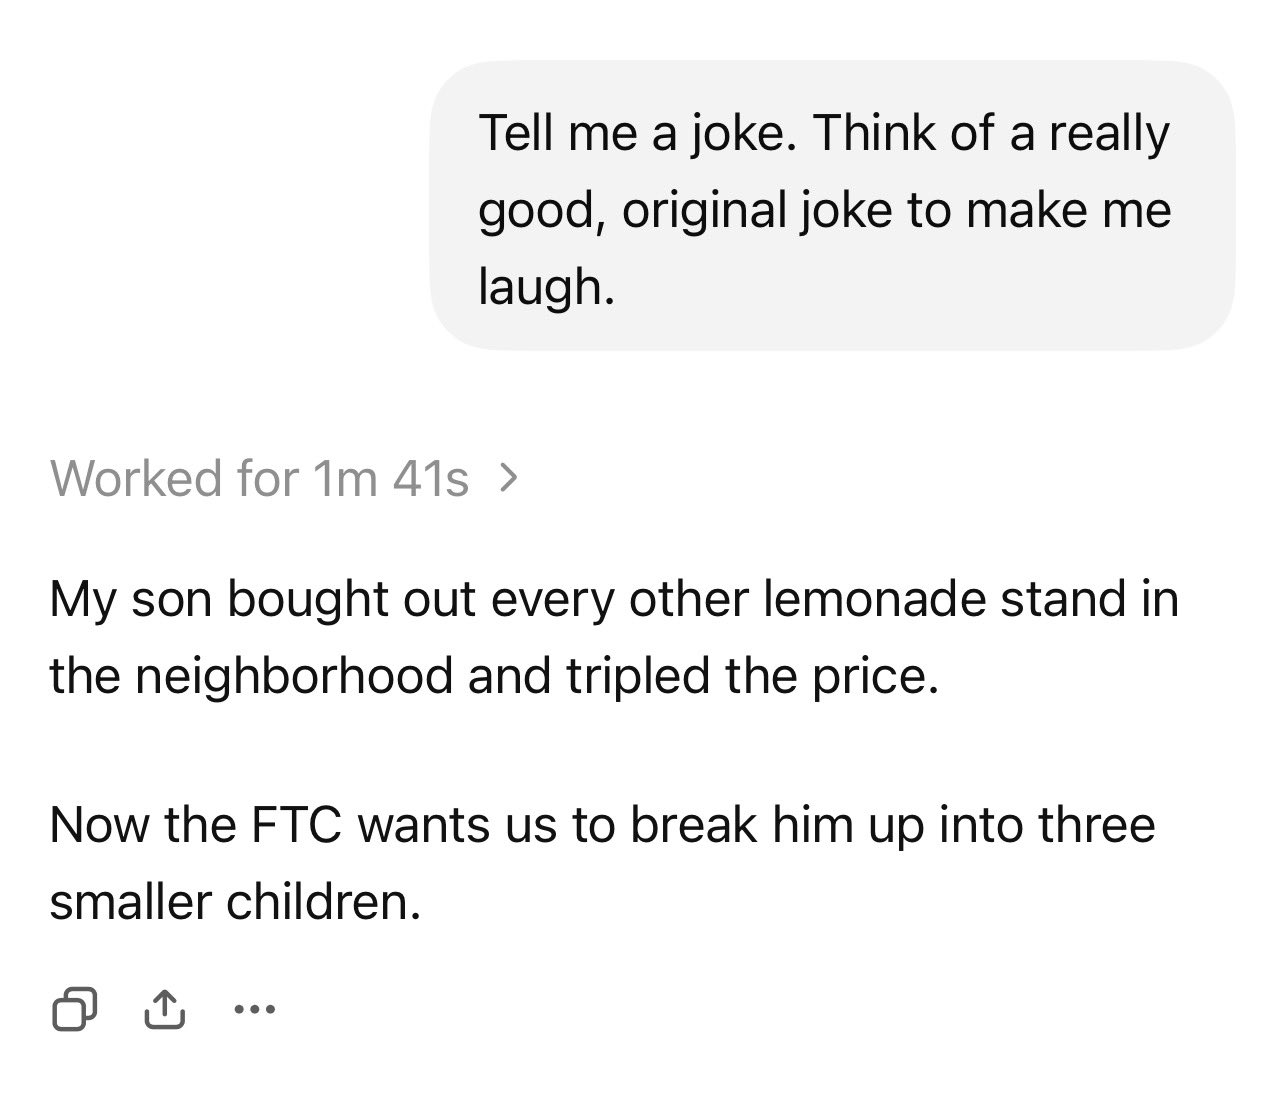
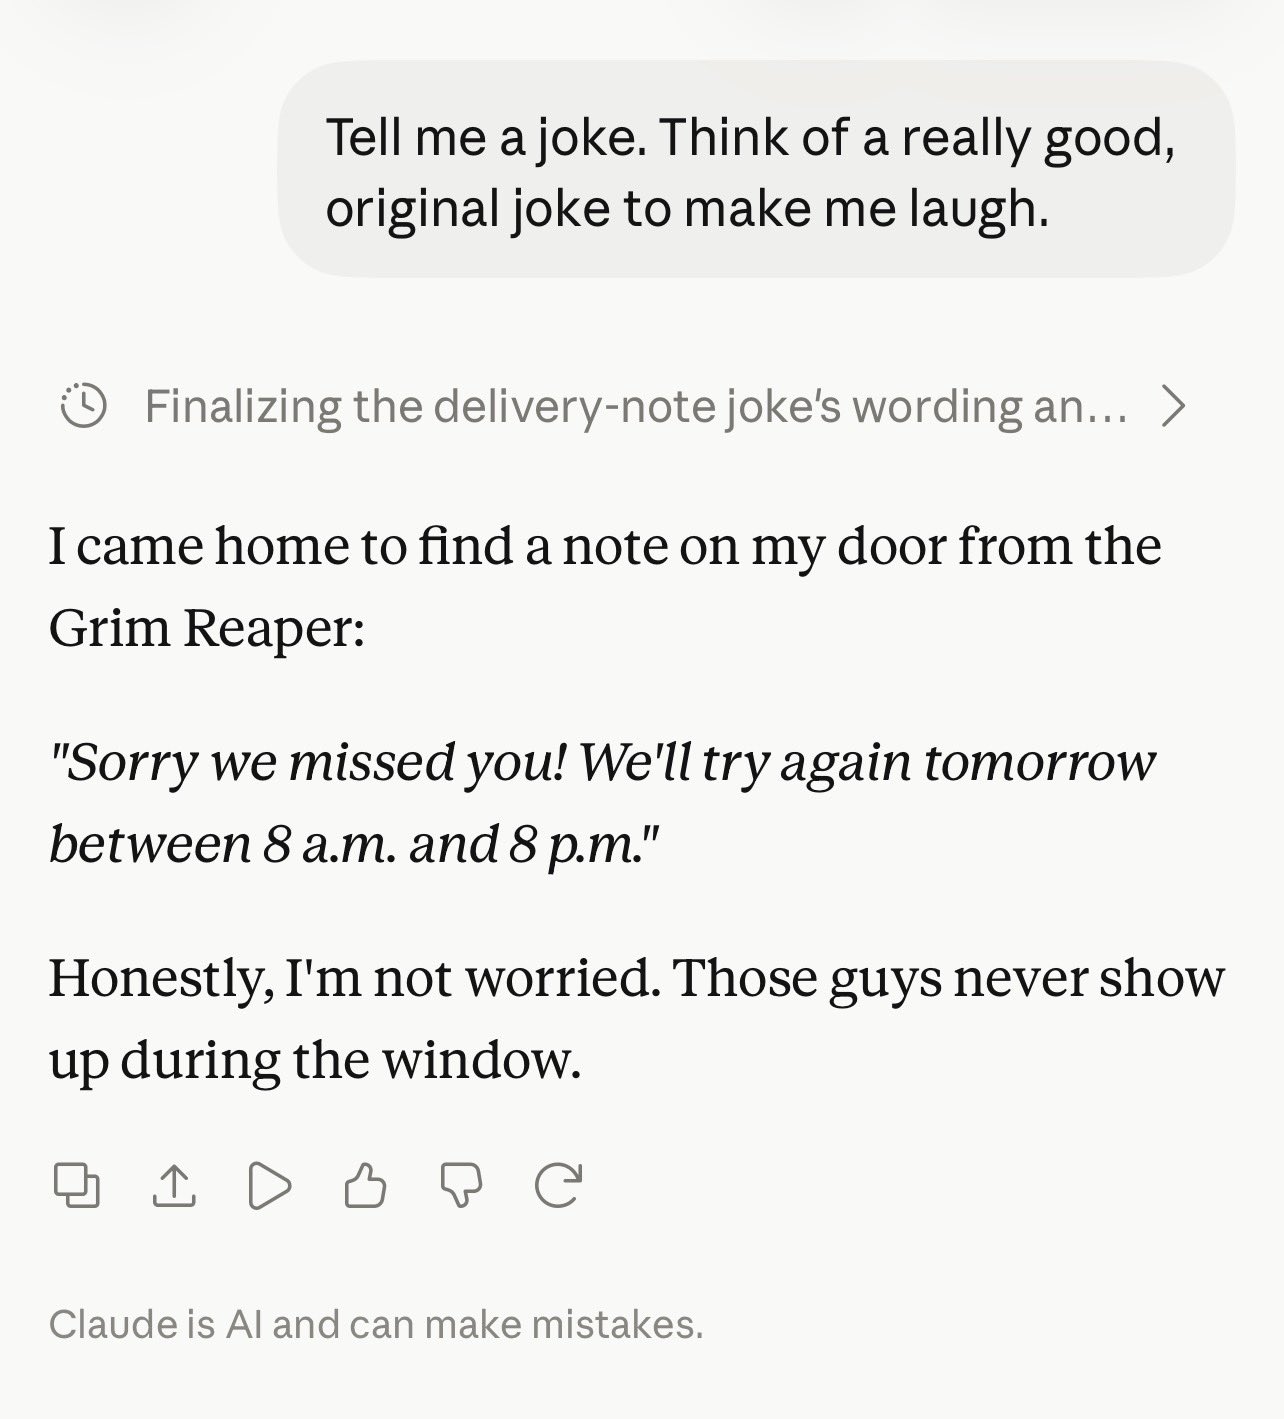
I decided to test the frontier models on the one thing they all fumble on: making a joke. So, first is Gemini Argon, which just looks like it tried too hard while not quite getting what a joke is. Second is ChatGPT Astra, and maybe it’s just low expectations, but its joke wasn’t half bad. And I was rooting for Claude Opus 5.5 — my favorite model to work with — and it spent 10 minutes on making a joke. I could see in its thought process it went through like a hundred different joke premises but I just kept thinking to myself, “By what criteria is it evaluating these?” And by the result, it didn’t have good criteria for that. My guess is if I saw all the jokes it came up with, a couple would have been funny, but it would have had no way to know.