DeepSeek reports ~$38 revenue per GPU-hour on its V4.1-Flash cluster
Alongside the DeepInfer release, a breakdown of DeepSeek's self-reported ~$38 revenue per GPU-hour versus $2–4 rental, attributing the 10–19x spread to speculative decoding, prefill cuts and in-house kernels.
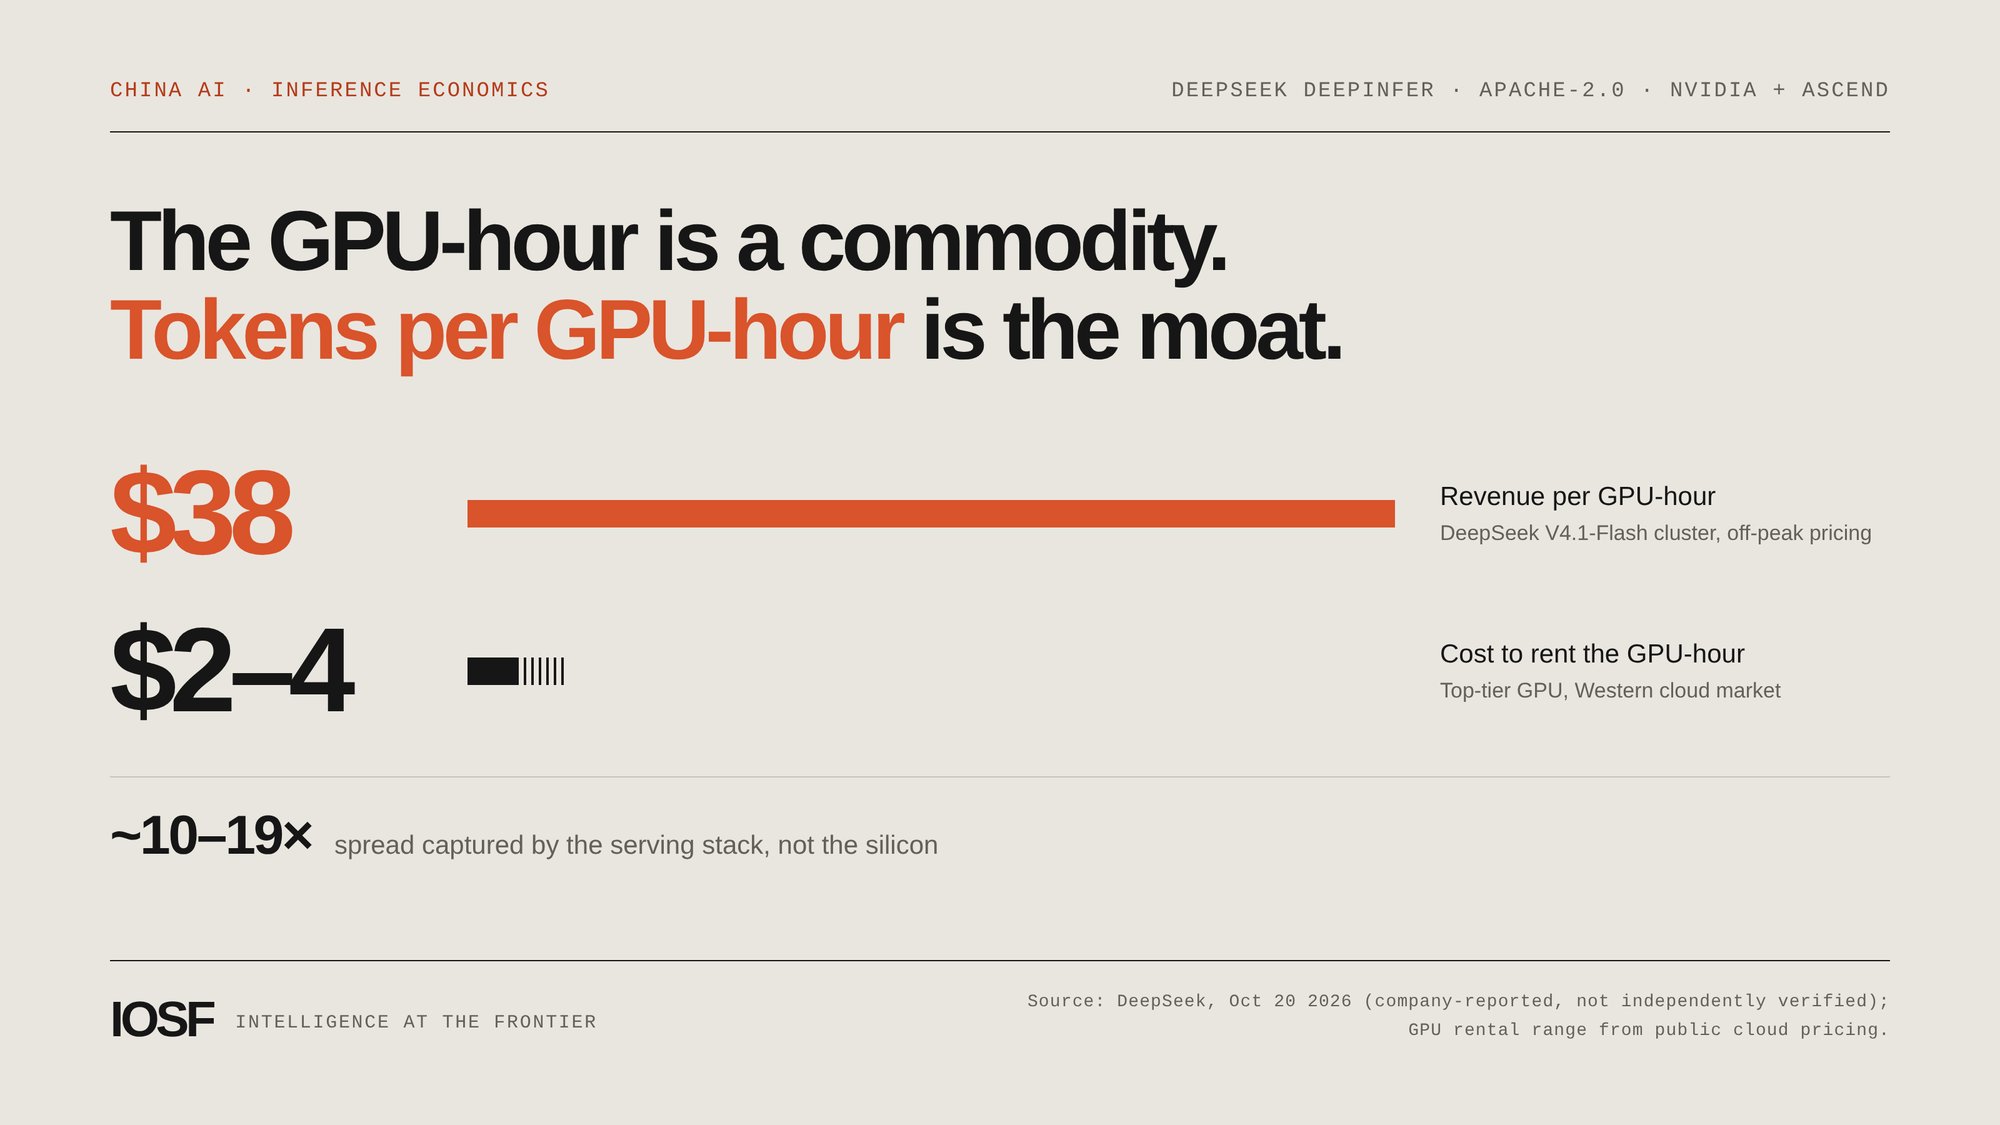
@deepseek_ai just disclosed ~$38 of revenue per GPU-hour on its V4.1-Flash cluster, at off-peak pricing. A top-tier GPU rents for ~$2–4/hr. That’s a 10–19x spread, and it comes from software, not silicon. The disclosure came with DeepInfer, the inference engine behind DeepSeek’s own production API, now open-sourced under Apache-2.0 with no revenue gate. One codebase runs on NVIDIA Blackwell or Huawei Ascend 950, and you switch between them with a single env var. Where the spread comes from: – Speculative decoding with a confidence head checks ~30% fewer draft tokens per step – A prefill technique cuts total prefill compute nearly in half – Built on vLLM and DeepSeek’s own kernels (FlashMLA, DeepGEMM, DeepEP) In inference, utilization is the product. What this means for compute investors: 1/ The GPU-hour is a commodity. Tokens per GPU-hour is the moat. Two operators renting identical hardware can run very different businesses. 2/ The margin sits in the serving layer, and DeepSeek knows it. KV cache management, prefill/decode disaggregation and load balancing were all kept out of the release. Open-sourcing the engine moves the hard part onto whoever deploys it. 3/ Hardware-agnostic serving loosens lock-in at the inference layer. If the same production engine runs on Ascend 950, non-NVIDIA silicon becomes a cost line, not a science project. Caveats: every figure here is DeepSeek-reported, the published benchmarks ran only on NVIDIA, and nobody has tested it independently yet. Outside estimates put inference gross margin around 80–95%, before R&D, networking and people.