Coding agent scores: Opus 5.5 at 61.7 leads Astra's 54.7
Artificial Analysis scores put Opus 5.5 at 61.7 versus GPT-6 Astra at 54.7 and Sol at 54.1, prompting the author to split grunt work to Sol and complex tasks to Opus.
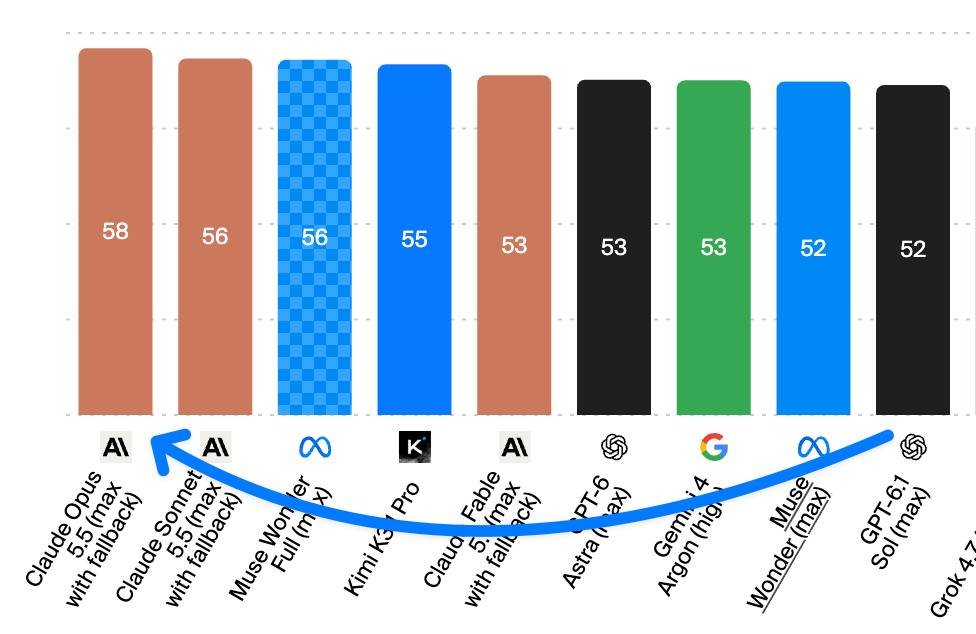
IF YOU DON’T BELIEVE OPUS 5.5 IS THE BEST CODING AGENT RIGHT NOW… LOOK AT THIS 💀 Artificial Analysis has Opus 5.5 at 61.7 👀 For comparison: Opus 5.5 → 61.7 ($11.42) GPT-6 Astra → 54.7 ($7.04) GPT-6.1 Sol → 54.1 ($1.50) But here’s the crazy part… Sol is almost at Astra’s level while costing a fraction of the price. So is Opus really worth paying ~7× more than Sol? Not always. I’d split the workload: Sol → grunt work PRs, issues, cleanup, repetitive tasks Opus 5.5 → serious work New features, complex bugs, deep/long tasks Why burn Opus tokens on boring work when Sol can handle it? 💀 Would you pay 7× more for Opus 5.5? 👀