DeepSeek V4.1 Flash on Strix Halo plus dual 7900 XTX: 41.3 decode and 1,291 prefill tok/s
On a roughly $6k Strix Halo plus two RX 7900 XTX setup tuned via Project Maya, DeepSeek V4.1 Flash 1017 reaches 41.3 decode and 1,291 prefill tok/s, with 8.3x faster prefill on a 130K prompt.
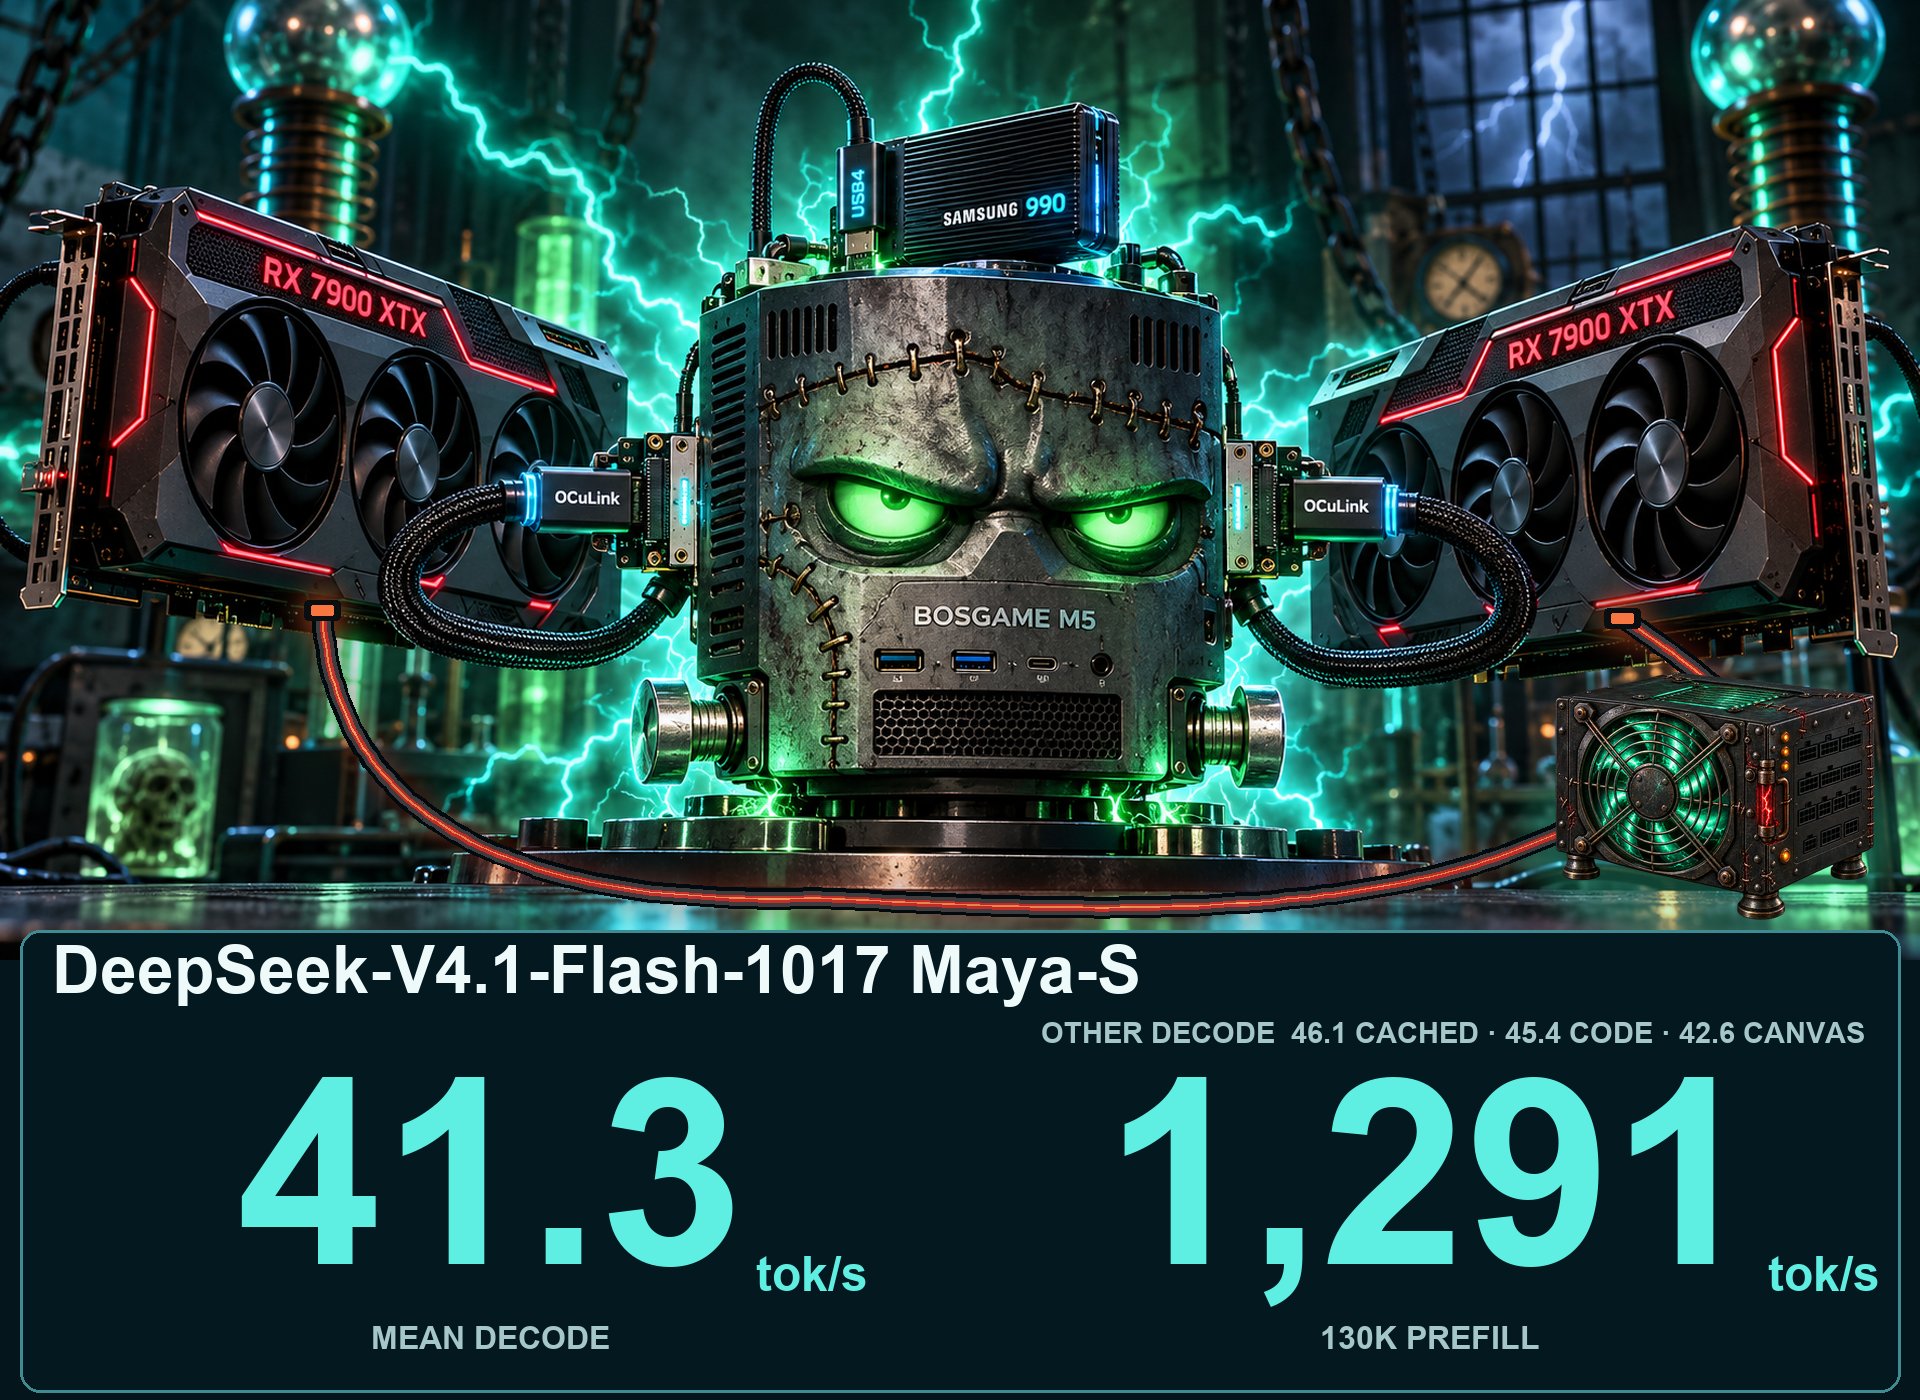
DeepSeek-V4.1-Flash-1017 Maya-S: 41.3 decode / 1,291 prefill tok/s. On a $6k setup: Strix Halo (Ryzen AI Max+ 395, 128 GB) + 2× RX 7900 XTX over PCIe 4.0 x4 OCuLink. Experts stream from a USB4 NVMe at 512K context. Software is no longer the bottleneck, we tuned project Maya for this weird HW: • fused decode stages + trimmed handoffs — fewer launches • pipelined FP16 all-reduce for prompts — less link traffic • 8060S helper for uneven tensor parallel groups — more experts in memory • hot-expert reuse + shared, sharded disk reads — fewer USB4 reads • long-prompt skip + borrowed VRAM slots — faster prefill • recent-expert cache, CPU-lane tuning + drafter VRAM caps — faster decode On the same 130K prompt, prefill went from 155.4 to 1,291 tok/s: 8.3×, even with 512K context now versus 128K before. Mean decode on Maya's benchmark at 512K rose from 37.2 to 41.3 tok/s: +11%. Results and nine PRs: https://github.com/mw00/project-maya/issues/510 Reproducible Ansible release: https://github.com/pepuscz/strix-halo-llm Thanks @PeasantSmith for Project Maya and @coldniko for Strata. Both made this possible.