gpt-6IMAGE
Four frontier models ranked on the same design review tasks
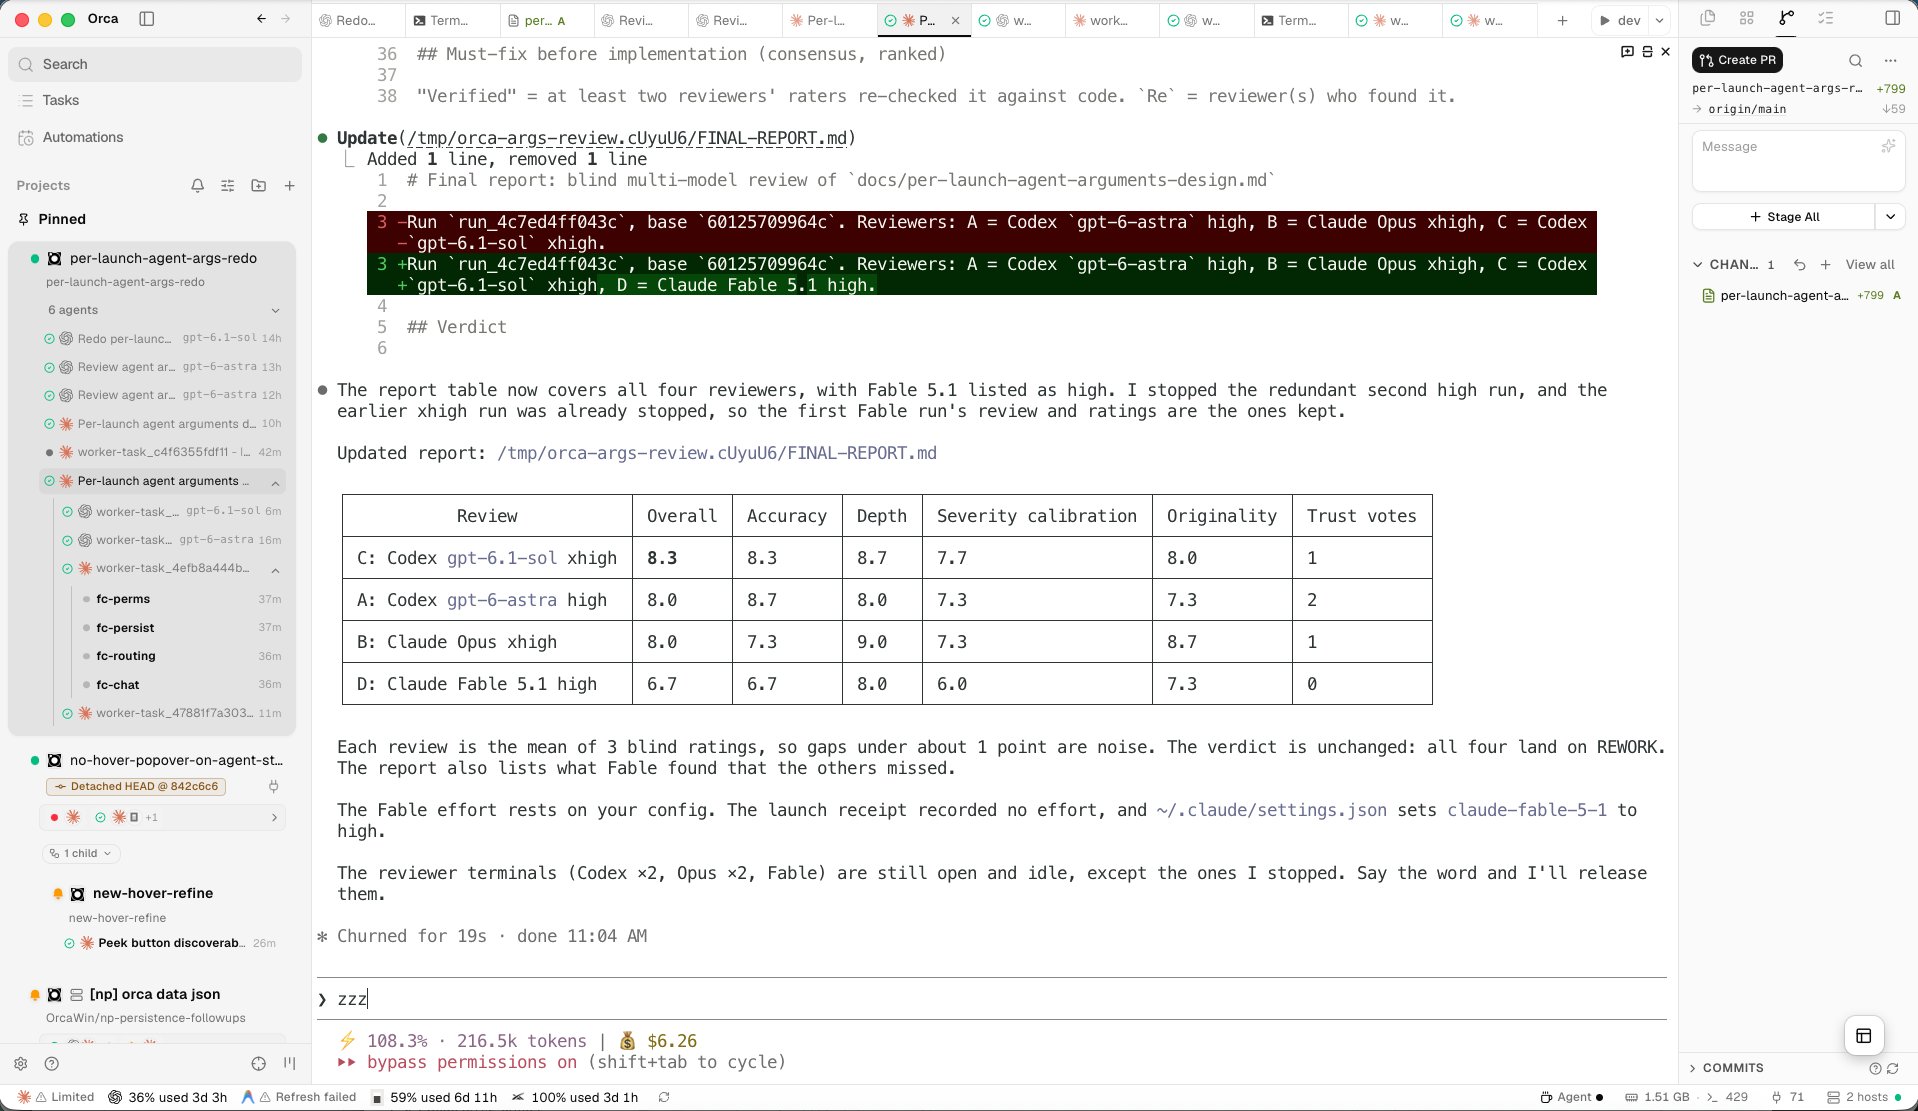
The author used an LLM Council to have four models perform the same design review, with GPT-6.1-sol placing first and GPT-6-astra second, both ahead of Opus and Fable.
jinjingliang
@JinjingLiangArchived 27 days agoOriginally posted 2026.10.07
jinjingliang @JinjingLiangOriginally posted 2026.10.07
I gave 4 frontier models the exact same design review tasks—here’s how they ranked: 1. GPT-6.1-sol xhigh (Codex) 2. GPT-6-astra high (Codex) 3. Opus xhigh (Claude Code) 4. Fable 5.1 high (Claude Code) How it works: I built an LLM Council using @orca_build's built-in orchestrator. A Sonnet 5 President agent triggers council members to run their own reviews, has them rate each other's work (blind), and aggregates the final votes. I’ve seen this consistently across multiple council runs—GPT models just do a better job with research & design tasks.
x.com/jinjingliang/status/2107537480945942954Archived 2026.10.07 10:10