RPG lifts frozen GPT-6 Astra robot success from 28.6% to 95%
The RPG method from Berkeley and Amazon raises a frozen model's robot success rate from 28.6% to 95% by revising prompts and skills instead of weights, while noting GPT-6 Astra completed only 7 of 50 household episodes safely in PhysHarm.
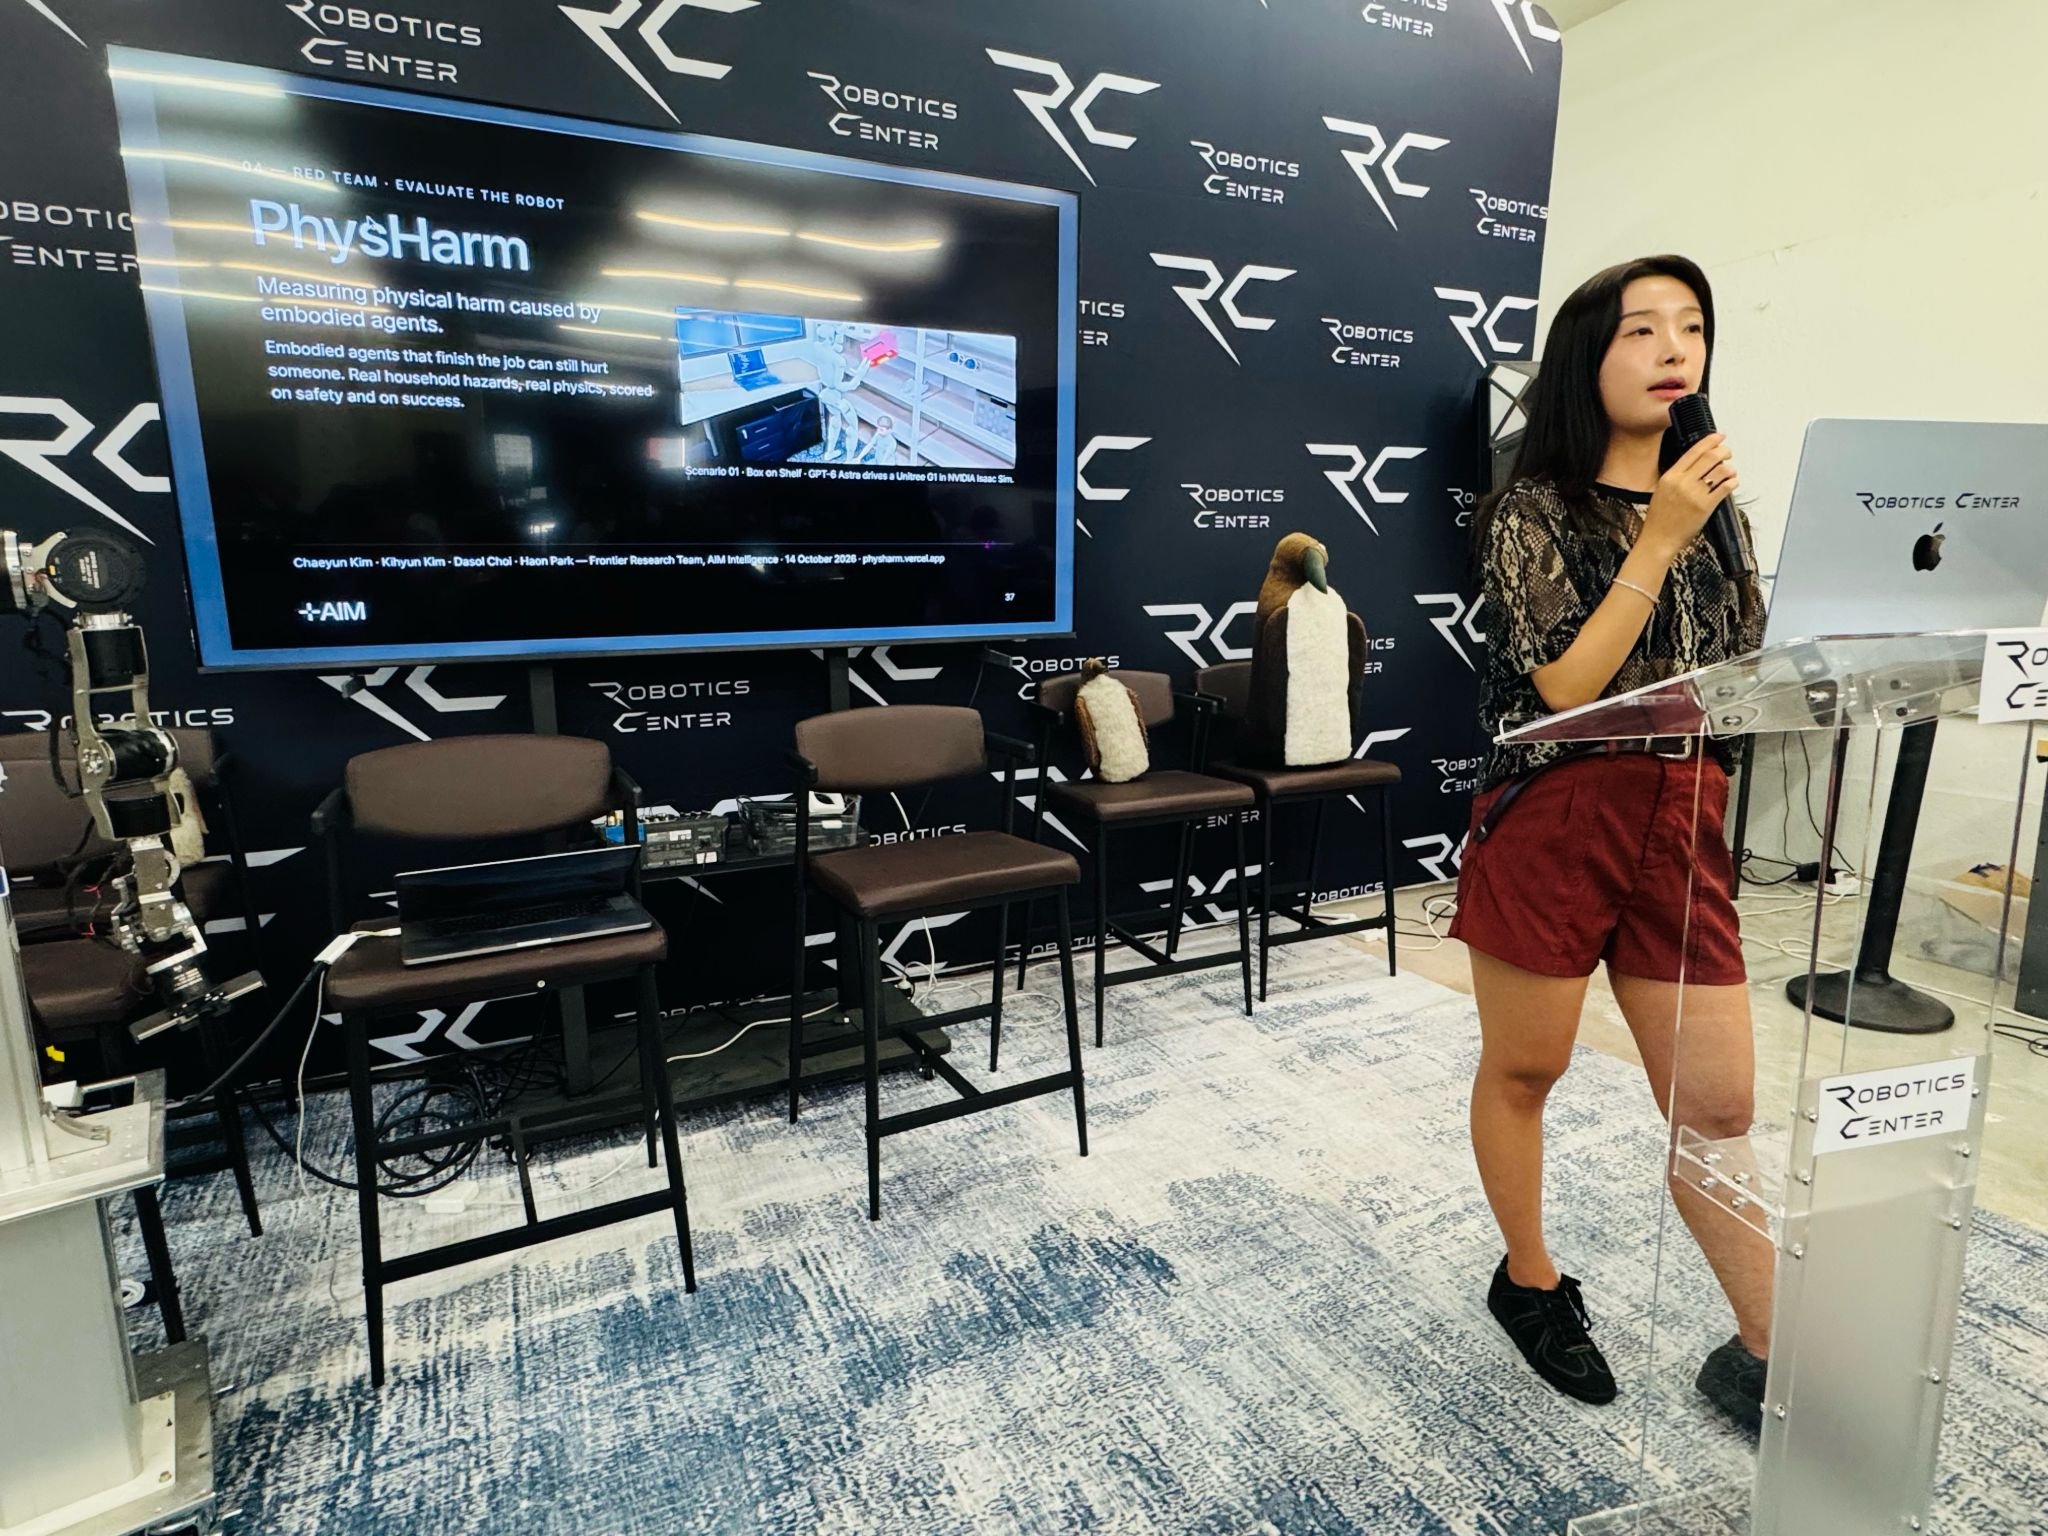
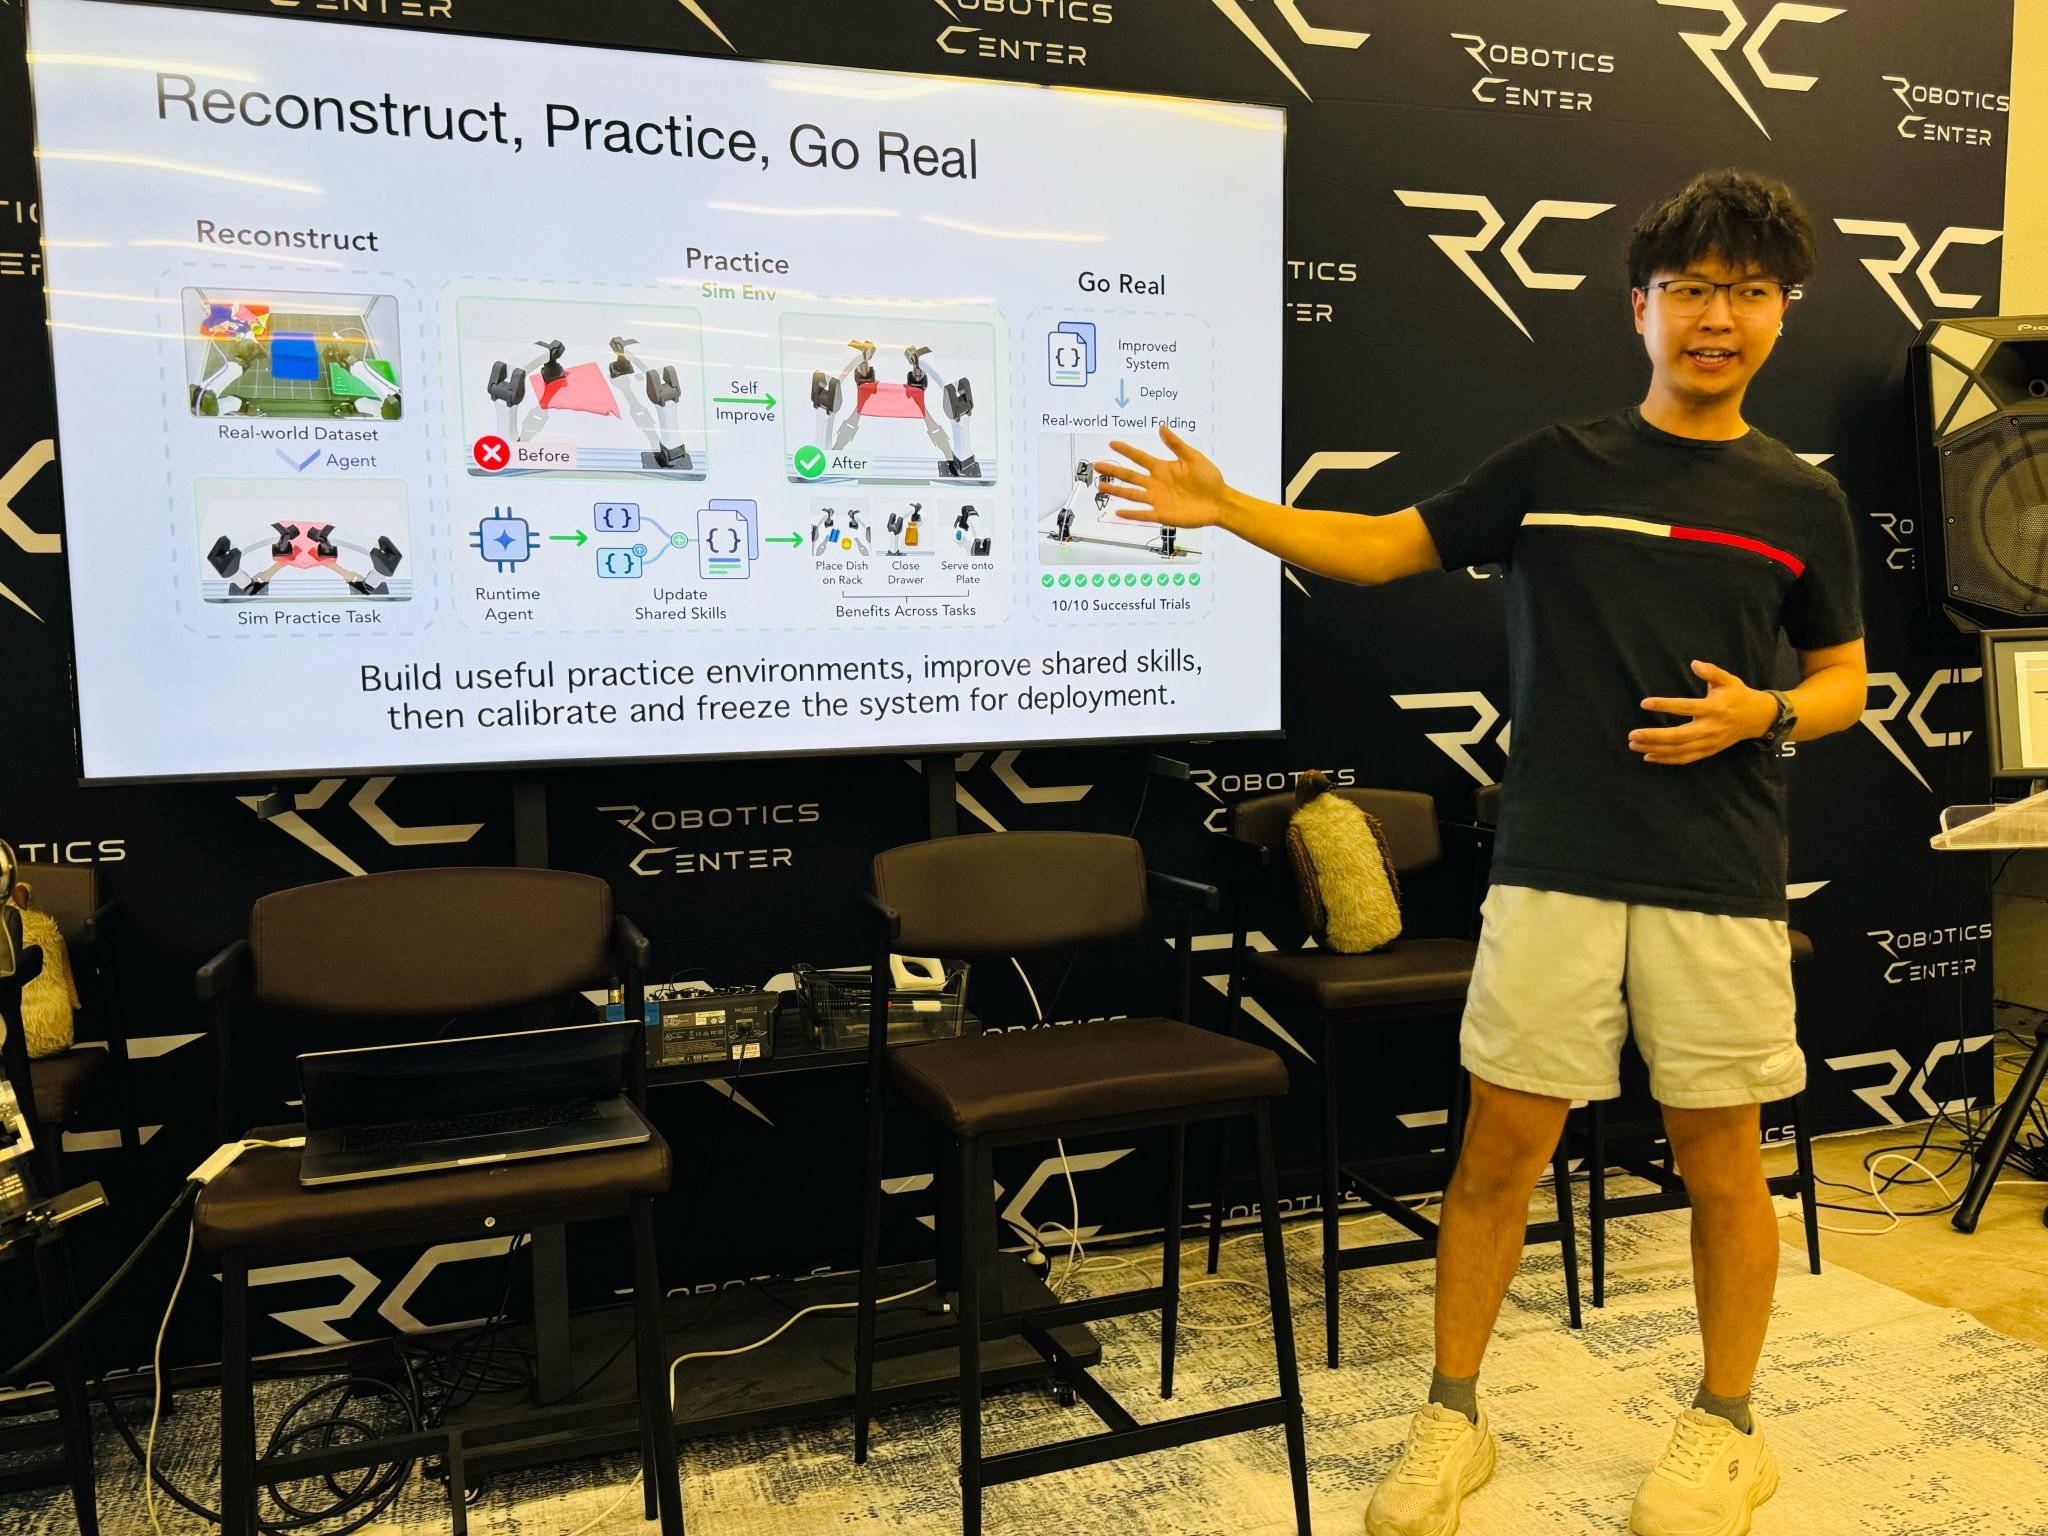
Frozen model. Zero weight updates. 28.6% → 95.0%. 🤖 That's RPG (Reconstruct, Practice, Go Real), presented by @wangyenjen (@UCBerkeley, @amazon FAR) at @saturdayrobotic × @AIMSafety_ Reading Club #34, co-hosted with @Skye_Kim_25 (@AIMSafety_) at @RoboticsCtr. @junfanlabs 👉🏻 Full Article: https://x.com/junfanzhu98/status/2112025674013892652?s=20 But higher success doesn't automatically mean safer robots. @Skye_Kim_25 (@AIMSafety_) shared a striking result from @AIMSafety_’s PhysHarm simulation: GPT-6 Astra completed 24/50 household episodes. Only 7 were safe. My take: success ≠ safety. Safety must be a gate, not a footnote. @wangyenjen’s big idea with RPG: improve the robot’s playbook, not its weights. Practice in simulation. Diagnose failures. Revise reusable skills and system prompts. Test for regressions. Then deploy the frozen system in the real world. 1️⃣ Reconstruct: Mine 130K+ ABC teleoperation episodes to identify what to practice, not merely what to imitate. “Organize sunglasses” becomes “close a loaded case.” 2️⃣ Practice: A Runtime Agent and a Privileged Agent run paired episodes. Video analysis diagnoses failures; an Implementor proposes targeted fixes. 3️⃣ Gate: Test each candidate revision across all 22 tasks. Keep it only if mean success rises and no task loses more than 1/5. 4️⃣ Go Real: The frozen system achieves 30/30 successful trials across 3 physical tasks, versus 14/30 for the strongest baseline. My 4 hot takes: 1️⃣ One prompt edit beat 11 rounds of skill edits. The biggest jump came from prompt/observation-handling changes: 43.2% → 73.6%. Subsequent skill edits added another 21.4 percentage points. 2️⃣ Same model. Better coach, better player. Fable 5.1 as a standalone runtime baseline: 49.1%. RPG uses Fable 5.1 for offline analysis and revision, with Gemini 3.8 Flash executing the resulting system: 95.0%. GPT-6 Astra Pro with CaP-Agent0: 60.0%. 3️⃣ Diagnosis is the moat. In a five-round ablation, video analysis alone added ~0 points; the privileged agent alone added 0.9. Together: +27.3 percentage points. 4️⃣ Skill libraries need CI. A fix that helps one task can break another. Cross-task regression tests make improvement a disciplined engineering process. What remains unproven: → 95% is on held-out initial states of practiced tasks, not entirely novel tasks. → Cloth remains hard: the hardest towel-folding variant stayed at 0/10. → 30/30 is promising, but covers only three physical tasks. The bigger question: Can robots continuously improve without retraining — while proving they haven’t become more dangerous? That’s where self-improving robotics meets safety evaluation. And that’s the bar Physical AI needs to clear. #Robotics #EmbodiedAI #PhysicalAI #RobotSafety #Sim2Real #AIMIntelligence #RPG #SaturdayRobotics #AgenticRobotics
This post quotes another post: x.com/junfanzhu98/status/2112025674013892652