Jev vs OpenAI Decisions API on chatbot intent routing
The author reran the same 30 intent-routing messages against Jev and OpenAI's new Decisions API; Jev scored 30/30 at 0.24s with stable confidence, while Decisions was faster but misrouted one message and triggered more clarifying questions.
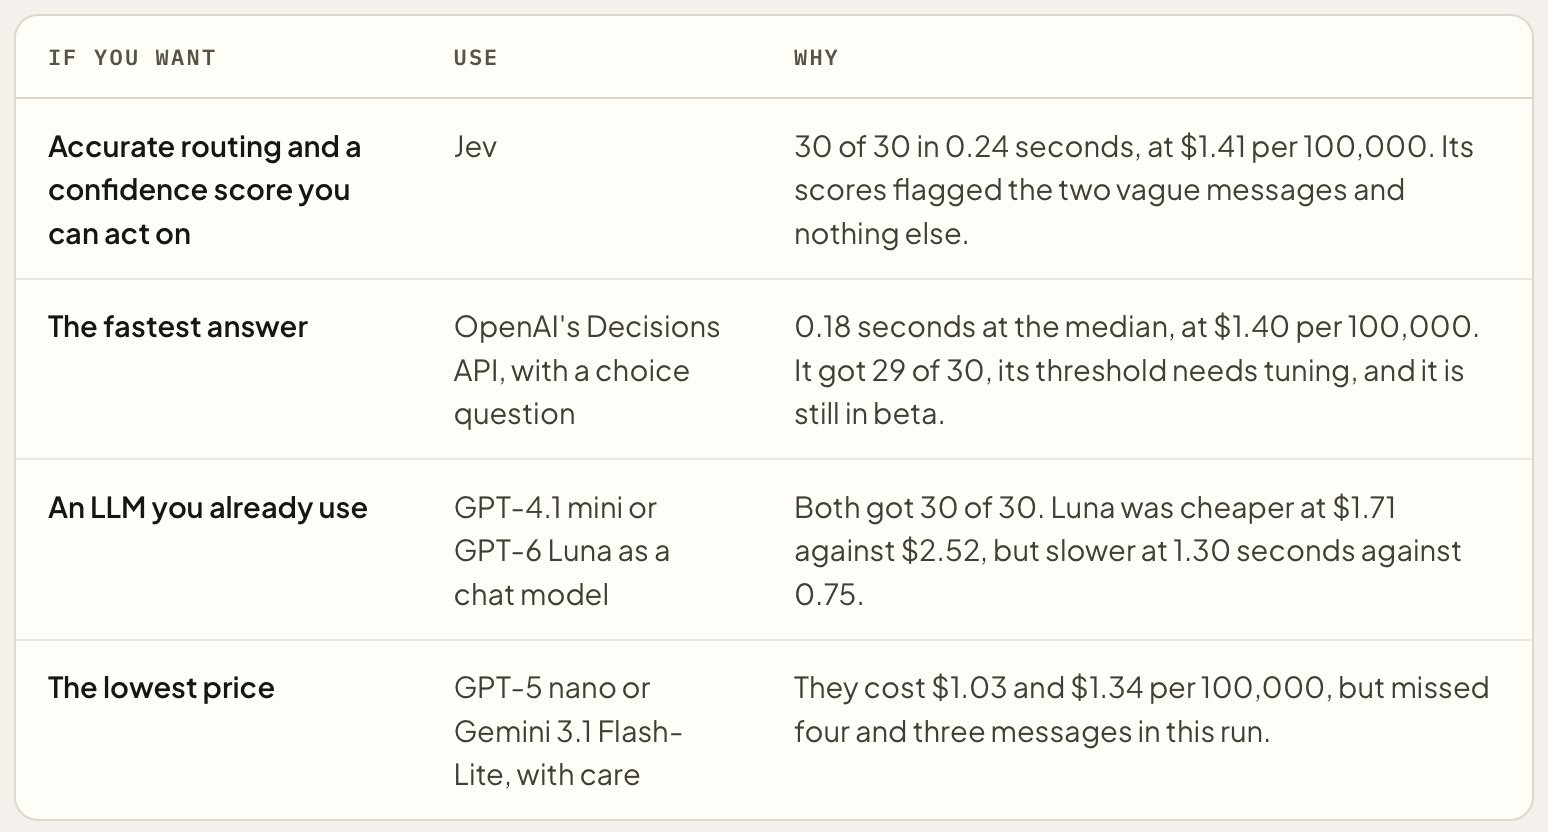
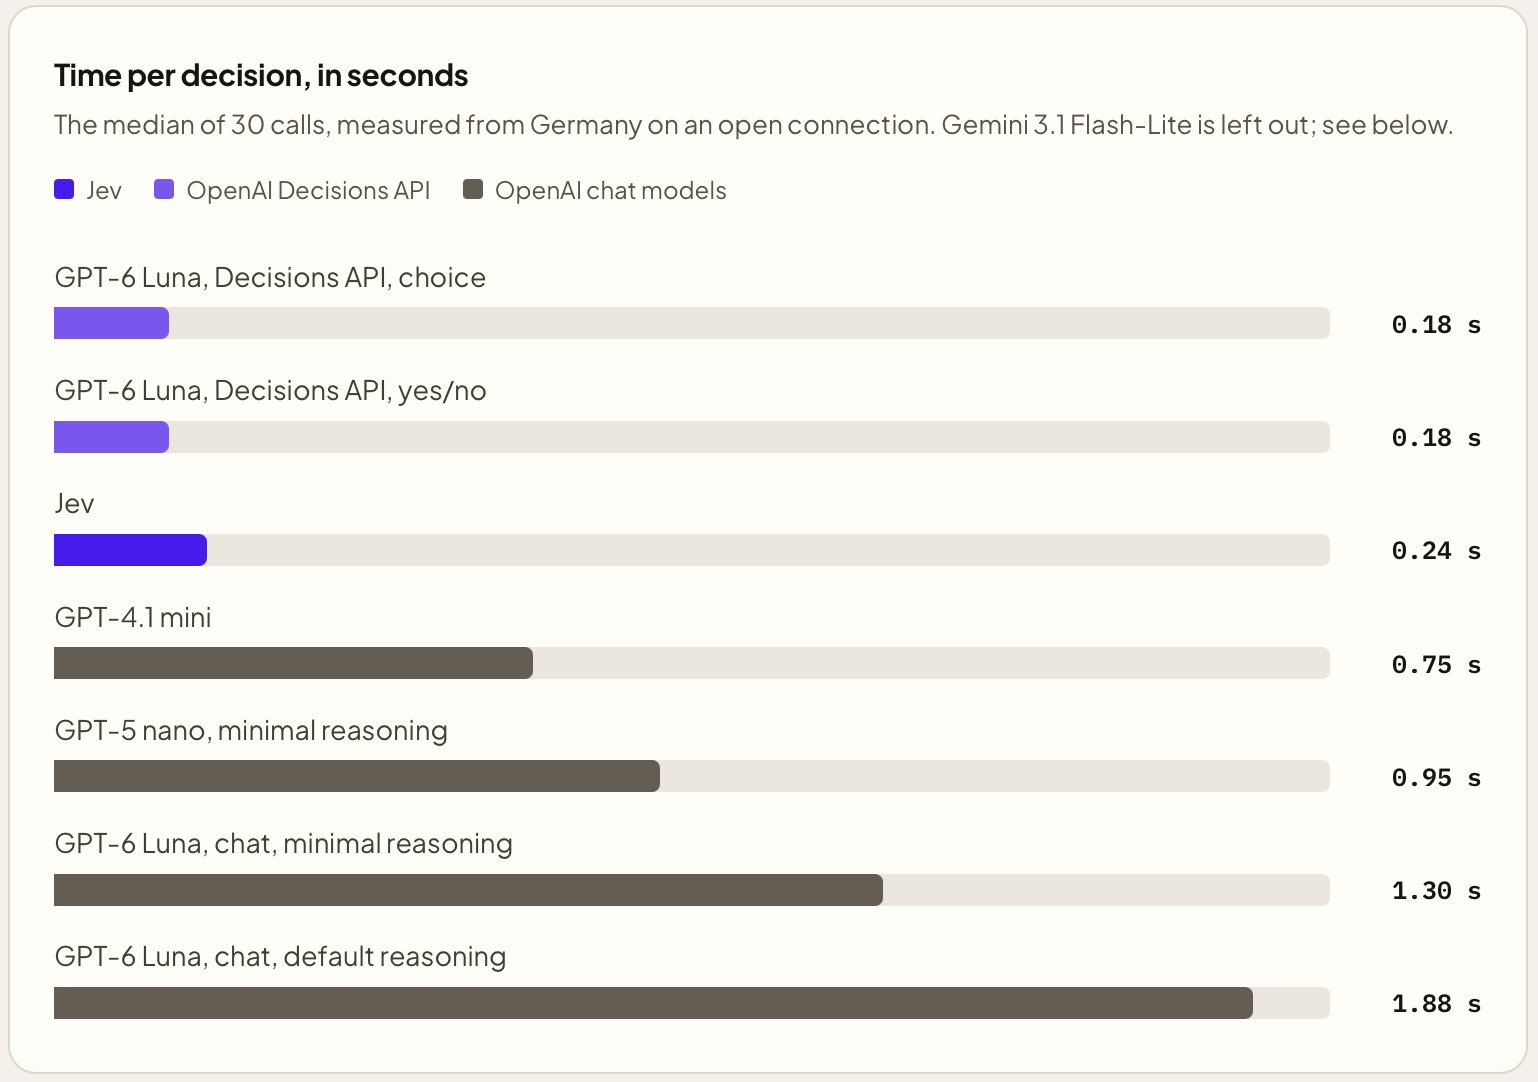
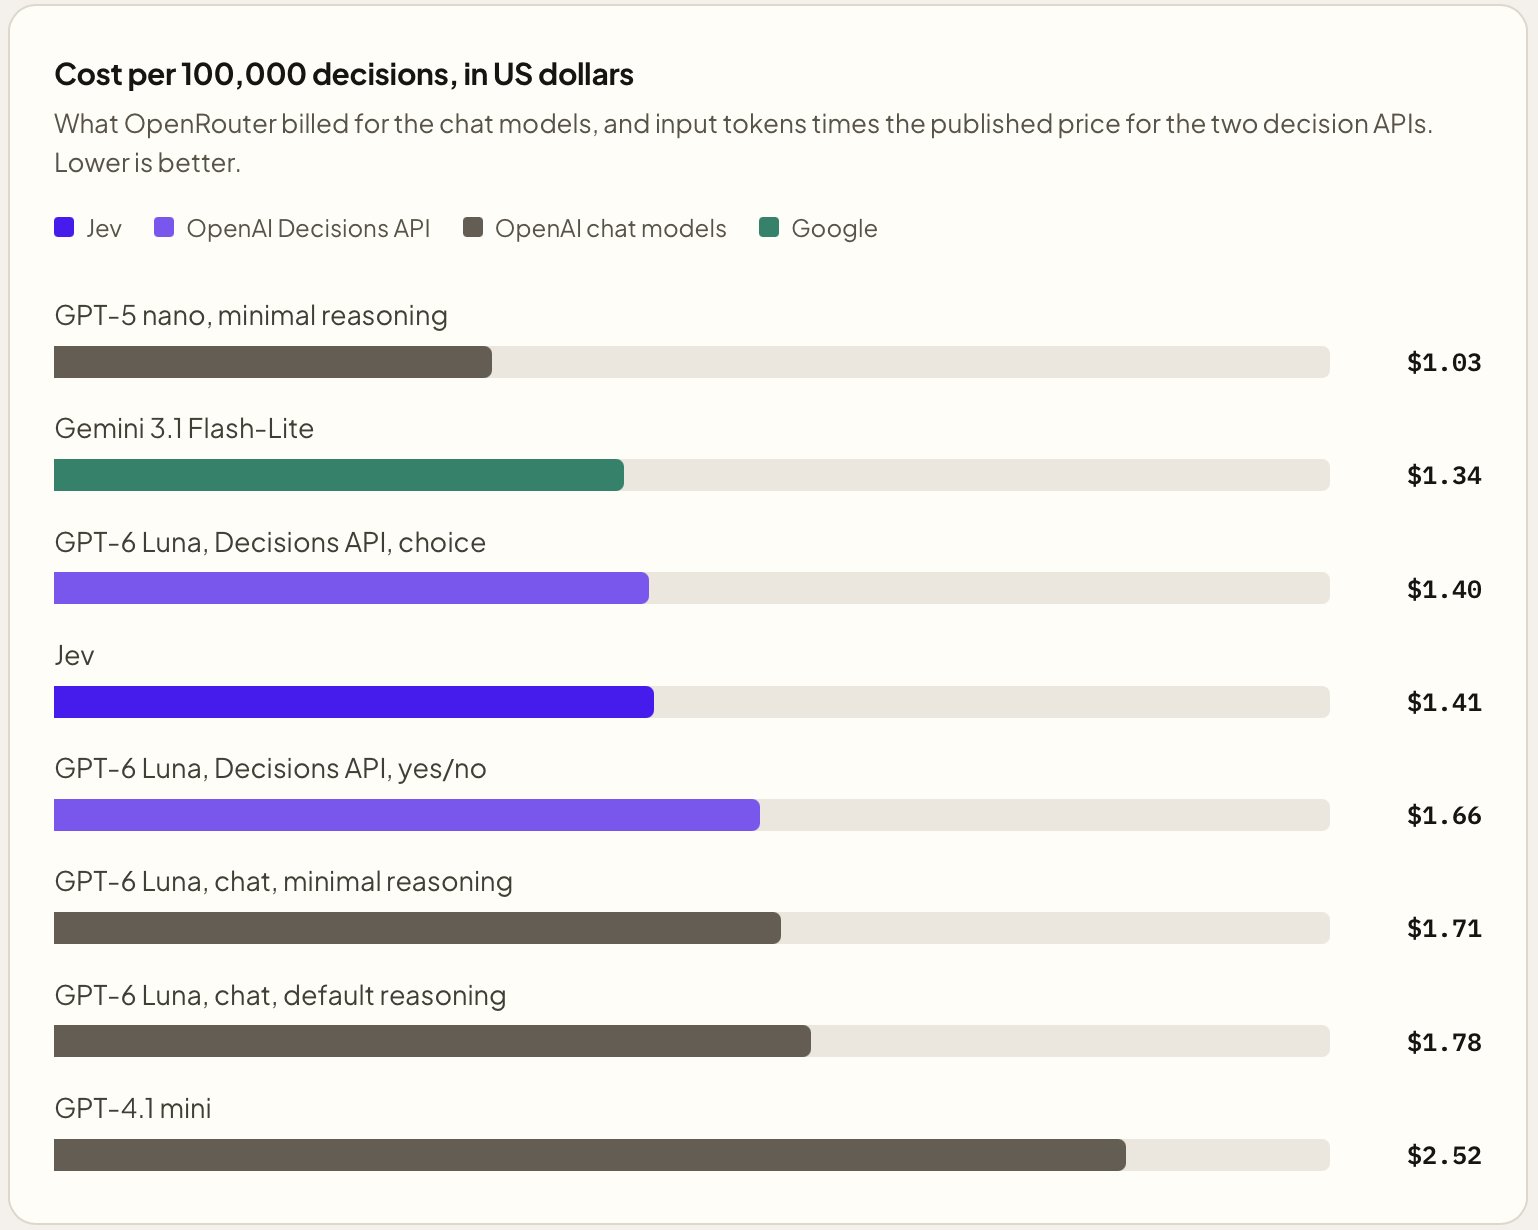
OpenAI's new Decisions API is the fastest thing I've measured on my chatbot's routing step. It's still not my pick. Last month I tested Jev against six LLMs on @ChatFrom_io 's intent routing. When OpenAI shipped Decisions this week, I ran the exact same 30 messages again. 12 clear refund requests, 12 clear support requests, 6 vague ones like "I want to cancel". Here's how it went: Jev: 30/30, 0.24s, $1.41 per 100k decisions Decisions API: 29/30, 0.18s, $1.40 GPT-4.1 mini: 30/30, 0.75s, $2.52 GPT-6 Luna (chat): 30/30, 1.30s, $1.71 - Speed Both decision APIs were 3 to 10x faster than the chat models. Decisions won the median, but Jev was way more consistent. Its slowest calls took 0.27s. Decisions' slowest took 0.90s. - Cost Basically a tie, for a funny reason. Both bill the question template as input. Decisions counted ~140 tokens per decision at $0.10/M. Jev counted ~334 at $0.042/M. More tokens vs a higher price, same bill. About $14 per million decisions vs ~$25 for GPT-4.1 mini. - Confidence I route anything under 0.8 to a clarifying question. Jev scored every clear message 0.98+ and only the two vague ones fell below. Decisions scores lower across the board. At 0.8 it would've asked the visitor 4 times, including for a plain "hello". Its one mistake, "I want to cancel" sent to refund, came in at 0.74. So 0.8 catches it, 0.7 lets it through. Lesson: don't copy a threshold from one model to another. How you ask changes the answer I also tried it as a yes/no question. Worse. 28/30, a 0.51 coin toss on one vague message, and it refused to answer "hello". Use a choice question, and treat refusals as "unsure". One weird thing is, GPT-5 nano went from 30/30 in September to 26/30 this time. Same prompt, same settings. One run isn't enough to trust anything. How to test a decision model on your own bot (bookmark this): 1. Pull ~30 real messages, include the vague ones, and label the branch you'd pick 2. Ask every model the same question, using the parser your workflow actually uses 3. Make one warm-up call, then time the rest. Look at the slowest 5%, not just the median 4. Price it per decision from billed input tokens, because templates count 5. Log confidence on every answer and set a threshold per model. Below it, ask the visitor 6. Try choice vs yes/no wording on your vague messages 7. Save it as a script and rerun whenever a model or price changes My pick for ChatFrom: Jev stays the default. Decisions is a close second, and I'll retest when it leaves beta. Full write-up with all 8 settings and the confidence table in the first reply 👇