Kaggle launches Human Behavior Bench: Gemini 4 Argon places second
Kaggle and RunRehearsals released a public benchmark for predicting real human behavior; Gemini 4 Argon scored 80.6%, second behind Engram 1.0 at 94.1%.
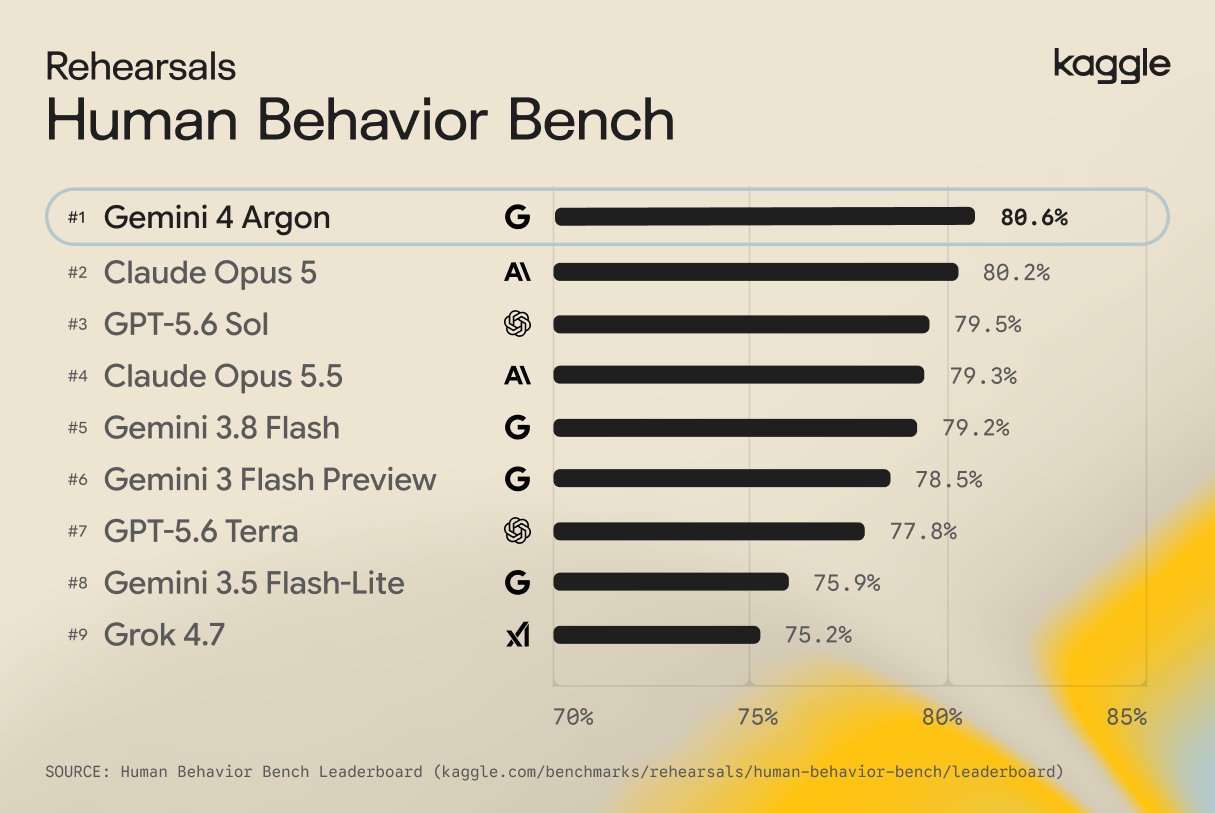
Can frontier models actually predict how real people behave? 🕺 Today, in collaboration with @RunRehearsals, we are launching Human Behavior Bench, the first public benchmark that tests whether AI can understand human preference and everyday decision-making. AI models have gotten increasingly good at coding, but knowing for whom to build is the next frontier of challenges for AI models to capture. Human Behavior Bench evaluates models on predicting real human behavior across health, entertainment, recreation, values, and consumption. To build this baseline, we gathered ground truth data directly from real people and evaluated models across a wide range of everyday scenarios: • Ground truth baseline: 1,244 US adults surveyed (June-Sept 2026) • Some cohorts are traditional demographic indicators such as age, income, and location • Other filters are behavioral e.g. GLP-1 patients and recent car buyers • 750 cases total (149 public / 601 private) across finance, health, recreation, values, and consumption • Scored using 1-TVD (total variation distance) Base models still have a significant gap to close to accurately predict human behavior by cohort. LLMs’ predictions tend to converge towards the mean, while the true distribution of human preferences vary greatly. Against a human noise ceiling of ~93, the current leaderboard scores are: Rehearsals’ Engram 1.0 (AI Twins) tops the leaderboard at 94.1%, followed by Gemini 4 Argon at 80.6% Claude Opus 5 at 80.2%, GPT-5.6 Sol at 79.5%.