deepseek-v4.1IMAGE
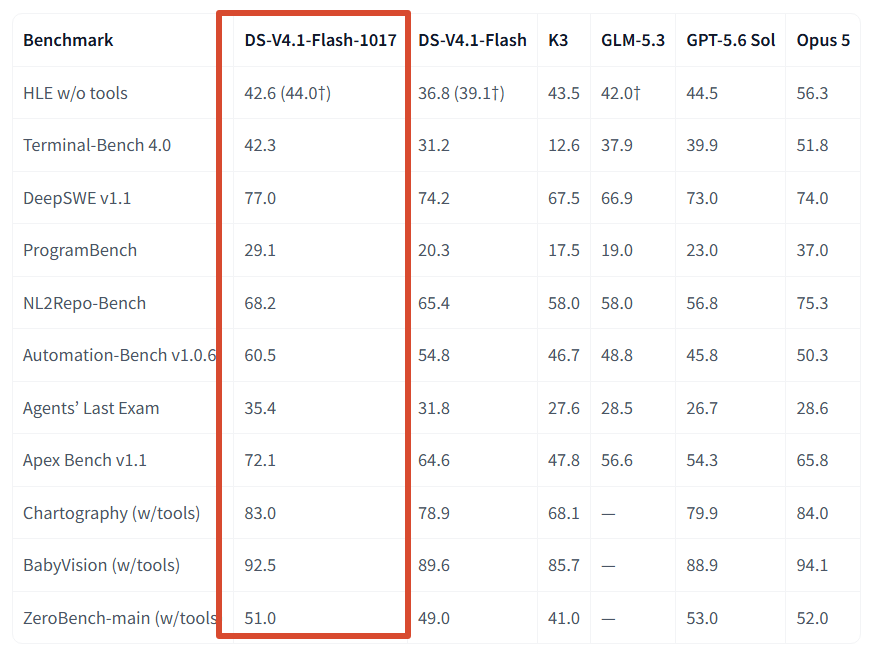
V4.1-Flash-1017 official scores: Terminal-Bench up 11.1, DeepSWE at 77.0
Terminal-Bench 4.0 rose 31.2 to 42.3, ProgramBench 20.3 to 29.1 and DeepSWE v1.1 74.2 to 77.0, above GPT-5.6 Sol's 73.0 and Opus 5's 74.0, with shorter task time and output; the author cautions against calling it a total sweep.
Kalenr
@kalenr3Archived 10 days agoOriginally posted 2026.10.17
Kalenr @kalenr3Originally posted 2026.10.17
🚨 DeepSeek V4.1 Flash 1017来了!官方称是一次小更新,几项成绩涨得可不小 关键变化: 🔹 Terminal-Bench 4.0:31.2 → 42.3,提高11.1分。 🔹 ProgramBench:20.3 → 29.1,提高8.8分。 🔹 DeepSWE v1.1:74.2 → 77.0。官方对比表里,这项成绩高于GPT-5.6 Sol的73.0和Opus 5的74.0。 🔹 推理、Agent任务、视觉评测也有提升;官方称任务耗时和输出长度同时减少 这次值得关注的组合:能力上去,单价不变,干活还更省时间和输出 至于能不能全面替代你现在的模型,得拿自己的任务试过再说 这张表还支持不了“全面碾压” 先把之前卡住它的任务再跑一遍,看看1017能不能过关 #DeepSeek #AI #大模型 #DeepSeekFlash #LLM #梁文峰 #大胖鱼 #梁圣
This post quotes another post: x.com/deepseek_ai/status/2111375640717033777
x.com/kalenr3/status/2111386540027085268Archived 2026.10.18 16:48