Running Jev-style decision models locally: Laya reports 8–10ms on RTX 4090
Someone brought Jev-style decision models to local hardware, taking text or JSON in and returning structured decisions, with Laya reporting about 8–10ms for 5 questions on an RTX 4090.
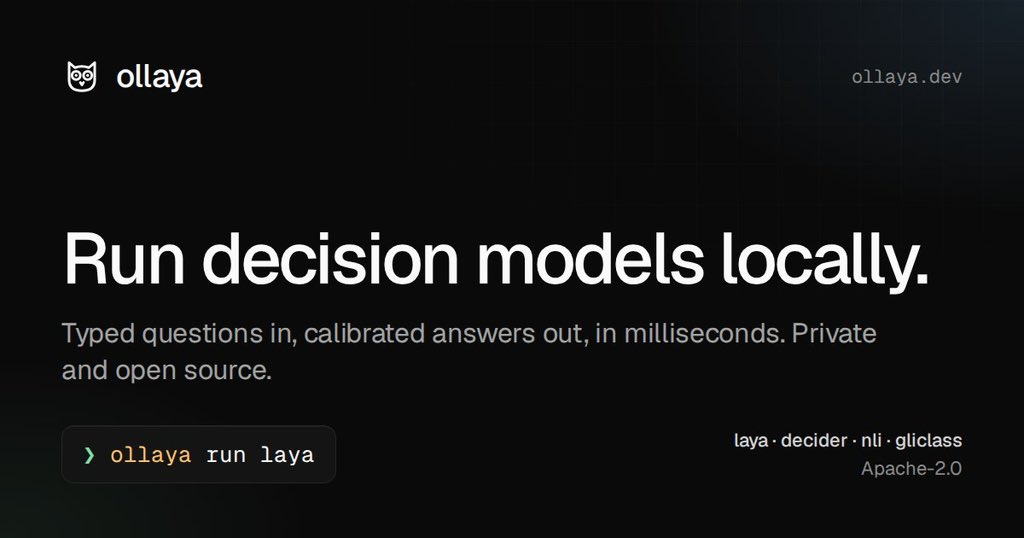
Ollama just got a new job run decision models locally Ollaya is basically bringing the Ollama idea to Jev-style decision models text or JSON in typed decision out no token-by-token generation Laya reports ~8–10ms for 5 questions on an RTX 4090 but here’s the catch Jev’s API is already so cheap that I’ve been using it a lot and still haven’t burned through my $5 so local isn’t automatically better the interesting part is that decision models are becoming something you can run, own and customize yourself LLMs had their Ollama moment decision models might be having theirs now