366GB DeepSeek V4.1 Flash streams on one RTX PRO 6000 at 85–95 tok/s
KireiStudios built the tierstream GPU weight-streaming library on mlx-stream's idea, running the 366GB model on 96GB VRAM at ~85–95 tok/s on code and ~100 tok/s in Spanish with token-identical output.
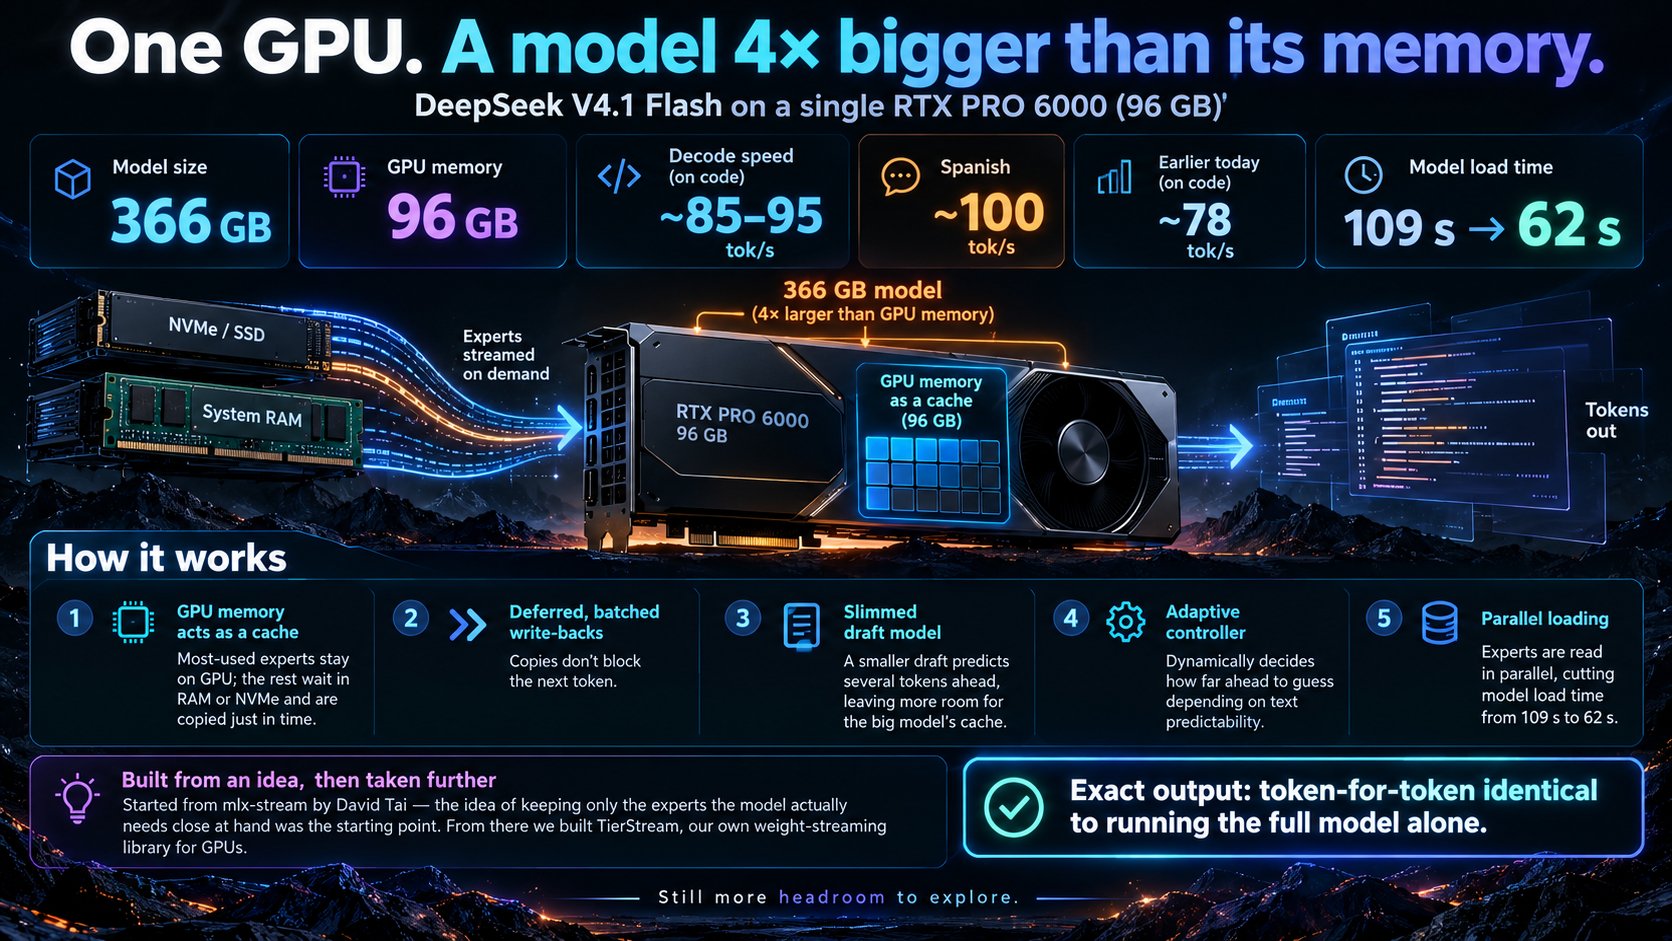
Included on that image is another test with just one GPU, loading a model 4x bigger than its memory. DeepSeek V4.1 Flash is 366 GB. We’re running it on a SINGLE RTX PRO 6000 (and now at 83% power limited) with 96 GB, at ~85–95 tok/s on code and ~100 tok/s in Spanish. The implementation started from mlx-stream by @TheDavidTai , a plugin that streams DeepSeek’s experts from SSD on Apple silicon. His idea of only keeping the experts the model actually needs close at hand was our starting point, and we built tierstream around it, our own weight-streaming library for GPUs: • The GPU memory works as a cache: the most-used experts stay on the GPU, the rest wait in RAM (or on NVMe) and get copied in just in time. • Write-backs are deferred and batched, so copies don’t get in the way of the next token. • A small draft model guesses several tokens ahead and the big model checks them in one pass. We slimmed the draft down to its most-used experts to leave more room for the big model’s cache. • An adaptive controller decides how far ahead to guess, depending on how predictable the text is. • Loading reads the experts in parallel: 109 s → 62 s. And the output is exactly the same as running the big model alone, token for token. Earlier today we were at ~78 tok/s on code; there’s still headroom for improvement!
This post quotes another post: x.com/kireistudios/status/2114496362490503556