Jev routes semantic decisions 200x faster than the main model
TypeSafe's Jev decision engine returns typed answers for non-generative judgments in AI loops such as routing, relevance and risk checks, and is claimed to be 200x faster and 400x cheaper.
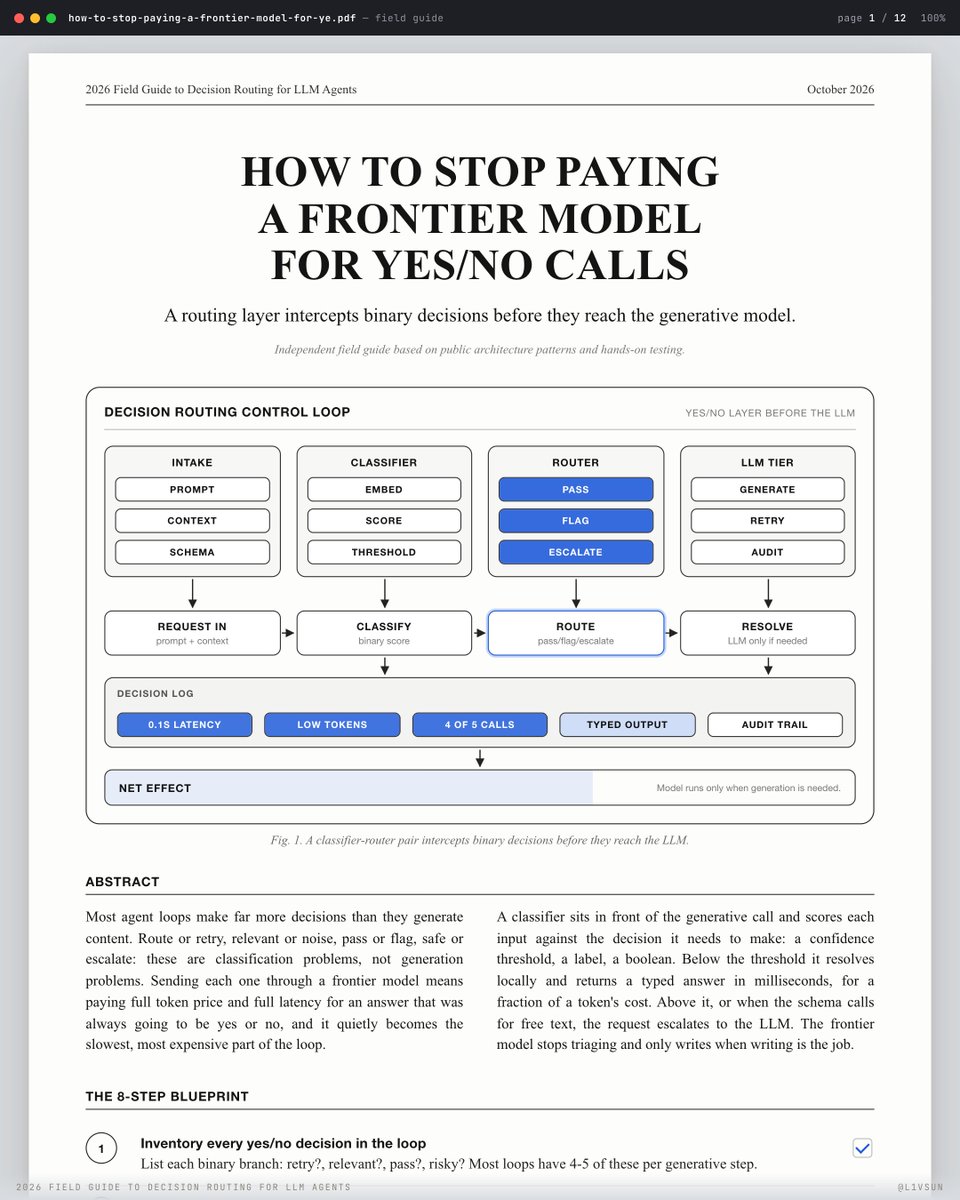
you're running a frontier model to answer yes/no questions that's not a model problem, it's a routing problem - and Jev just solved it Jev is a semantic decision engine from TypeSafe - returns typed answers in ~0.1s, costs almost nothing per call it handles every decision that doesn't need generative output not a chatbot, not a wrapper around gpt - a dedicated layer between your prompt and your LLM diogo almeida (jev founder) dropped numbers this week: > 200x faster on decisions that used to hit the main model > 400x cheaper per call on same workload > model finally does only the work it's built for 5 decisions happen on every AI loop. only 1 writes code or generates output jev handles the other 4: route or retry? relevant or noise? pass or flag? high risk or auto-proceed? bottleneck was never claude or gpt it was routing calls you kept sending to a $20/1M token model because you had nothing else teams using jev look like they have a faster model. they don't - they just stopped paying a surgeon for triage
This post quotes another post: x.com/l1vsun/status/2105630781578125651