DeepSeek V4.1 Flash 1017 benchmarks: DeepSWE 77 beats Opus 5, KV down to 890 bytes/token
Vendor-reported scores show Terminal-Bench 4.0 rising from 31.2 to 42.3 and DeepSWE at 77.0 versus Opus 5's 74.0, while tool-free HLE lags at 42.6; FP4 KV cache plus CSA2 cuts KV to about 890 bytes per token.
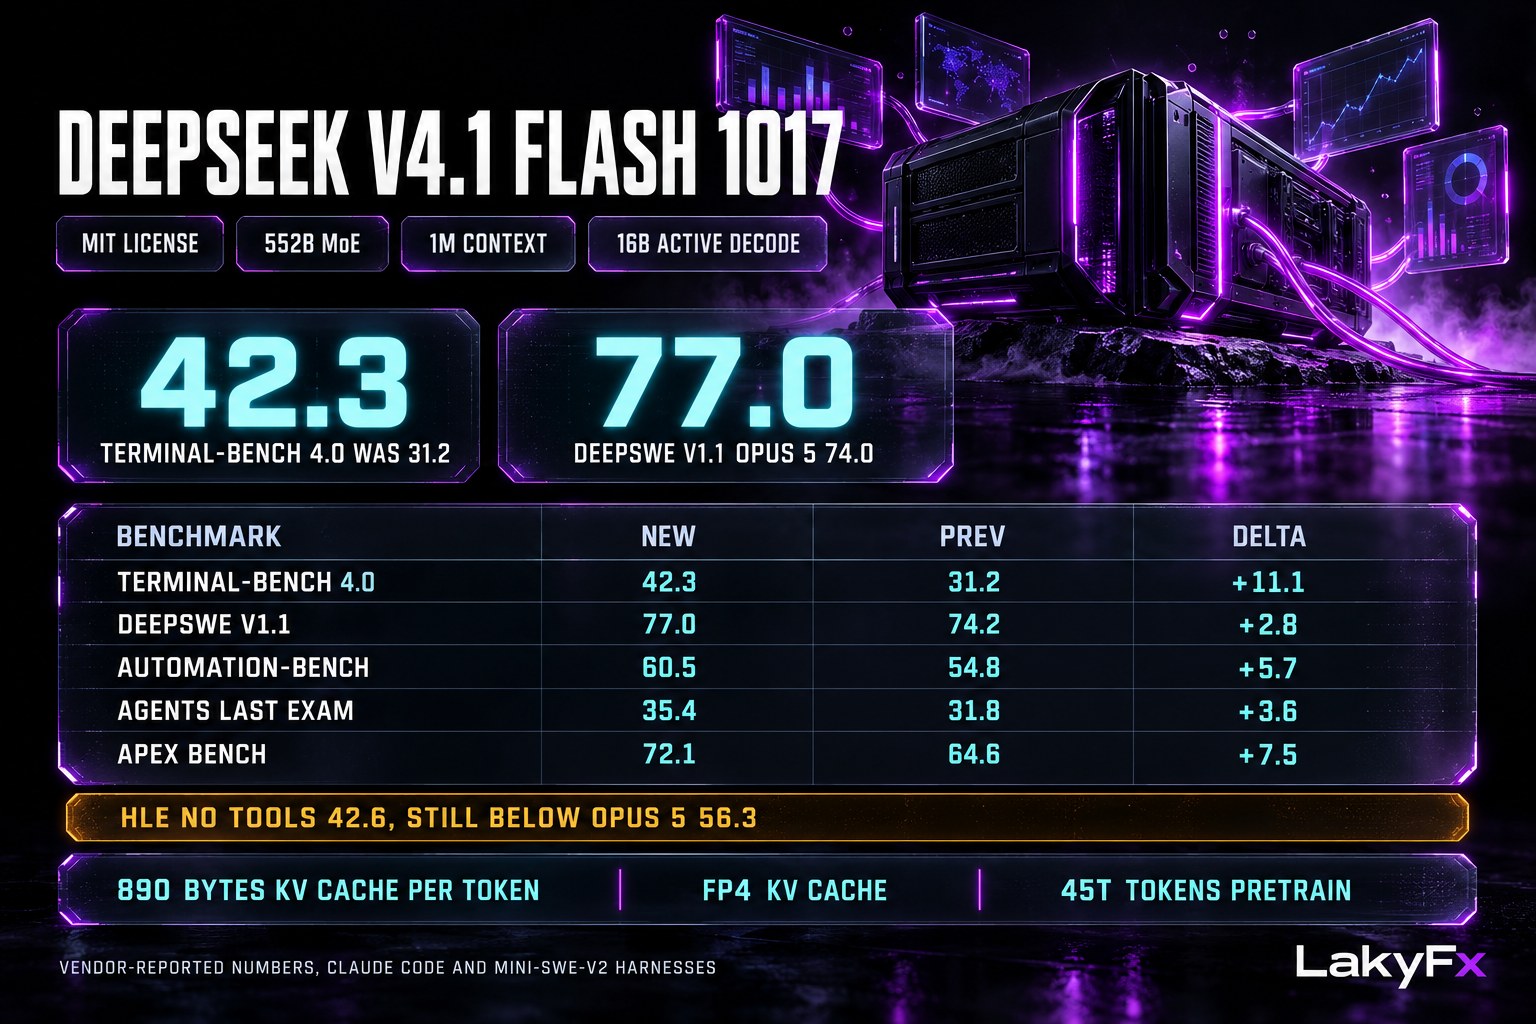
DeepSeek shipped a point release yesterday that moves the open-weight frontier on agentic benchmarks: DeepSeek-V4.1-Flash-1017, MIT licensed, weights on Hugging Face. It is a "minor update" to V4.1-Flash, a 552B-parameter MoE (8B active per token during prefill, 16B during decode) with 1M token context. The agentic scores move a lot: • Terminal-Bench 4.0: 42.3 (previous version: 31.2) • DeepSWE v1.1: 77.0 (Opus 5: 74.0, GPT-5.6 Sol: 73.0) • Automation-Bench: 60.5 (was 54.8) • Agents' Last Exam: 35.4 (was 31.8) • Apex Bench v1.1: 72.1 (was 64.6) Not universal: on HLE without tools it scores 42.6, behind GPT-5.6 Sol (44.5) and Opus 5 (56.3). All numbers are vendor-reported, measured in third-party harnesses (Claude Code for Terminal-Bench, Mini-SWE-V2 for DeepSWE). What matters for self-hosting is the cost side: FP4 KV cache plus cross-layer attention reuse (CSA2) cut the global KV footprint to 890 bytes per token, about 1/4 of V4-Flash, and DeepSeek says this update also shortens execution time and output length per task. One tooling caveat: no Jinja chat template, the release ships a Python reference encoder and a Rust toolkit instead. Weights and full table: https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 #LocalLLM #OpenSource #LLM #AI #Agents