Debate Benchmark: GPT-6 Astra trails GPT-5.6 Sol by 39 points
Fable 5.1 tops the new Debate Benchmark, GPT-6 Astra lands mid-table below GPT-5.6 Sol, and GLM-5.3 and Hy4 show large gains.
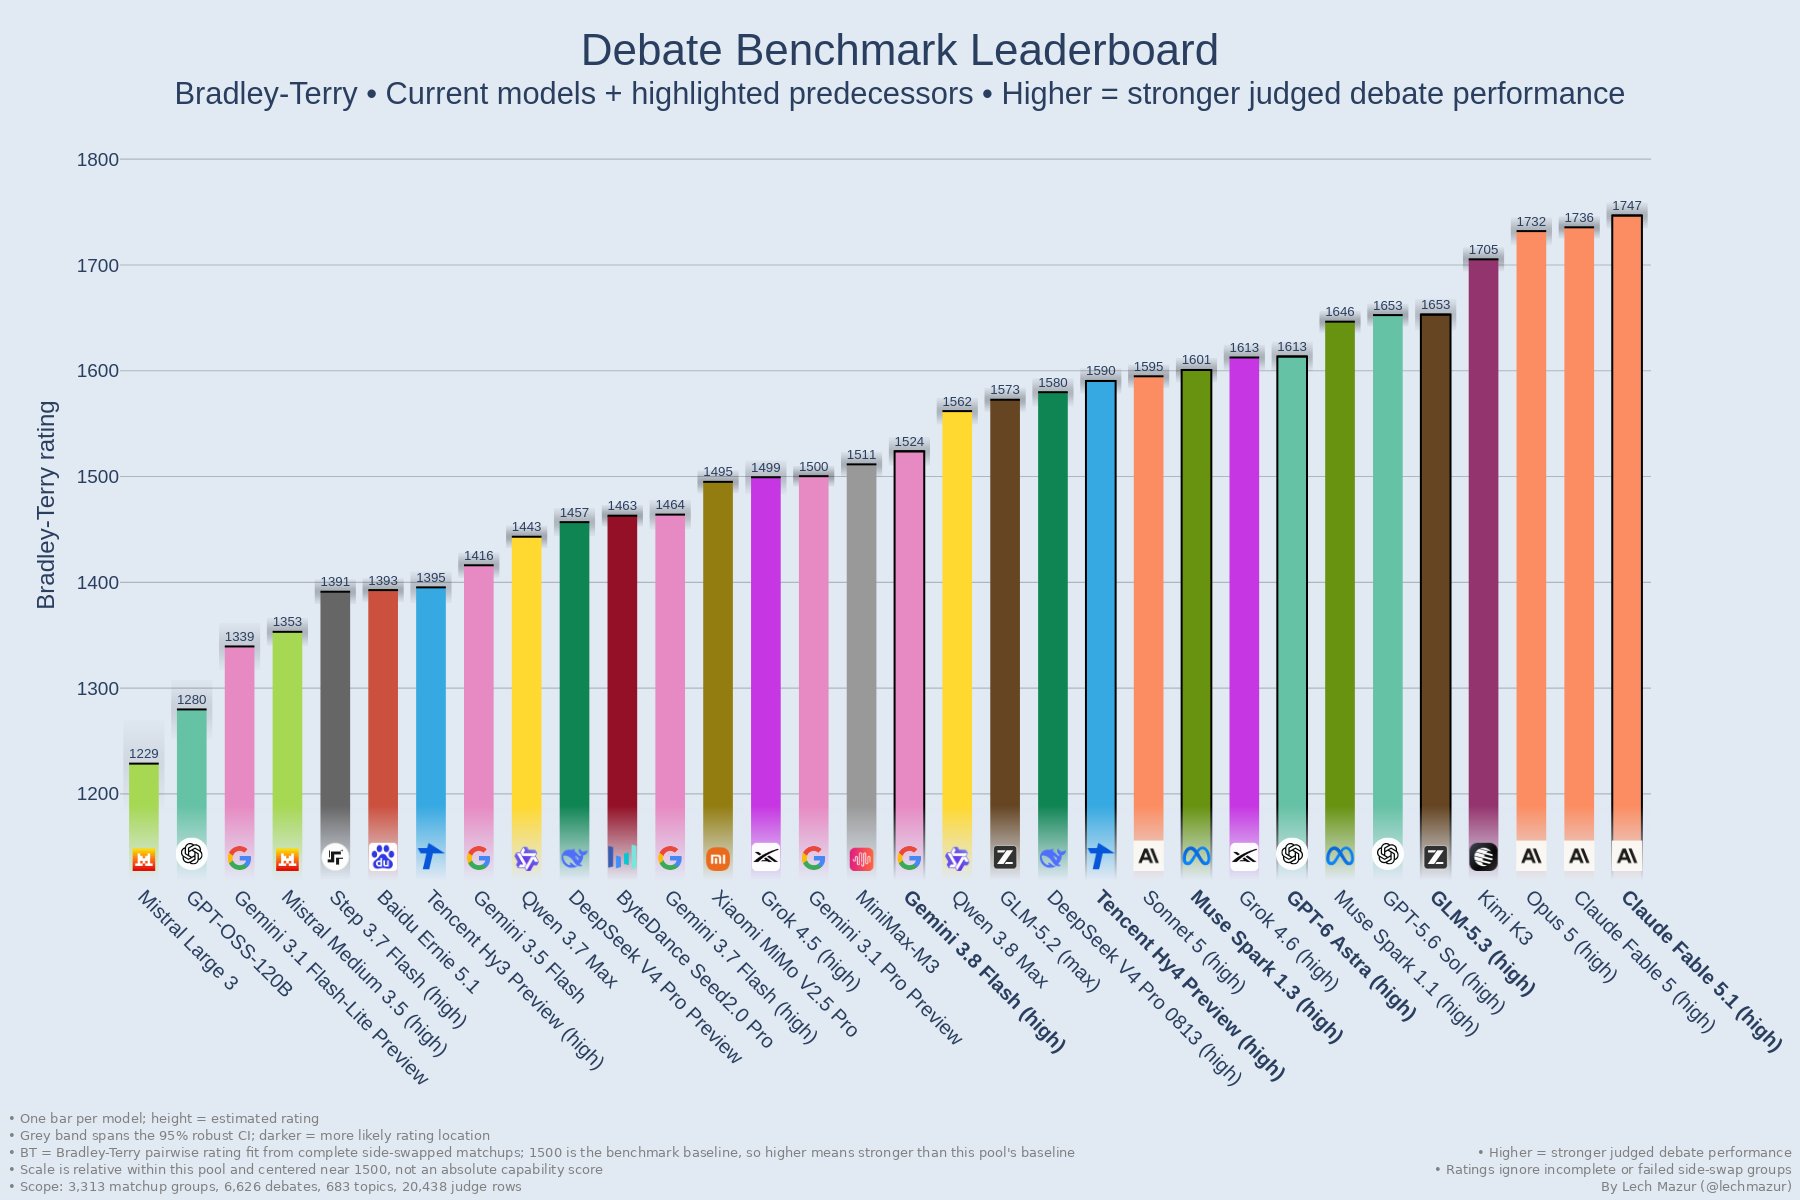
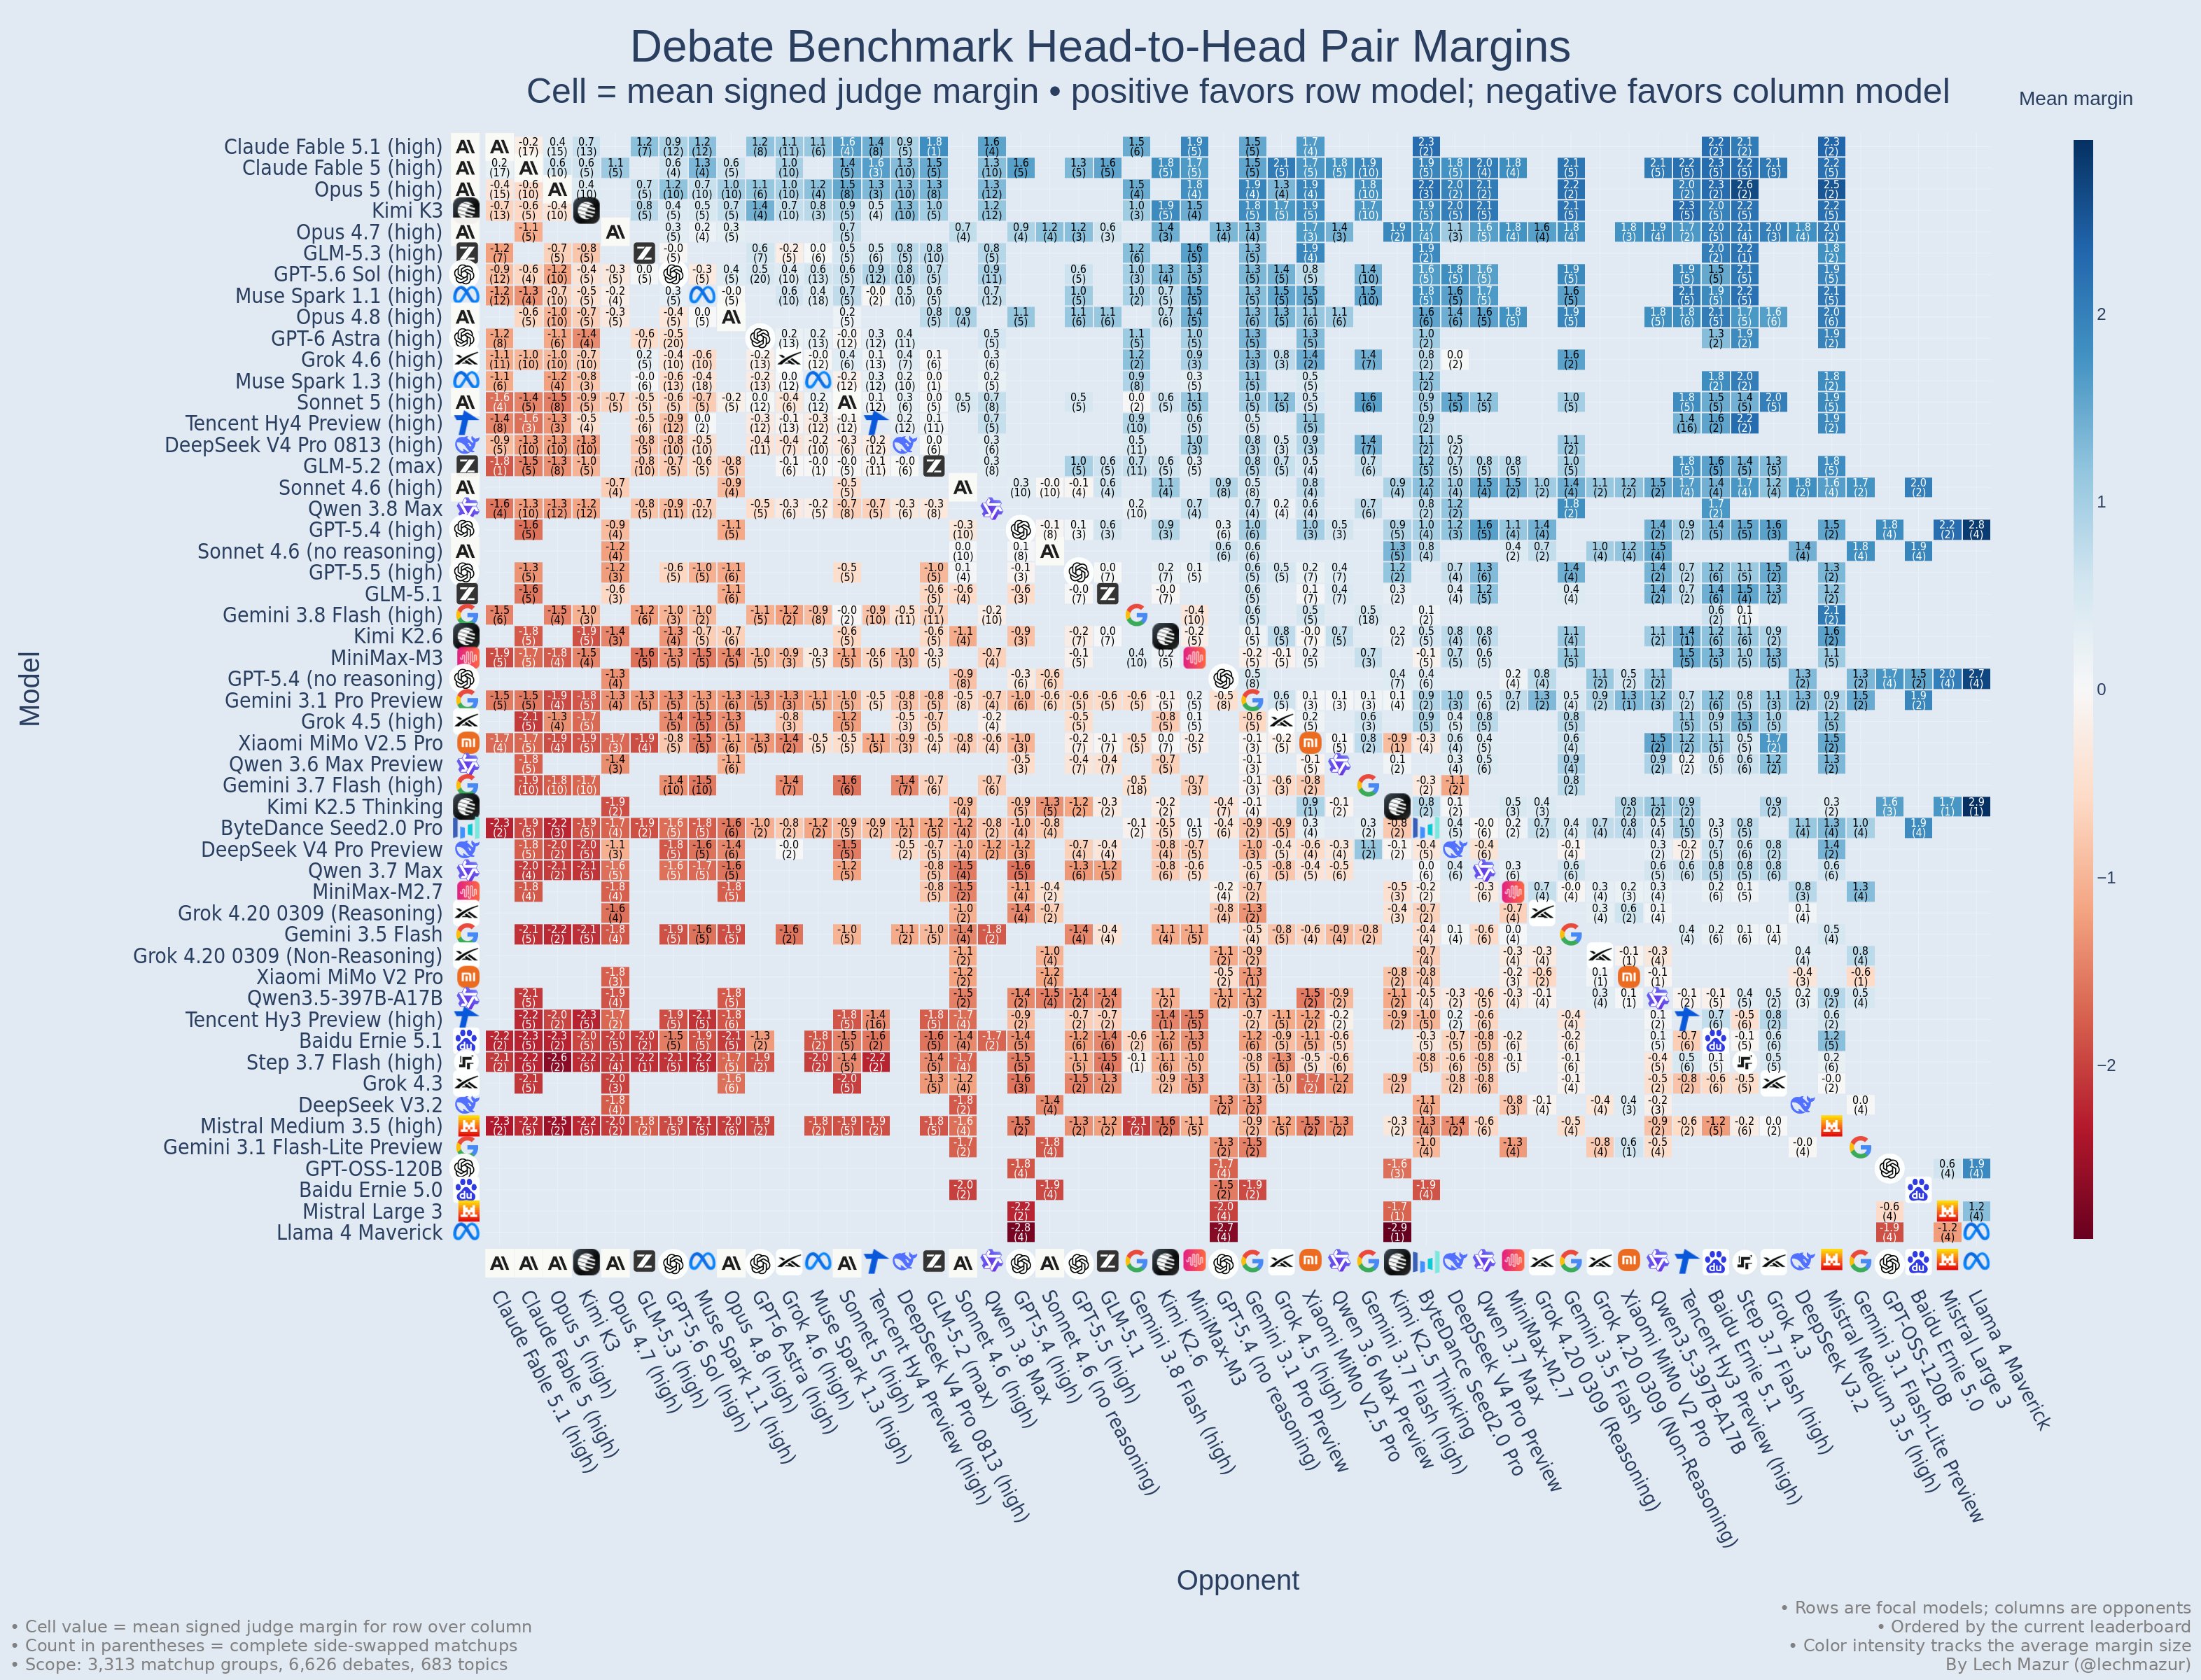
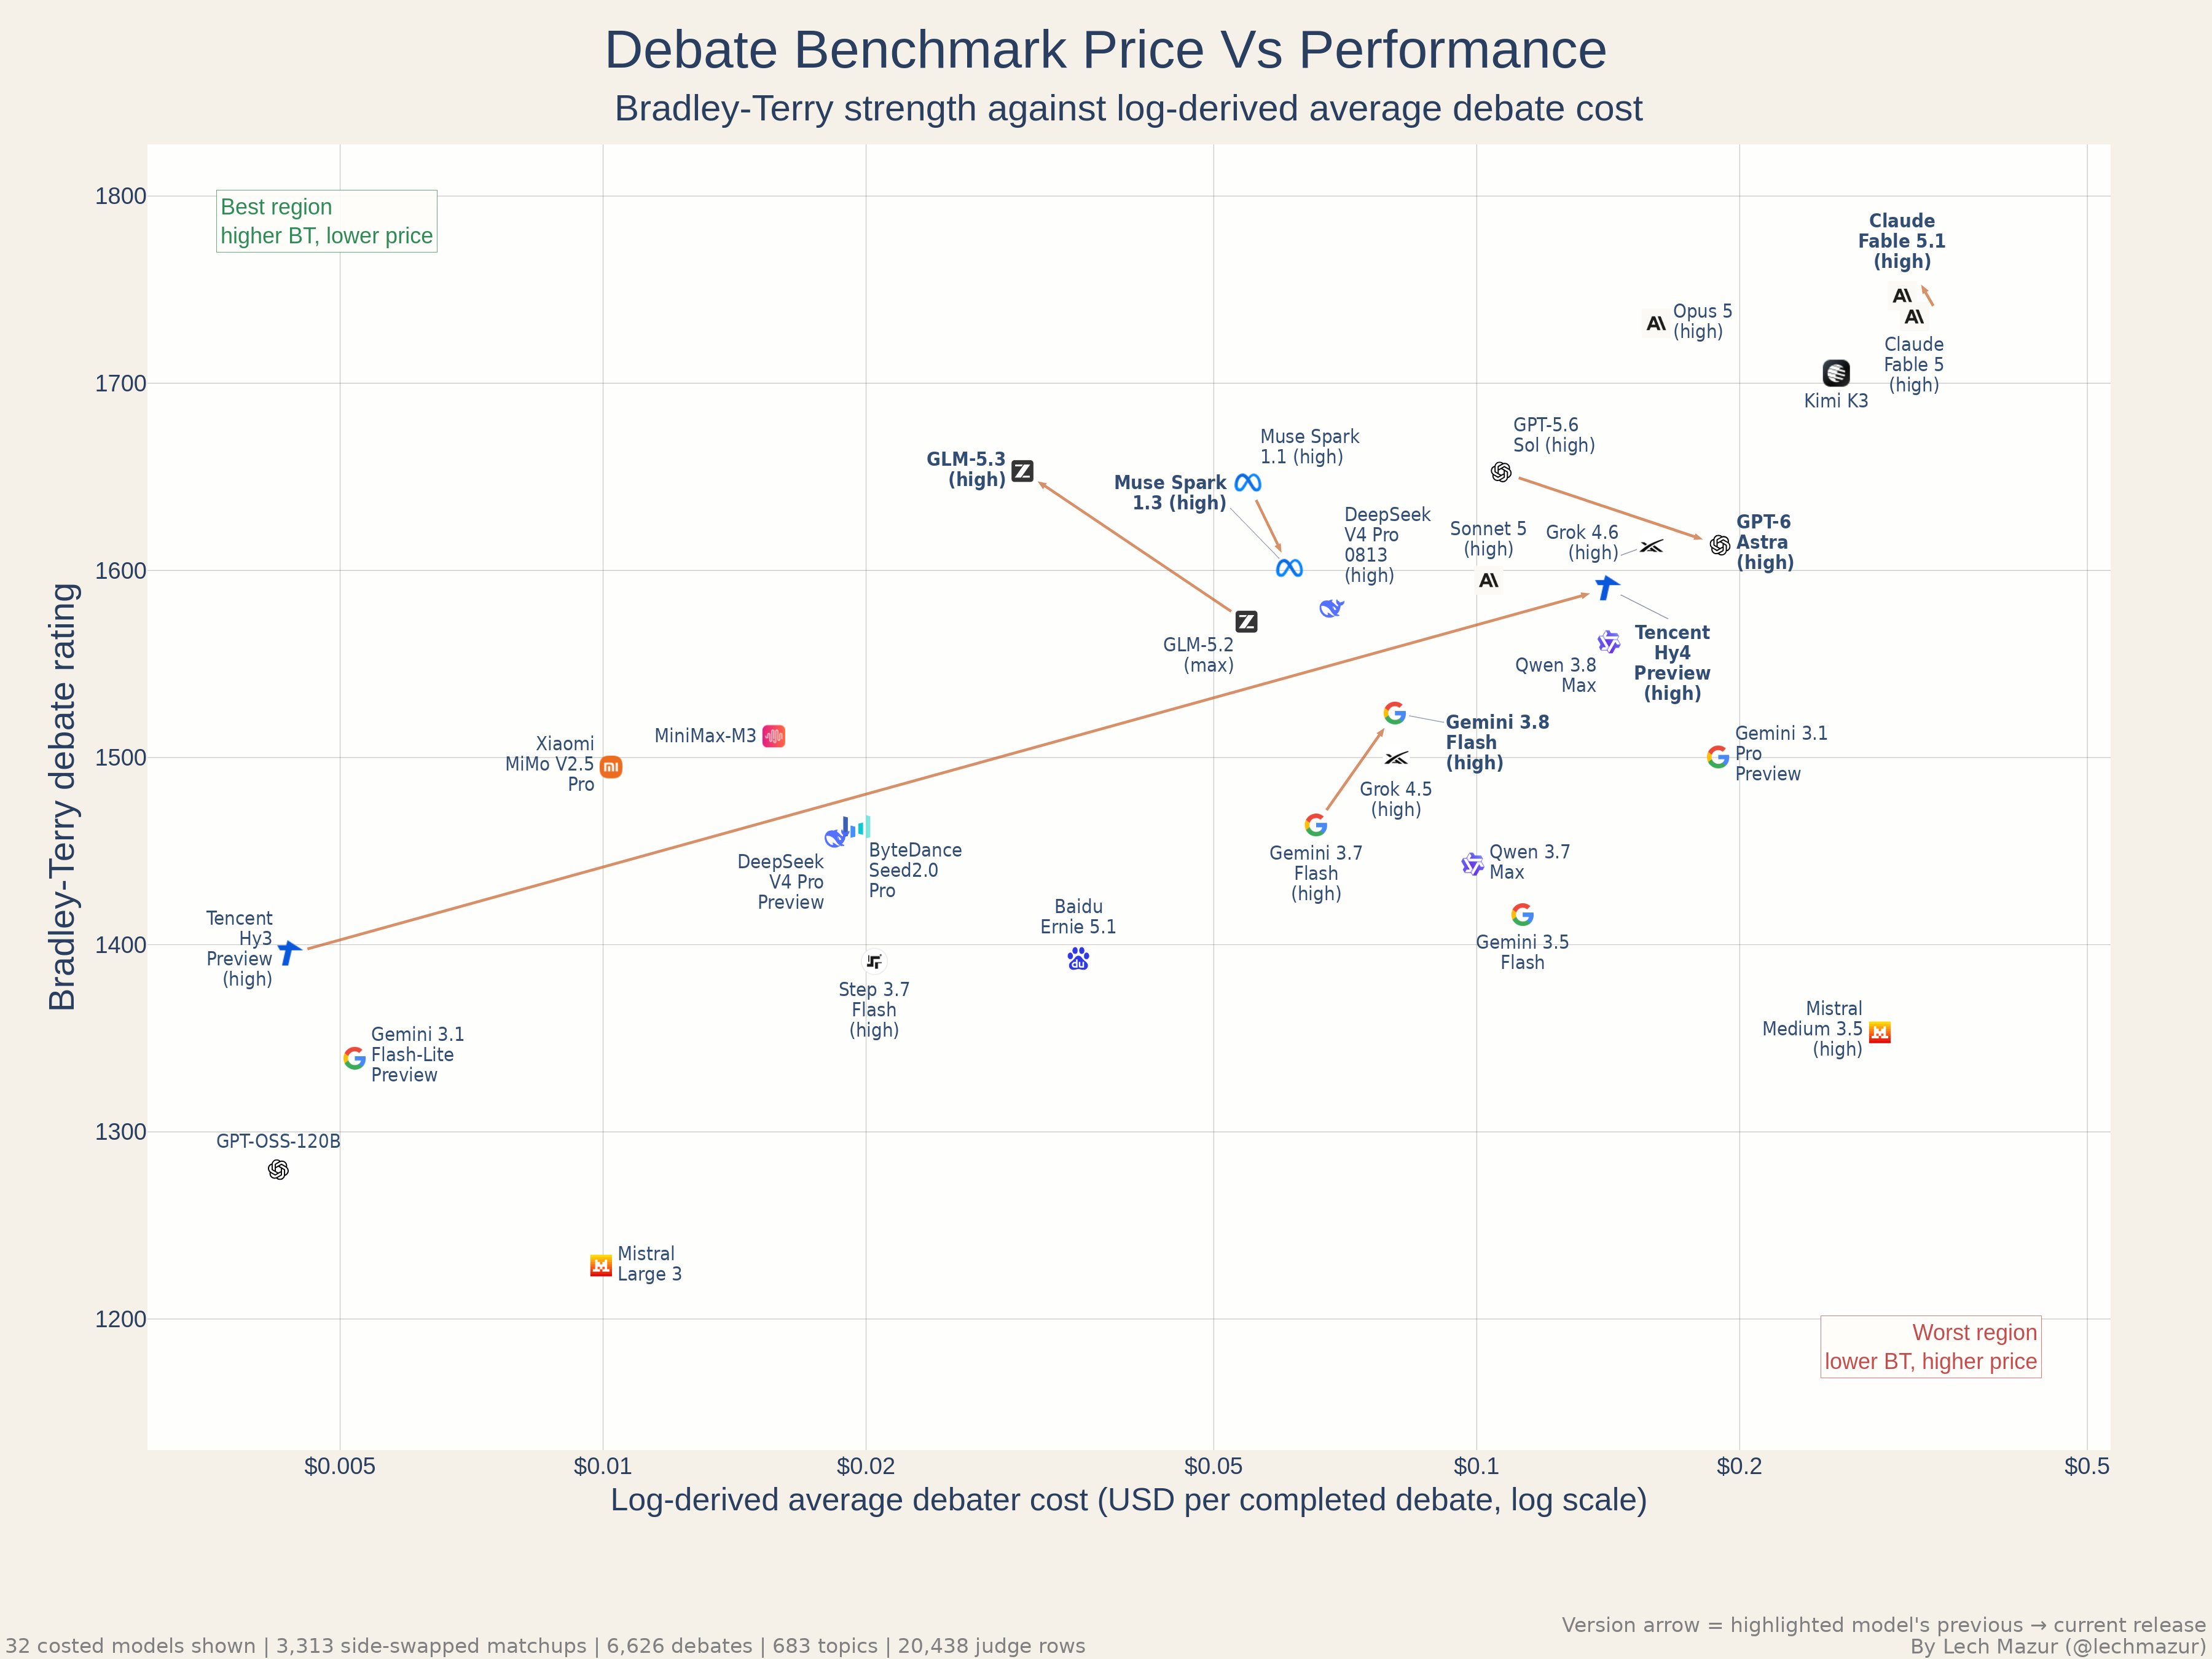
Fable 5.1 is the new Debate Benchmark Champion (+11 vs Fable 5)! 🏆 GPT-6 Astra lands below GPT-5.6 Sol (−39). GLM-5.3 (high) debuts at #4 among current models. It gains 80 points over GLM-5.2 max: 1573 → 1653. Hy4 Preview delivers the biggest generational leap: 1395 → 1590 (+195). Gemini 3.8 Flash also advances over 3.7: 1464 → 1524 (+60). Muse Spark 1.3 trails 1.1 by 46. Debate Benchmark tests how well models defend a position through sustained, adversarial, multi-turn opposition across hundreds of topics. It demands broad knowledge, factual accuracy under pressure, sharp rebuttals, and arguments that hold together round after round. Every matchup runs twice on the same motion, with PRO and CON swapped to control for side advantage. Three judges from distinct model families independently evaluate each debate’s winner and margin. More info: https://github.com/lechmazur/debate